

KobiMusic Dettato 9 benchmark composite F1 comparison (Apache 2.0)
Share this post:
Dettato Audio to MIDI: Open Source Film Scoring AI
AI music generators can deliver compelling temp cues in seconds, yet filmmakers and composers hit a brick wall when they need to change one viola chord, shift tempo for a picture re edit, or swap synthetic strings for a real orchestral library. Dettato (kobimusic/dettato), released in late October 2026 under the Apache 2.0 license, bridges that gap by turning any band, orchestra, piano, or vocal recording into editable multi track performance MIDI. At just 15.3M parameters (plus 5.0M for dettato-drums), Dettato scores 59.2 composite F1 across nine public benchmarks, beating the 1.3B parameter MuScriptor model (45.1 F1) by 14 points while running 65 times smaller. You can test this open source model free in your browser below with zero login.
Studio availability. Try the public Hugging Face demo below; Dettato is not part of a paid AI FILMS Studio plan (use ACE-Step 1.5 Lyrics to Music in the audio workspace for example instead).
Try Dettato Audio to MIDI Live
Upload a temp score cue, piano improvisation, or AI generated music clip into the public Hugging Face Space below to inspect its piano roll and download editable MIDI tracks.
Architecture and Technical Design
Dettato achieves high accuracy at tiny size by using a pitch equivariant lane network rather than a massive generic audio transformer. Every one of the 88 piano keys forms its own parallel lane running shared weights, so harmonic patterns learned around middle C generalize automatically across the entire register.
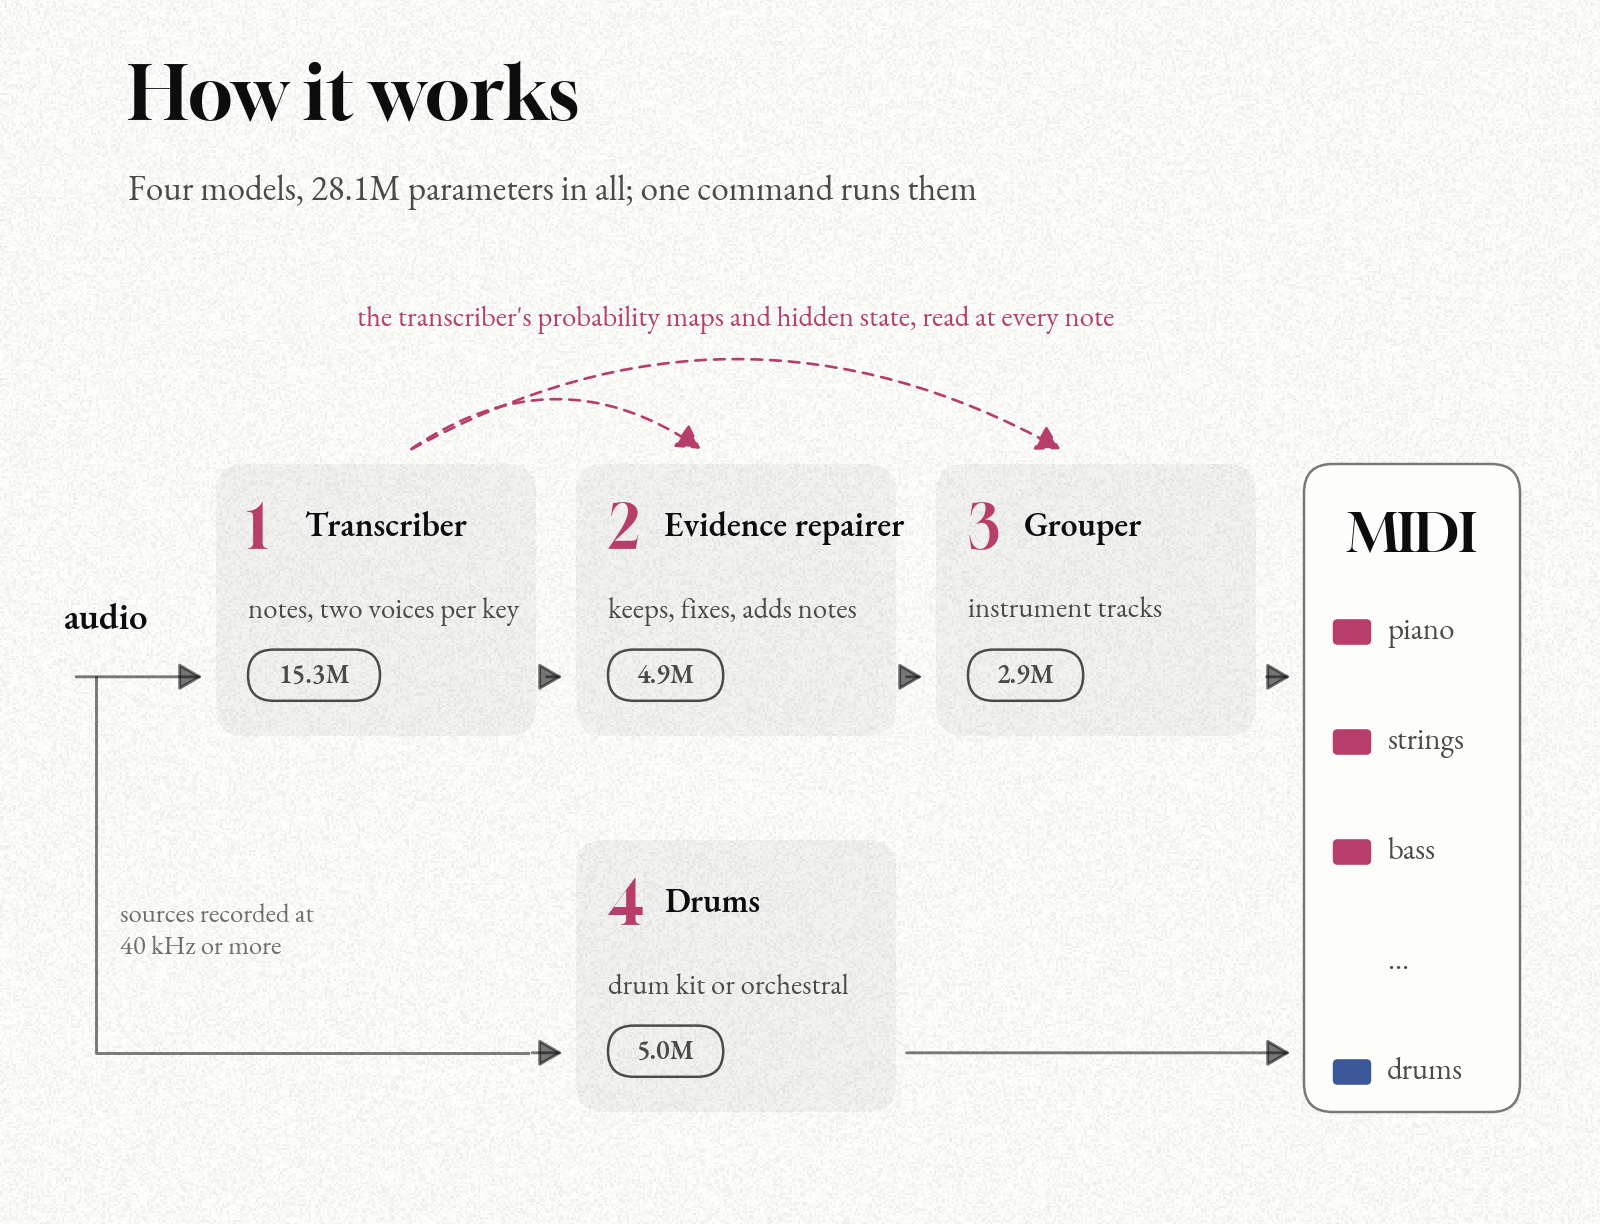
Dettato four model transcription pipeline by KobiMusic, Apache 2.0
The front end computes a harmonic log frequency spectrogram from 16 kHz audio at 3 bins per semitone from A0, stacking harmonic channels from 0.5x to 7x plus a short window channel for sharp transients. A 15 block ConvNeXt trunk (368 channels at 40 ms steps) mixes harmonic intervals at 1, 2, 12, 19, 24, 28, and 31 semitones, paired with axial pitch/time attention and a bidirectional GRU per lane.
Output heads predict onset, frame, and offset probabilities at 20 ms resolution with two independent voice slots per key, capturing overlapping unison notes played by two instruments simultaneously. The full system chains four Apache 2.0 models: dettato, dettato-evidence, dettato-grouper (instrument track separation), and dettato-drums.
Across the nine benchmark suite (Bach10, Dagstuhl ChoirSet, PHENICX-Anechoic, five RWC datasets, and Slakh2100 test), Dettato reaches 67.2 onset F1, 77.9 frame F1, 44.8 offset F1, and 47.1 drum F1. On the three sets reported by closed commercial model Mirelo A2M v1.1 Pro, Dettato scores 60.8 against Mirelo's 56.1.
Every transcribed note retains its exact onset probability as a confidence score, letting composers filter out quiet bleed or ghost notes cleanly inside a DAW. Because Dettato outputs unquantized performance MIDI, natural rubato, orchestral swells, and human micro timing survive intact instead of snapping rigidly to a mechanical metronome.
Audio is evaluated in overlapping 8 second windows spaced 2 seconds apart with Hann window blending, eliminating boundary glitches on long film cues.
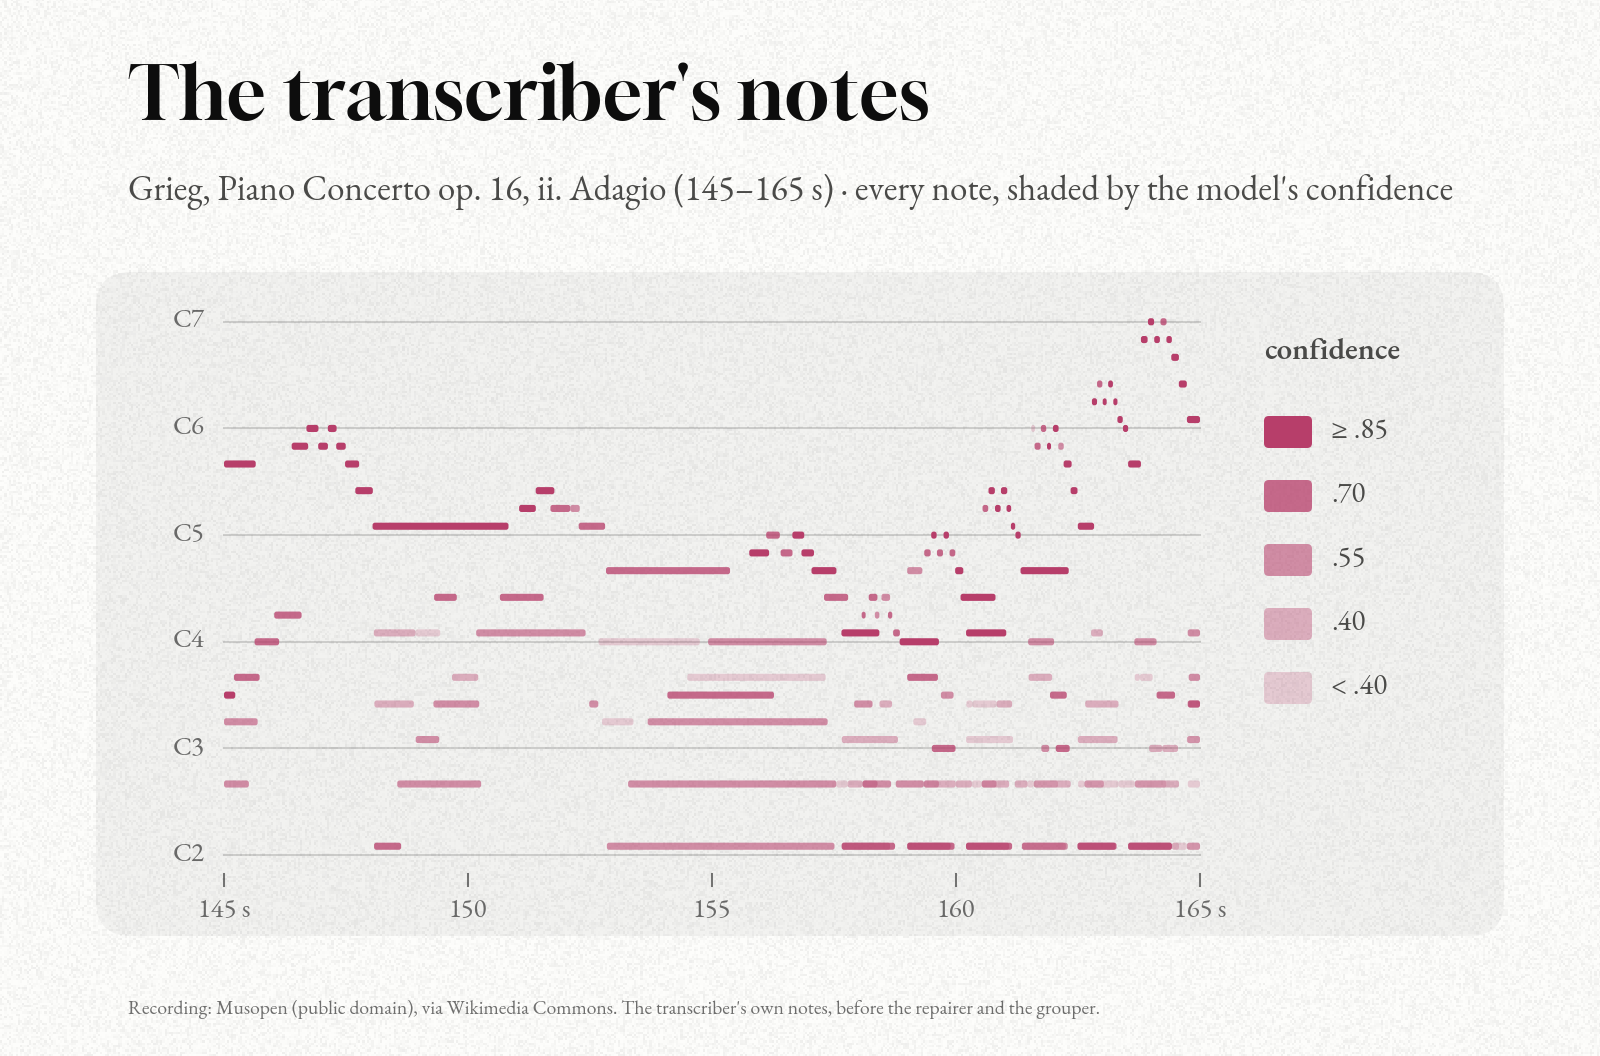
Grieg piano concerto note transcription shaded by confidence by KobiMusic, Apache 2.0
Hardware, VRAM, and License Matrix
| Model Component | Parameters | Typical Hardware | Speed | License | Intended Use |
|---|---|---|---|---|---|
kobimusic/dettato (Transcriber) |
15.3M | CPU or any 2 GB+ GPU | Faster than real time on GPU | Apache 2.0 | Pitched 88 key 2 voice note extraction |
kobimusic/dettato-drums |
5.0M | Shared footprint | Real time / faster | Apache 2.0 | General MIDI drum kit onset transcription |
kobimusic/dettato-grouper + evidence |
Compact companion models | Shared footprint | Fast post pass | Apache 2.0 | Splitting notes into separate instrument MIDI tracks |
All four checkpoints and the dettato CLI package ship under Apache 2.0, permitting unrestricted commercial studio and DAW integration.
Parameter Reference
| Decode Setting | Default Value | Musical Effect |
|---|---|---|
| Input Sample Rate | 16 kHz |
Internal harmonic spectrogram resolution |
| Window / Hop | 8 s window, 2 s hop |
Hann blended overlap avoids seam dropouts |
| Onset Threshold (Voice 1 / 2) | 0.25 / 0.30 |
Controls sensitivity for primary and unison notes |
| Frame Threshold | 0.40 |
Determines sustained note hold continuity |
| Offset Threshold | 0.30 |
Marks clean note release timing |
| Output Format | .mid + .json |
Multi track unquantized performance MIDI + confidence metadata |
Local Python and CLI Setup
Install the dettato package directly from GitHub and transcribe any WAV or MP3 cue to multi track MIDI in one terminal command.
pip install git+https://github.com/kobimusic/dettato
dettato temp_score_cue.mp3 -o ./midi_out/
To call the raw transcriber in Python and inspect note confidence scores programmatically:
from dettato.audio import load
from dettato.transcriber import Transcriber

transcriber = Transcriber.from_pretrained("cuda")  # or "cpu"
maps, _ = transcriber.run(load("temp_score_cue.mp3").at(16000))
notes = transcriber.notes(maps)
# notes dict keys: onset, offset (seconds), pitch (MIDI), conf, slot (voice 1 / 2)
print(f"Extracted {len(notes['pitch'])} pitched notes")
Filmmaker Production Playbook
- Turn AI temp tracks into editable DAW sessions. Generate fast musical ideas with StepAudio-3-Music, HeartMuLa, or ACE-Step 1.5 Lyrics to Music in AI FILMS Studio, then run Dettato to pull multi track MIDI into Logic Pro, Cubase, or Reaper and re voice the score with Spitfire or Vienna orchestral libraries.
- Filter by onset confidence on dense mixes. Heavy reverb and trailer percussion can trigger low confidence ghost notes. Use the exported
.jsonconfidence values to prune notes below0.35while keeping hero melodic phrases untouched. - Preserve human rubato for picture lock. Because Dettato exports performance MIDI without forced beat quantization, drag the
.midfile directly alongside your locked picture cut so every dramatic swell hits the exact frame of the original audio reference. - Run cleanly on CPU laptops in the edit bay. At 15.3M parameters, Dettato needs no workstation GPU, allowing assistant editors and composers to transcribe temp cues locally on any laptop.
Related Reading
- StepAudio-3-Music: Open Source 48 kHz Film Score AI
- HeartMuLa: Open Source Apache 2.0 Music AI
- ACE-Step 1.5: Open Source Music AI vs Suno v5
- Explore cloud film scoring models on the AI Text to Music Generator page.


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)