

Kling Team (arXiv:2506.19774) & FunAudioLLM PrismAudio (ICLR 2026, arXiv:2511.18833)
Share this post:
Kling-Foley & PrismAudio: Open Source Video to Audio AI
PrismAudio (Decomposed Chain of Thoughts and Multi-Dimensional Rewards for Video-to-Audio Generation, arXiv:2511.18833, accepted at ICLR 2026 by FunAudioLLM and Alibaba Group with weights at FunAudioLLM/PrismAudio) and Kling-Foley (Multimodal Diffusion Transformer for High-Quality Video-to-Audio Generation, arXiv:2506.19774) are two open research frameworks that synthesize frame accurate stereo sound effects, ambient soundscapes, and musical stems directly from silent video clips.
Studio availability. Kling-Foley and PrismAudio are not available in AI FILMS Studio. This article covers public research releases. To generate sound effects and video in the Studio, open the sound workspace or see the models listed on the Text to Video page.
Kling-Foley multimodal diffusion transformer generating synchronized mechanical, ambient, and impact audio tracks
Frame aligned foley synthesis matching fast on screen action and surface material collisions
How PrismAudio Uses Decomposed Chain of Thought RL (Fast-GRPO)
When a silent film scene contains overlapping action events, such as footsteps on wet gravel, distant thunder, and a car door slamming on the left side of the frame, single pass video-to-audio models often drop secondary sounds or blur transient impacts. Built on top of the open source ThinkSound (liuhuadai/ThinkSound) flow matching architecture, PrismAudio decomposes sound design reasoning into four specialized Chain of Thought (CoT) dimensions before synthesizing the 44.1 kHz stereo waveform.
- Four dimensional CoT planning. Given an input video, the multimodal planner reasons explicitly across Semantic (what objects collide), Temporal (exact onset/offset timestamps), Aesthetic (acoustic clarity and dynamic range), and Spatial (left and right stereo panning and room depth) dimensions.
- Multi dimensional reinforcement learning (
Fast-GRPO). To optimize the continuous flow matching audio generator alongside the discrete text reasoning planner without reward hacking, PrismAudio introduces Fast-GRPO. A hybrid ODE-SDE sampling schedule restricts stochastic exploration to critical denoising windows, cutting reinforcement learning training time while aligning each CoT dimension with its dedicated acoustic reward model.
Interactive Audio Sample: Chain of Thought Layered Foley Synthesis (ThinkSound / PrismAudio)
Generated 44.1 kHz stereo foley track synthesized from visual action cues and structured acoustic reasoning:
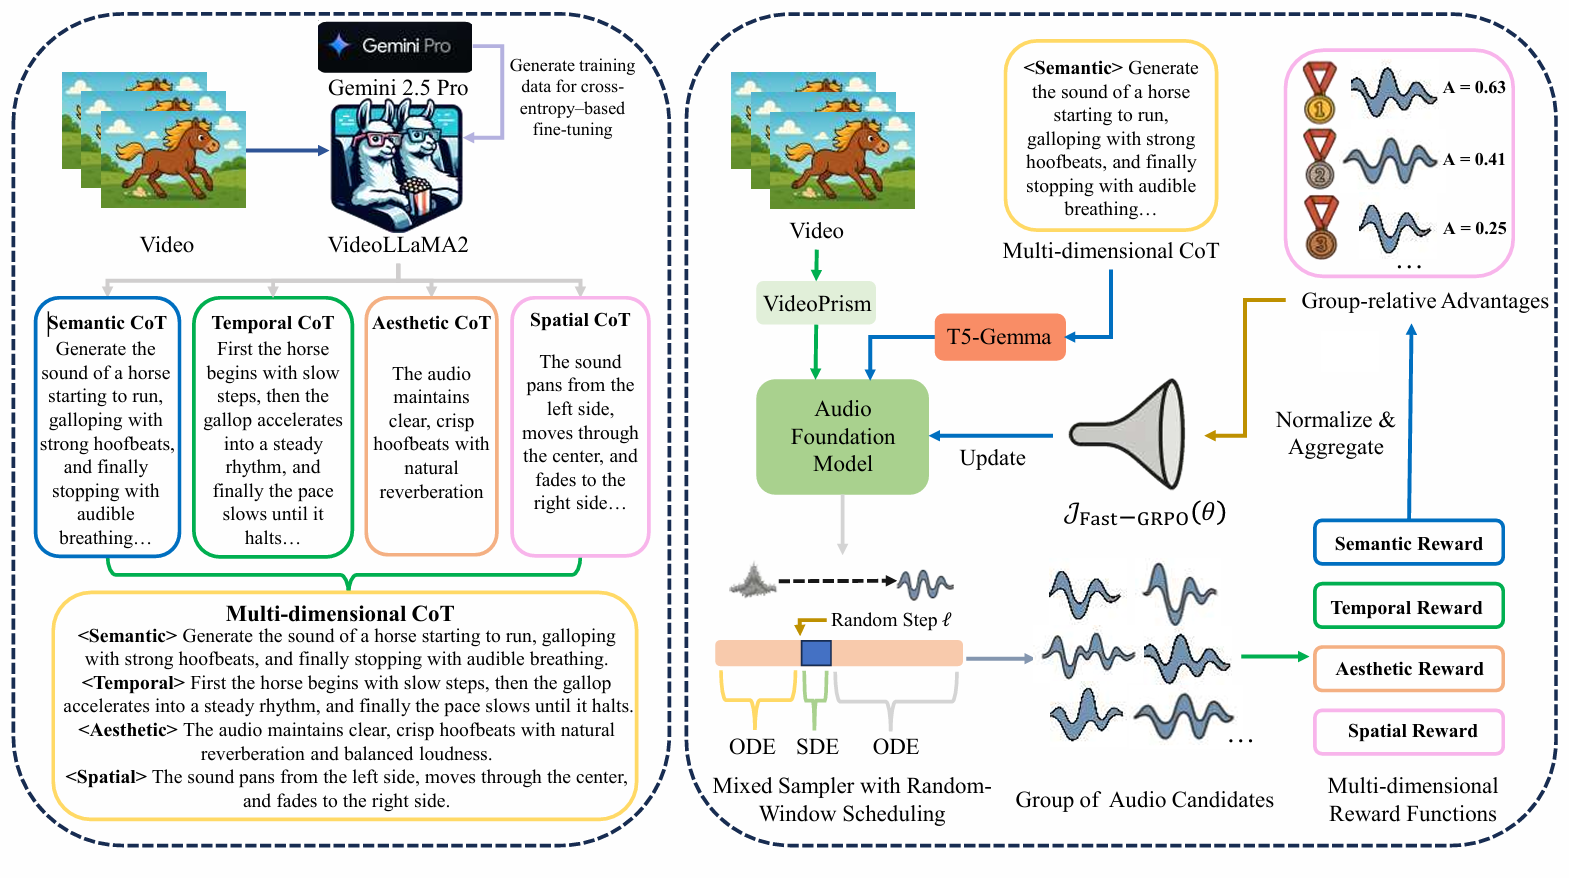
PrismAudio decomposes foley planning into Semantic, Temporal, Aesthetic, and Spatial Chain of Thought modules optimized via Fast-GRPO. Credit: Huadai Liu et al., FunAudioLLM (ICLR 2026).
Separating semantic event detection from temporal onset alignment prevents the audio generator from sacrificing frame synchronization when rendering rich environmental ambience.
Across the VGGSound and AudioCap evaluation suites, PrismAudio improves onset synchronization accuracy, stereo spatial imaging, and perceptual audio quality over single prompt V2A baselines.
How Kling-Foley Aligns Audio and Video Latents in MM-DiT
Kling-Foley pairs a Multimodal Diffusion Transformer (MM-DiT) with a high compression 1D audio Variational Autoencoder (VAE) and the open source klingfoley/Kling-Audio-Eval industrial benchmark (20.9 GB of curated multi category video and audio test pairs).
Visual features extracted at frame rate are temporally aligned with the 1D latent audio tokens inside joint multimodal attention blocks, while text embeddings provide global timbre and mood steering.
A dedicated stereo rendering stage converts the latent representation into dual channel 44.1 kHz audio so off center visual impacts pan accurately across the stereo field.
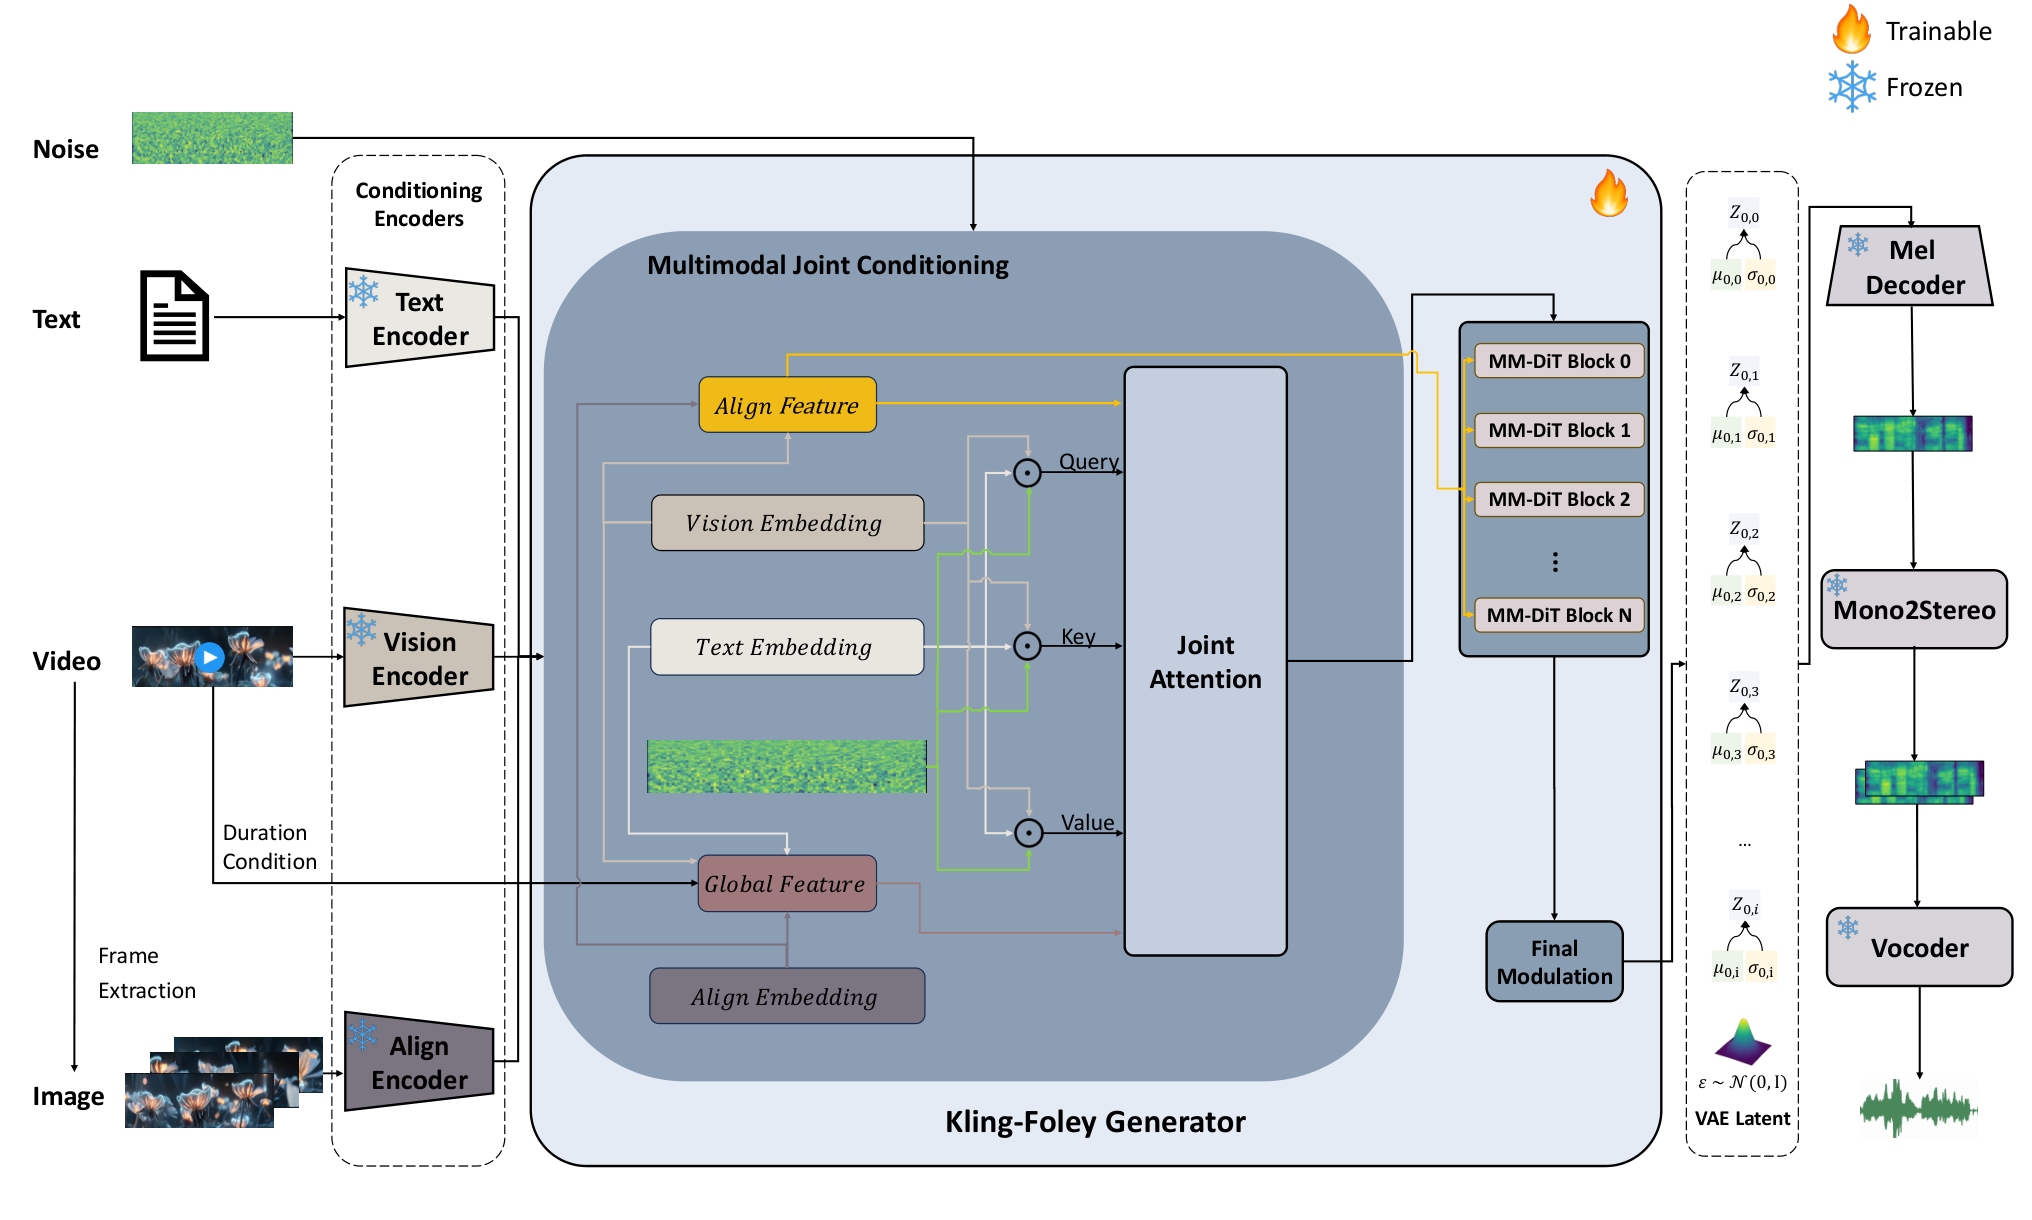
Kling-Foley MM-DiT joint video, text, and audio latent synchronization architecture. Credit: Kling Team (arXiv:2506.19774).
Hardware, VRAM & Model Comparison
| Model / Resource | Repository / HF ID | Core Architecture & Output | Hardware & VRAM | License / Status |
|---|---|---|---|---|
| PrismAudio | FunAudioLLM/PrismAudio (liuhuadai/ThinkSound) |
Decomposed CoT planner + Flow Matching Audio DiT (44.1 kHz stereo) | 12 GB to 24 GB VRAM | Apache 2.0 / Open Weights (ICLR 2026) |
| ThinkSound Base | liuhuadai/ThinkSound |
Chain of Thought interactive video-to-audio foundation model | 12 GB VRAM (supports Gradio & CLI batching) | Open Weights |
| Kling-Foley & Eval | klingfoley/Kling-Foley / Kling-Audio-Eval |
Multimodal DiT + 1D Audio VAE + 9 class industrial foley benchmark | Reference architecture & open evaluation benchmark | Open Benchmark & Paper |
Running PrismAudio and ThinkSound Locally
Clone the prismaudio branch of liuhuadai/ThinkSound, download the FunAudioLLM/PrismAudio checkpoints from Hugging Face, and run the single clip or batch foley generation script.
git clone -b prismaudio https://github.com/liuhuadai/ThinkSound.git
cd ThinkSound
conda create -n prismaudio python=3.10 -y
conda activate prismaudio
pip install -r requirements.txt

huggingface-cli download FunAudioLLM/PrismAudio --local-dir ./ckpts/PrismAudio

# Generate synchronized 44.1 kHz stereo foley for a silent video clip
bash scripts/demo.sh \
  --video_path examples/rain_footsteps_cut.mp4 \
  --cot_description "Semantic: Heavy leather boots stepping on wet cobblestone in rain. Temporal: Distinct footsteps at 0.4s, 1.1s, 1.8s, and 2.5s." \
  --output_dir ./outputs
Post Production Sound Design & AI FILMS Studio Workflows
Most open source video diffusion models (Wan 2.1, Flux-driven image-to-video pipelines, and 3D camera controllers) output silent .mp4 plates. Adding PrismAudio or ThinkSound as a downstream post processing stage automatically populates footsteps, cloth rustle, weather ambience, and prop impacts timed to the visual cut before final mix.
For related open source audio and foley guides, read our coverage of MOSS-SoundEffect V2.0 long form sound design, HunyuanVideo-Foley synchronized 48kHz audio, and AudioLDM2, Stable Audio Open, and MusicGen local foley.
To generate video, sound effects, voiceovers, and music directly in the browser, open the sound workspace, visit the Text to Video page, or chain video and audio generators inside the Nodes Graph Editor.


Sources
- FunAudioLLM/PrismAudio Checkpoints on Hugging Face
- PrismAudio Official Project Page (ICLR 2026)
- PrismAudio: Decomposed Chain of Thoughts and Multi-Dimensional Rewards for Video-to-Audio Generation (arXiv:2511.18833)
- liuhuadai/ThinkSound Official GitHub Repository (
prismaudiobranch) - klingfoley/Kling-Foley Official GitHub Repository
- Kling-Foley: Multimodal Diffusion Transformer for High-Quality Video-to-Audio Generation (arXiv:2506.19774)
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)