

NVIDIA NVlabs / Efficient-Large-Model, Open-H3-Regenerate-2K (MiniMax-H3 Community License)
Share this post:
Open-H3-Regenerate-2K: Open Source 2K & 4K Video AI
Open-H3-Regenerate-2K and Open-H3-Regenerate-2K-IC from NVIDIA NVlabs (Efficient-Large-Model) are open weights video refinement pipelines built on MiniMax-H3 that regenerate a 768p (1344x768, 121 frame) draft clip at 1080p, 2K (2560x1440), or 4K (3840x2160) in just three to eight sampling steps. Released in late October and November 2026 under the MiniMax-H3 Community License and downloaded over 1.70 million times on Hugging Face, the two checkpoints replace closed cloud regeneration endpoints with local latent upscaling, an in context Ref2VA reference LoRA, and the distilled StreamRender-H3 tiled VAE decoder.
Studio availability. Open-H3-Regenerate-2K is not available in AI FILMS Studio. While MiniMax H3 Text to Video, MiniMax H3 Image to Video, and MiniMax H3 Video Extend are live in the Studio, the NVlabs Open-H3-Regenerate-2K refinement pipeline covered here is a separate open weights release. To upscale video in the Studio, use SeedVR2 Video Upscaler, Real-ESRGAN Video Upscaler, or Topaz Video Upscaler on the Video Upscaler page.
Open-H3-Regenerate-2K cinematic 2560x1440 showcase reel with synchronized sound (unmute to listen)
Three step 2K regeneration restoring skin pores, eyelashes, and fine fabric weave from a 768p draft
Why Spatial Upscalers Blur 768p AI Video Drafts
Most local MiniMax-H3 workflows render initial takes at 1344x768 (768p) across 121 frames (5 seconds at 24 fps) to keep generation times practical. Passing that 768p draft through a traditional spatial super resolution filter magnifies existing diffusion softness and smears subtle facial micro expressions, signage lettering, and distant foliage.
Native 2560x1440 or 3840x2160 generation from pure noise solves the detail problem, yet full 40 step diffusion at 2K or 4K resolution multiplies attention cost and frequently alters the exact actor blocking or camera framing that the director approved in the 768p draft.
NVlabs designed the Sol-Engine Open-H3-Regenerate-2K family to separate creative blocking from high resolution finishing. Filmmakers lock performance, lip sync, and camera motion at 768p, then run a deterministic three step or four step generative refinement pass at 2K or 4K with classifier free guidance disabled (CFG=1.0).
Two Architectures: Latent Refinement vs In-Context Ref2VA LoRA
The NVlabs release ships two distinct architectures on Hugging Face so studios can choose between maximum single GPU speed and strict 4K identity preservation.
- Three step latent upscale refiner (
Open-H3-Regenerate-2K). The base pipeline takes the768platent tensor, upscales it into the2560x1440latent grid, injects controlled noise at sigma0.909375, and runs three Euler steps across the sigma schedule[0.909375, 0.857143, 0.666667, 0]atCFG=1.0. It merges theHyperFlow8-step adapter and Sharp's1025x8adaln_t_tabletimetable curve alongside a rank 384 EMA refiner LoRA (step 5000 EMA). - In-Context Ref2VA transformer LoRA (
Open-H3-Regenerate-2K-IC). Released in November 2026 for1080p,2K(2560x1440), and4K(3840x2160) mastering, theICvariant keeps the original768pclip inside the context window ofMiniMax-H3'sRef2VAreference transformer (transformer_ref). Because every high resolution denoising step attends directly to the intact768preference tokens, actor faces, mouth shapes during dialogue, and on screen typography never drift at3840x2160. - Distilled
StreamRender-H3VAE decoder. At2560x1440and3840x2160, standard 3D VAE decoding often consumes more wall clock time and VRAM than the 3-step diffusion pass itself. NVlabs pairs both refiners withStreamRender-H3, a distilled streaming decoder that cuts VAE decode time and memory footprint by more than half.
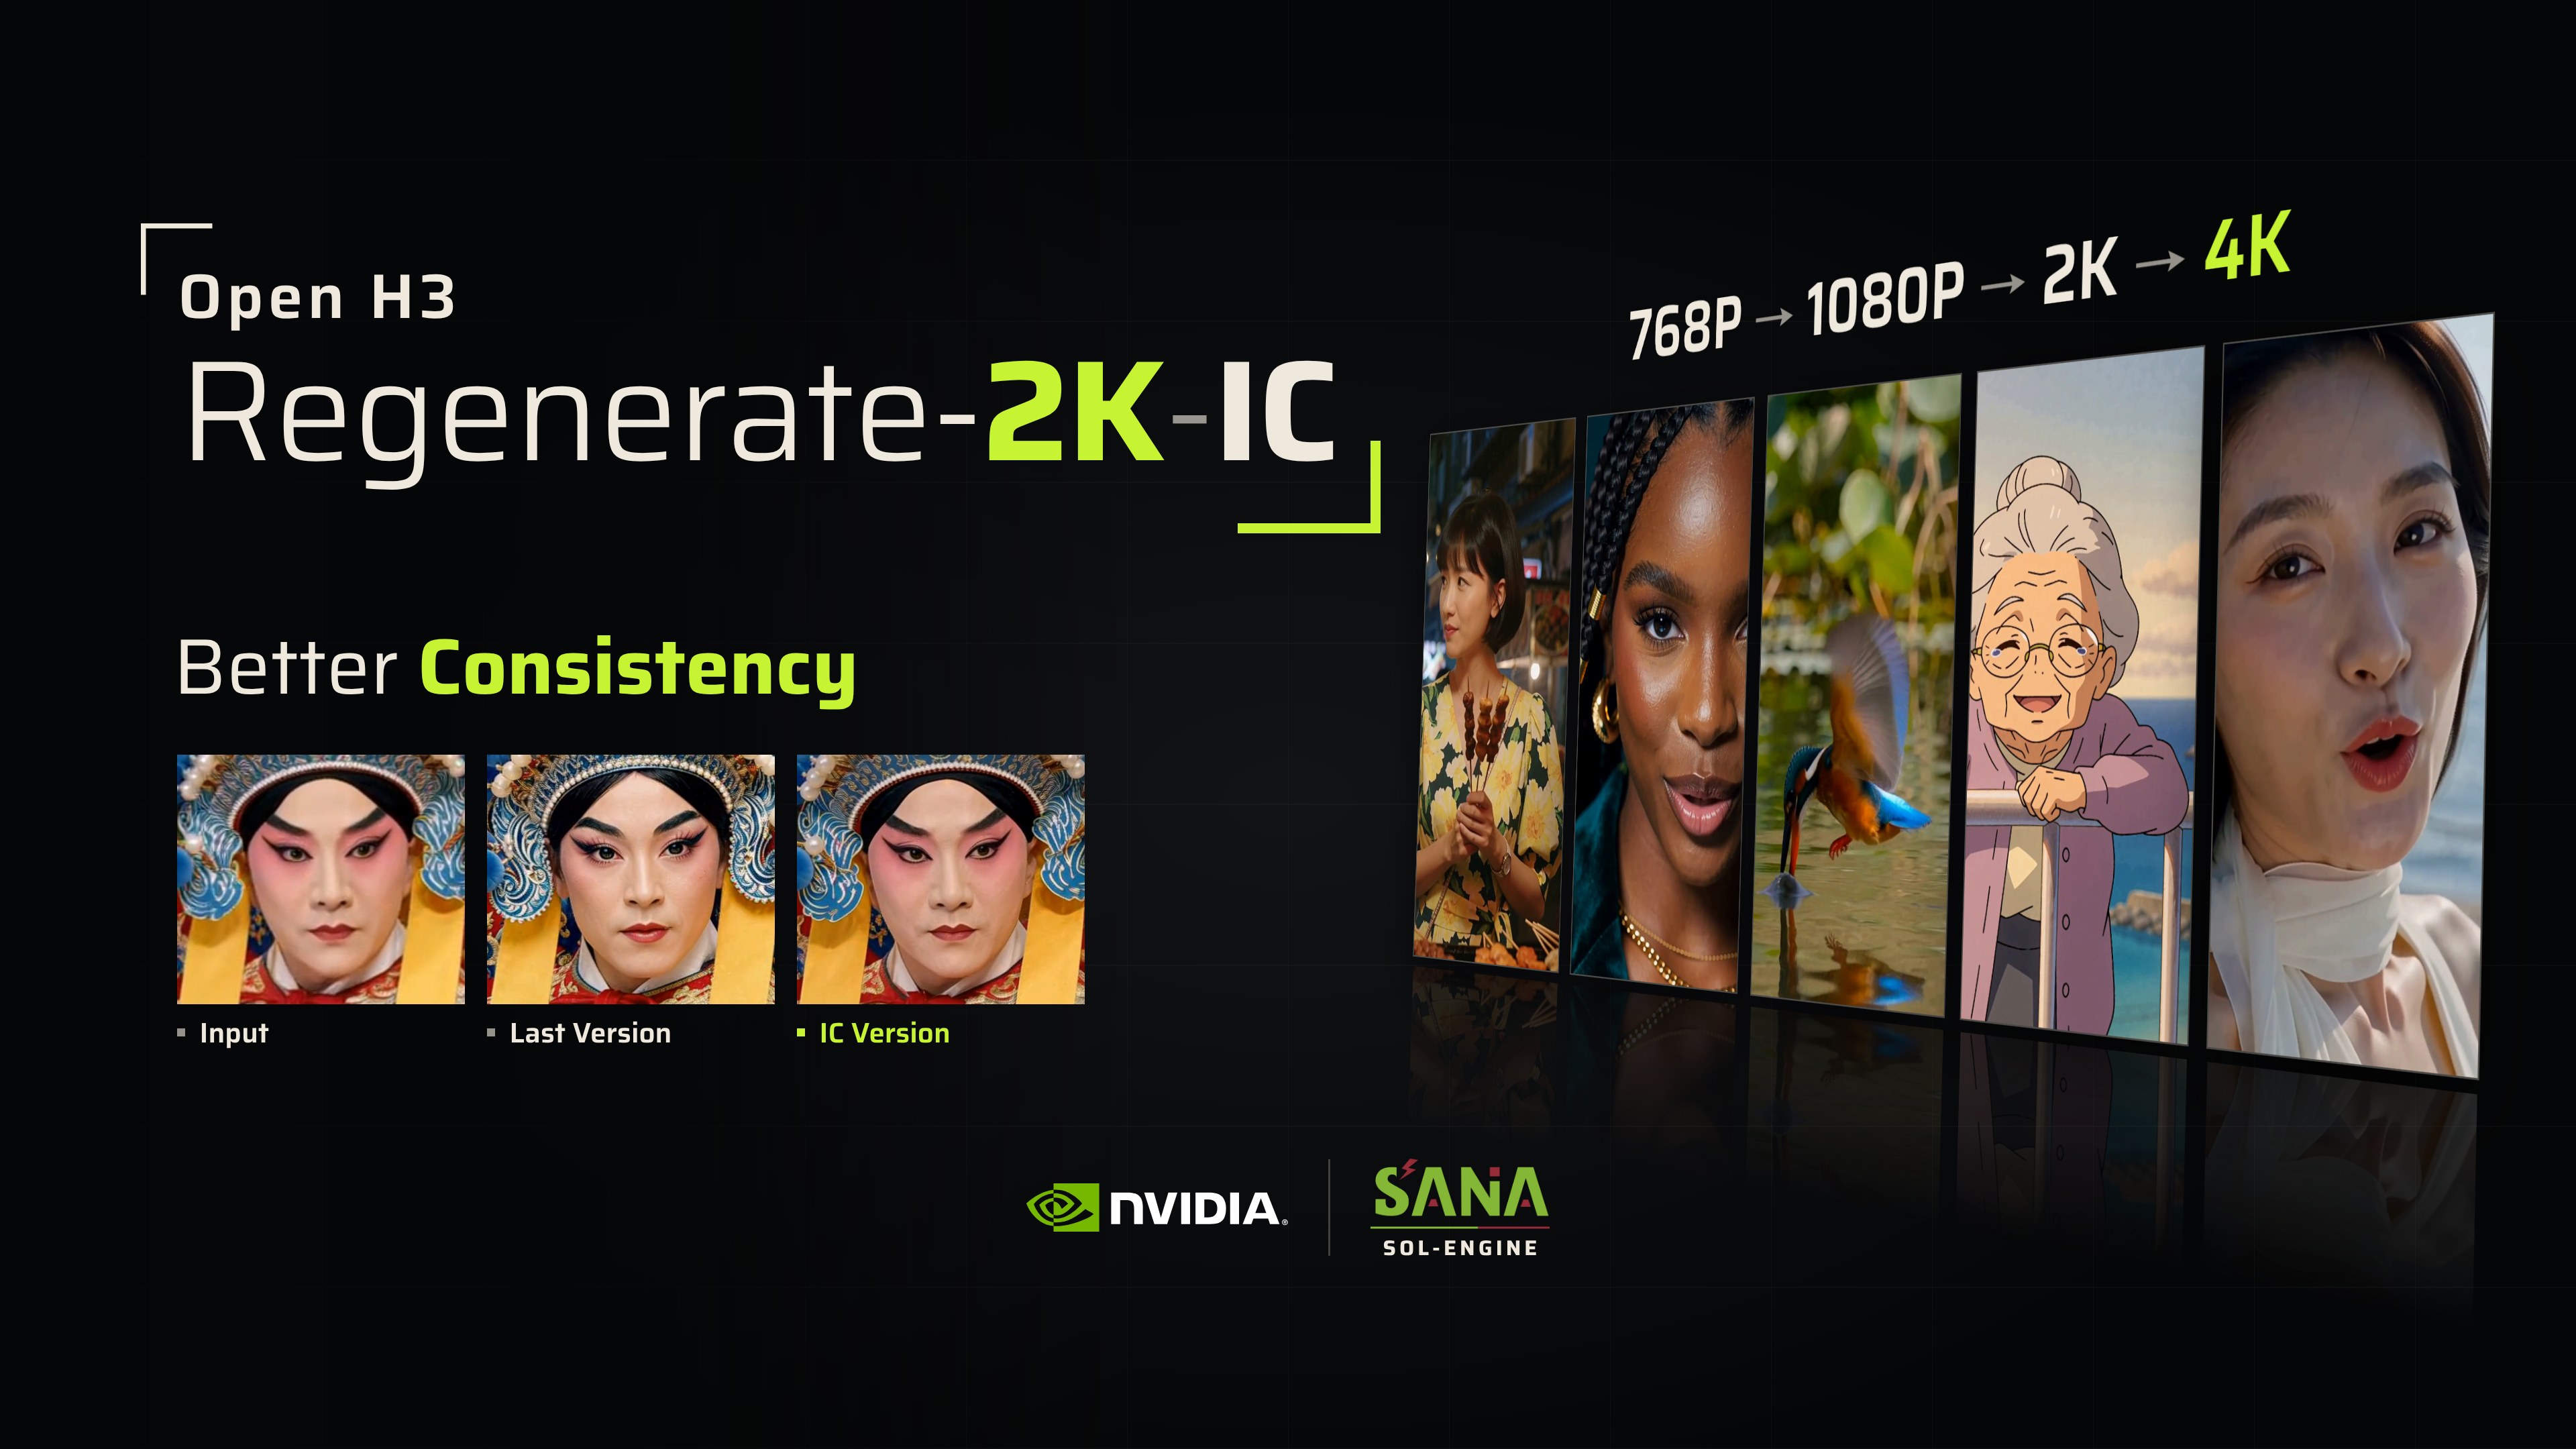
Open-H3-Regenerate-2K-IC keeping the 768p draft in context inside the Ref2VA transformer for 2K and 4K output. Credit: NVIDIA NVlabs.
When scaling a 768p shot fourfold to 3840x2160, simple latent noise injection can cause small faces or storefront signs to hallucinate new features.
Holding the 768p draft as an active reference stream inside `transformer_ref` anchors spatial layout and lip sync across all 121 frames while the IC LoRA synthesizes high frequency 4K detail.
In side by side crops against the closed commercial `H3-Regenerate-2K` API, the open weights 3-step refiner matches or exceeds hair strand separation, wet asphalt specular highlights, and skin grain.
Combining `HyperFlow` 8-step distillation with `LMS Sharp` at weight load time eliminates the waxy over smoothed look typical of few step video distillations.
2560x1440 detail recovery from a 1344x768 draft plate. Credit: Efficient-Large-Model / NVlabs.
Checkpoints, Sampling Modes & Hardware Matrix
| Checkpoint / Module | Hugging Face Repository | Target Resolution | Sampler & Steps (CFG=1.0) |
Hardware & Speed | License |
|---|---|---|---|---|---|
Open-H3-Regenerate-2K |
Efficient-Large-Model/Open-H3-Regenerate-2K |
2560x1440 (2K, 121 frames) |
3 Euler steps ([0.909375, 0.857143, 0.666667, 0]) |
Single 80 GB+ GPU (B200 / H100) or multi GPU shard | MiniMax-H3 Community |
Open-H3-Regenerate-2K-IC |
Efficient-Large-Model/Open-H3-Regenerate-2K-IC |
1080p, 2K (2560x1440), 4K (3840x2160) |
up3 (3 steps) · up4 (4 steps) · hf8 (8 steps from noise) |
Multi GPU (torchrun --nproc_per_node 8) or high VRAM node |
MiniMax-H3 Community |
StreamRender-H3 VAE |
Bundled in vae/ subfolder |
768p up to 4K decoding |
Distilled streaming 3D VAE decode | Cuts peak VAE memory and latency by >50% | MiniMax-H3 Community |
HyperFlow 8-Step + LMS Sharp |
Bundled in lora/ (rank 384) |
All H3 refinement resolutions | Merged into transformer_ref at load time |
Zero runtime overhead after weight merge | MiniMax-H3 Community |
Parameter Reference for Open-H3-Regenerate-2K-IC
When mastering shots with infer.py, four command line flags govern the balance between adherence to the 768p draft and newly synthesized 2K or 4K micro detail.
| Flag | Values | Production Behavior |
|---|---|---|
--sampler |
up3 (default), up4, hf8 |
up3 and up4 initialize from the upscaled draft latent and run the last 3 or 4 HyperFlow grid steps; hf8 starts from pure noise and runs all 8 steps conditioned on the reference clip. |
--resolution |
1080p, 2k, 4k |
Selects 1920x1080, 2560x1440, or 3840x2160 target grid while preserving the draft's aspect ratio and 121 frame temporal length. |
--caption |
Text prompt string | Passes the shot's visual description into Qwen3-VL text encoding to guide high frequency material textures during refinement. |
--stream_vae |
Enabled by default | Uses StreamRender-H3 tiled decoding so 121 frames of 3840x2160 RGB video decode without triggering out of memory crashes. |
Running Open-H3-Regenerate-2K and IC Locally
Clone the sol-engine branch of NVlabs/Sana, download the self contained checkpoint folder from Hugging Face (Efficient-Large-Model/Open-H3-Regenerate-2K or Open-H3-Regenerate-2K-IC), and execute infer.py.
# Clone the NVlabs Sol-Engine repository branch
git clone -b sol-engine https://github.com/NVlabs/Sana.git
cd Sana/models/Open-H3-Regenerate-2K

pip install -r requirements.txt

# Download the self-contained 2K refiner (includes base_model, HyperFlow LoRA, and StreamRender-H3)
huggingface-cli download Efficient-Large-Model/Open-H3-Regenerate-2K --local-dir ./weights/regen2k

# Run 3-step 768p -> 2560x1440 refinement on a single high-VRAM GPU
python infer.py \
  --weights ./weights/regen2k \
  --input assets/draft_768p.mp4 \
  --output outputs/master_2560x1440.mp4 \
  --caption "Close up of a weathered sea captain under stormy deck lights, rain droplets on wool coat, 65mm cinema lens."
For dialogue shots, title cards, or 4K (3840x2160) delivery where facial identity and lip sync cannot shift by a single pixel, run the In-Context IC pipeline across sharded GPUs.
cd Sana/models/Open-H3-Regenerate-2K/IC
huggingface-cli download Efficient-Large-Model/Open-H3-Regenerate-2K-IC --local-dir ./weights/regen2k_ic

# 3-step in-context regeneration to 2K or 4K preserving faces, lip sync, and lettering
torchrun --nproc_per_node 8 infer.py \
  --weights ./weights/regen2k_ic \
  --input assets/dialogue_draft_768p.mp4 \
  --output outputs/dialogue_master_2k.mp4 \
  --sampler up3 \
  --caption "Medium two-shot in a neon diner, crisp signage lettering in window, sharp eye reflections."
Production Playbook for Filmmakers
- Fast creative iteration at 768p. Generate 10 to 20 candidate takes at
1344x768usingMiniMax-H3with an 8-stepHyperFloworDMADLoRA until camera timing and acting beats lock. - Choose
up3vshf8by shot type. Use--sampler up3onOpen-H3-Regenerate-2K-ICfor lip synced dialogue, close ups, and VFX plates with readable text. Switch to--sampler hf8on wide establishing landscapes where you want the 2K or 4K pass to synthesize richer foliage, clouds, or water ripples. - Compare with universal diffusion upscalers. Unlike general video upscalers that operate on any decoded
.mp4,Open-H3-Regenerate-2Kuses the exactMiniMax-H33D latent space andRef2VAtransformer. For clips generated by other backbones (Wan 2.2,LTX-2.5, or live action cameras), pair your pipeline with SeedVR2 and Real-ESRGAN Video, SVI360 and UltraVSR 4K super resolution, or FlashVSR real time video upscaling. Also see our guide on HyperFlow H3 Flash fast video LoRA and GGUF workflows.
To generate shots with MiniMax H3 in the cloud or upscale video to 4K without local multi GPU setup, open the Video Upscaler and Image to Video pages, or chain generation and upscaling nodes visually in the Nodes Graph Editor.


Sources
- NVlabs Open-H3-Regenerate-2K & IC Official Project Page
- NVlabs/Sana Sol-Engine Open-H3-Regenerate-2K GitHub Repository
- Efficient-Large-Model/Open-H3-Regenerate-2K on Hugging Face
- Efficient-Large-Model/Open-H3-Regenerate-2K-IC on Hugging Face
- NVlabs StreamRender-H3 Distilled Video VAE Project Page
- MiniMaxAI/MiniMax-H3 Base Model & Community License on Hugging Face
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)