

Institute of Foundation Models (IFM) at MBZUAI (Apache 2.0)
Share this post:
PAN2: Open Source World Simulation Video AI
Standard video generators treat a prompt as a loose visual mood board, which breaks down as soon as a scene requires cause and effect over 15 or 20 seconds. PAN 2 (IFM/PAN2), developed by the Institute of Foundation Models (IFM) at MBZUAI and released under the Apache 2.0 license, approaches video generation as world simulation. Pairing a language based conceptual reasoner with a 29B parameter MMDiT perceptual backbone, PAN 2 simulates how objects, actors, and cameras evolve across up to 20 seconds at 704x1248 and 24 fps from a single text-to-video or image-to-video prompt. You can test this open source model free in your browser below with zero login.
Studio availability. Try the public Hugging Face demo below; PAN 2 is not part of a paid AI FILMS Studio plan (use MiniMax H3 Image to Video in the video workspace for example instead).
Try PAN 2 Live
Test text-to-video and image-to-video world simulation directly in the public Hugging Face Space below without local multi GPU hardware.
Architecture and Technical Design
PAN 2 implements the Generative Latent Prediction (GLP) architecture formalized in Critique of World Models (arXiv:2507.05169). Rather than forcing one diffusion network to invent both narrative logic and pixel texture simultaneously, PAN 2 splits the job into two distinct stages.
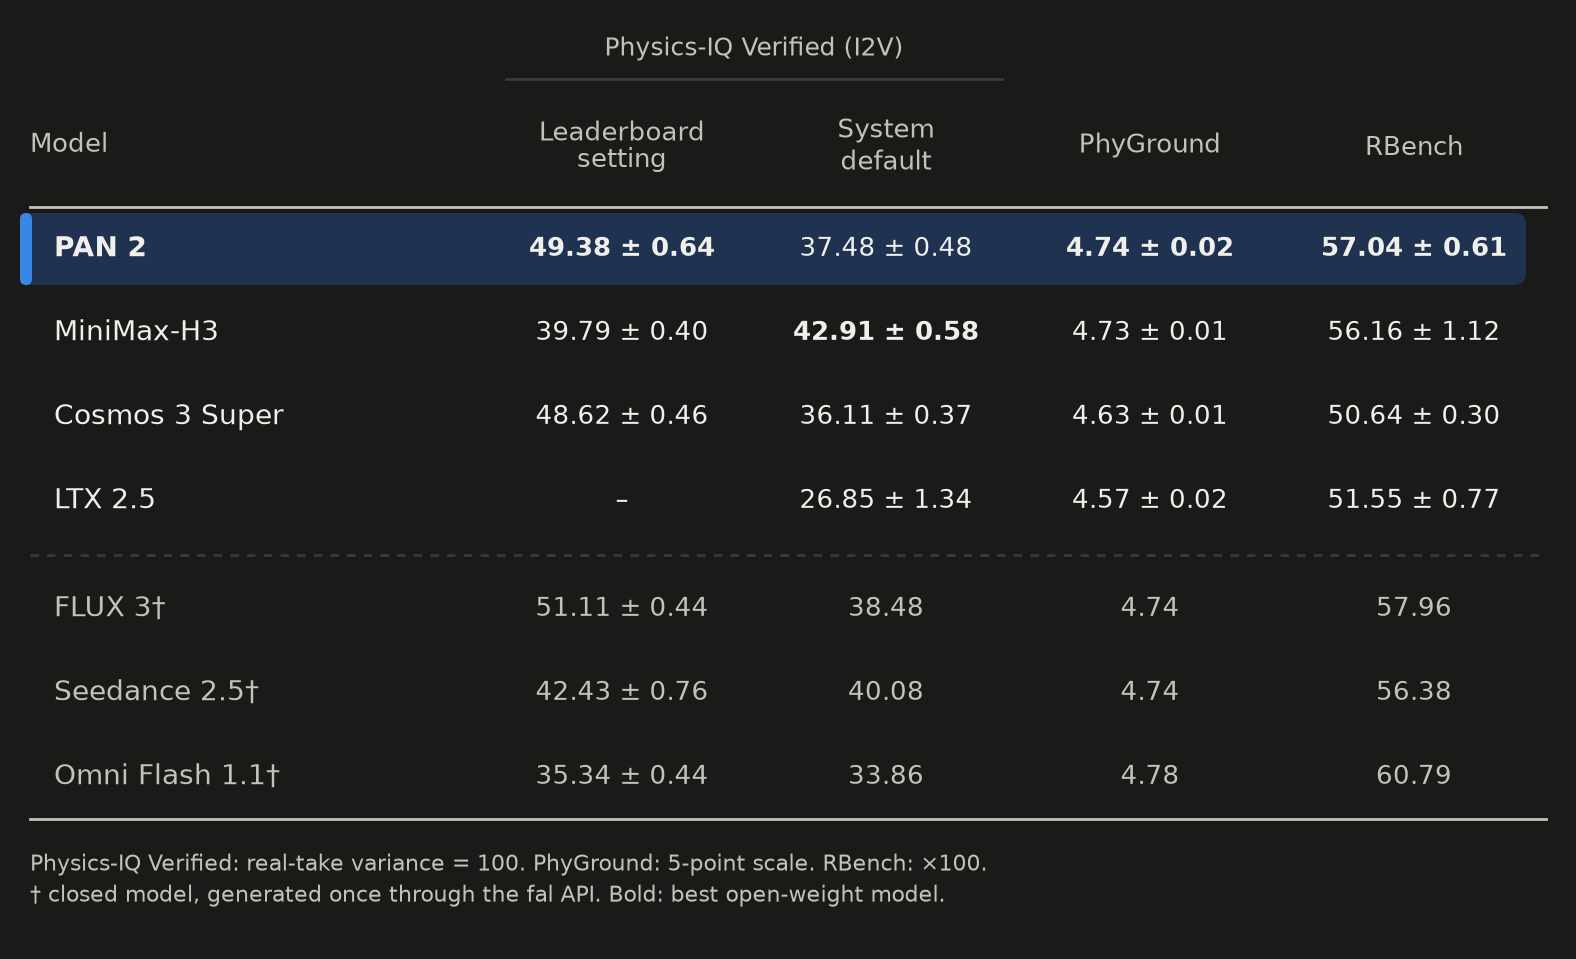
PAN 2 benchmark scores by IFM at MBZUAI, Apache 2.0
First, the conceptual reasoning backbone reads the starting frame and user action instructions, then writes a structured, time grounded world state script specifying timed actor actions, physics outcomes, and camera moves.
Second, a frozen Qwen3.5-9B text encoder converts that structured world state into conditioning features for the 29B parameter MMDiT perceptual backbone, trained from scratch on hundreds of millions of annotated videos. The Wan 2.2 VAE decodes the predicted video latents back into crisp 24 fps footage.
Because one unified checkpoint serves both t2v and i2v tasks, production teams can stage an entire sequence from a single storyboard keyframe and steer how the shot unfolds across 241 frames (10 seconds) or 481 frames (20 seconds).
Human evaluation studies published by IFM show strong preference for PAN 2 on physical plausibility, action adherence, and long horizon coherence compared to standard clip generators. Filmmakers can also use PAN 2 for simulative pre visualization, testing two or three blocking variations from the same opening plate before committing to principal photography.
Official integration ships across Hugging Face Diffusers (PAN2Transformer3DModel) and vLLM serving recipes, simplifying batch rendering on cloud GPU clusters.
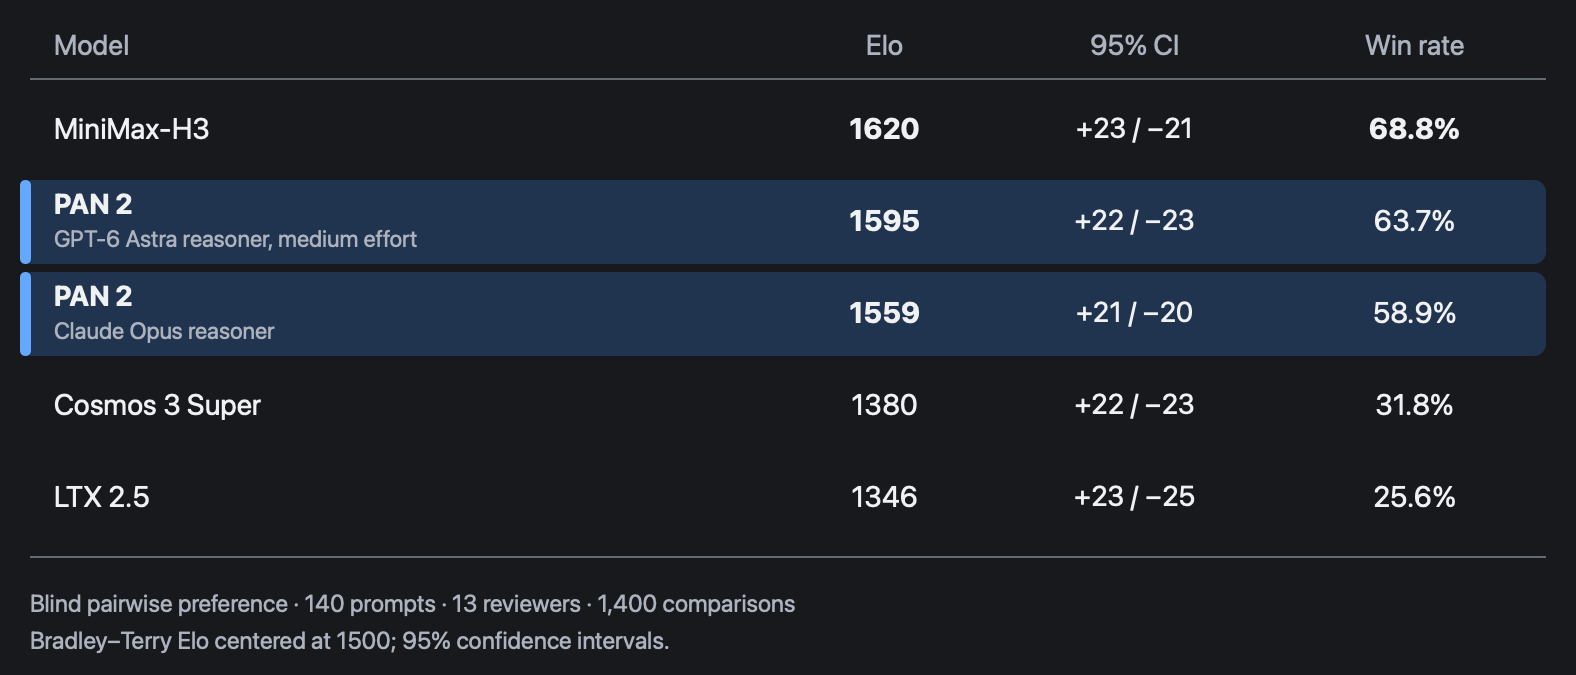
PAN 2 human evaluation results by IFM at MBZUAI, Apache 2.0
Hardware, VRAM, and License Matrix
| Deployment Option | Precision / Format | Typical VRAM | Output Ceiling | License | Intended Use |
|---|---|---|---|---|---|
IFM/PAN2 (Diffusers BF16) |
BF16 Safetensors (29B DiT + Qwen3.5-9B + Wan 2.2 VAE) | ~80 GB (H100 / A100 / B200) | 704x1248, 24 fps, up to 20 s | Apache 2.0 | Commercial pre vis, world simulation |
Multi GPU Node (generate.py) |
BF16 data parallel workers | 1x 80 GB GPU per worker | Batch T2V and I2V rollouts | Apache 2.0 | Studio shot generation queues |
| Quantized / CPU Offload | FP8 / sequential offload | ~32 to 48 GB | Slower 10 s clips (241 frames) | Apache 2.0 | Local research workstations |
The Apache 2.0 license covers both the code and the 29B weights with zero commercial revenue caps.
Parameter Reference
| Parameter | Default Value | Production Guidance |
|---|---|---|
NUM_STEPS |
50 |
Full quality denoising schedule for complex physics |
FLOW_SHIFT |
9 |
Balances global motion layout with fine texture detail |
GUIDANCE_SCALE |
2.5 |
Applied across every step; prevents oversaturated highlights |
VIDEO_LENGTH |
241 frames (~10 s) |
Extend up to 481 frames (20 s) for long action beats |
| Resolution & FPS | 704 x 1248 at 24 fps |
Matches theatrical 24 fps editorial timelines |
| I2V Temporal Latent 0 | Unconditional anchor | Locks opening frame identity without guidance distortion |
Local Python and CLI Setup
Download the IFM/PAN2 perceptual backbone along with its frozen Qwen/Qwen3.5-9B text encoder and Wan-AI/Wan2.2-TI2V-5B-Diffusers VAE, then run inference with the official repository or Diffusers.
git clone https://github.com/ifm-ai/PAN2 && cd PAN2
pip install -r requirements.txt
hf download IFM/PAN2 --include "transformer/*" --local-dir ./weights/PAN2
hf download Qwen/Qwen3.5-9B
hf download Wan-AI/Wan2.2-TI2V-5B-Diffusers
# Convert diffusers weights once for native generate.py inference
python scripts/convert_checkpoint.py to-native \
  --input ./weights/PAN2/transformer \
  --output ./weights/PAN2-native/transformer

# Run text-to-video and image-to-video batch generation
bash inference/inference.sh ./weights/PAN2-native/transformer ./outputs inference/prompts/examples.json
Filmmaker Production Playbook
- Run the conceptual reasoner before rendering. Feed your plain English director brief through
inference/prompts_rewritter.pyfirst. The 29B perceptual backbone was trained on structured, time stamped world state descriptions, so rewriting prompts with explicit timed actions yields far stronger physics and camera obedience. - Lock opening composition with image-to-video. Generate a crisp hero keyframe first, pass it as
image_path(type: i2v), and let PAN 2 simulate 10 to 20 seconds of continuous camera and character movement from that exact frame. - Use 241 frames for blocking tests, 481 frames for master beats. Running 10 second previews cuts compute in half while you verify actor trajectories, then switch to 20 second rollouts once the motion path is approved.
- Combine with video super resolution for 4K delivery. Native PAN 2 outputs sit at 704x1248. Pass approved takes through RelayVSR or SeedVR2 Video Upscaler in AI FILMS Studio to finish at crisp 1080p or 4K.
Related Reading
- LingBot-World-V2: Open Source 60 FPS World Simulator
- ATAS (Any Time, Any Space): Open Source Multi Shot Video
- RelayVSR: Open Source AI Video Super Resolution
- Explore cloud image-to-video models on the AI Image to Video Generator page.


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)