

Robbyant / Ant Group, LingBot-World-V2 (arXiv:2607.07534, CC BY-NC-SA 4.0)
Share this post:
LingBot-World-V2: Open Source 60 FPS World Simulator
LingBot-World-V2 (Robbyant/lingbot-world-v2, also known as LingBot-World-Infinity, arXiv:2607.07534) is Ant Group's open source interactive video world model engineered for unbounded, real time 720p at 60 fps environment exploration from a single starting image. Shipping in both 14B (lingbot-world-v2-14b-causal-fast) and 1.3B (lingbot-world-v2-1.3b) weights alongside community GGUF quantizations that run on 8 GB GPUs, V2 introduces causal pretraining and a Director and Pilot agentic controller that lets filmmakers steer camera paths and dynamic world events indefinitely without quality collapse.
Studio availability. LingBot-World-V2 is not part of a paid AI FILMS Studio plan (use WAN 3.0 or Kling 3 in the video workspace).
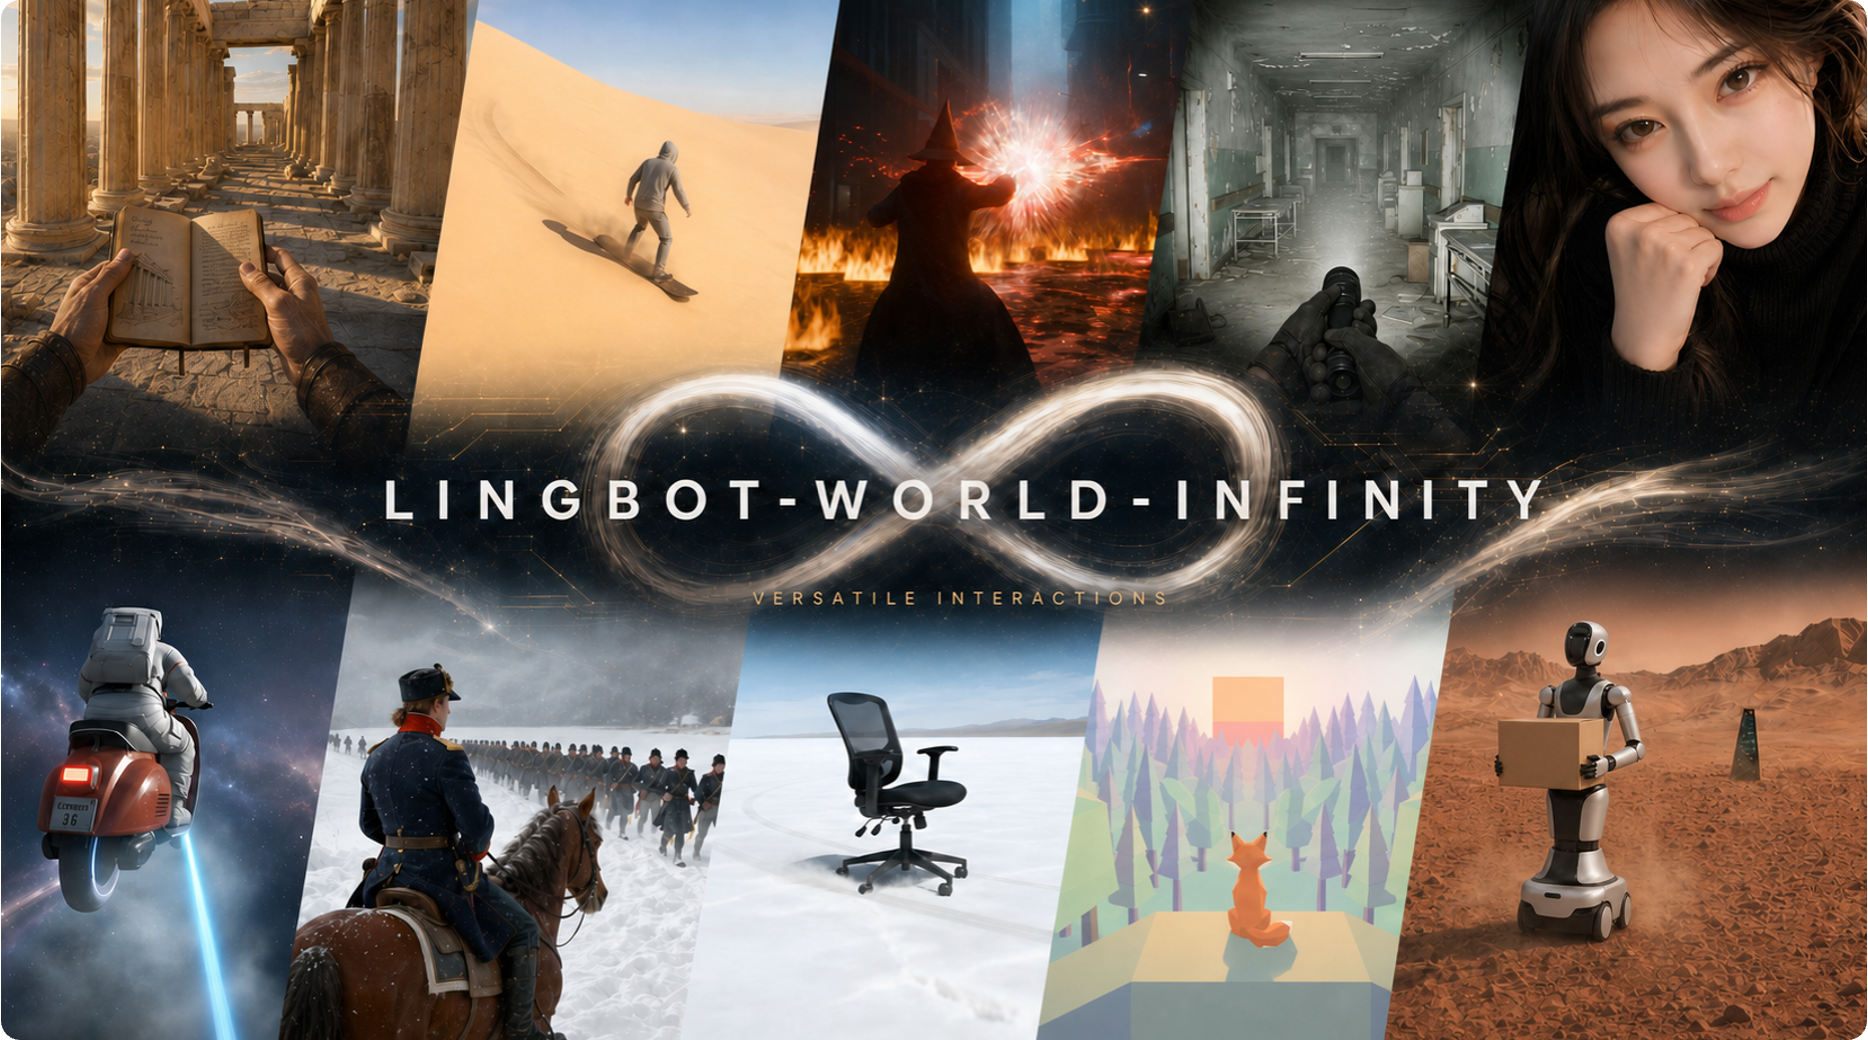
How LingBot-World-V2 Solves Long Horizon World Drift
First generation world models looked impressive for 8 to 15 seconds, then melted into gray blur or forgot buildings the moment a virtual camera panned 180 degrees. LingBot-World-V2 redesigns both pretraining and runtime control to keep spatial layouts and interactive physics alive across unbounded horizons:
- Causal pretraining paradigm. Rather than fine tuning a bidirectional video generator into a causal stream late in training, Robbyant pretrains the DiT causally across massive interactive environment trajectories. Frame to frame temporal consistency stays stable across multi minute rollouts without progressive contrast burn.
- Director and Pilot agentic controller. V2 splits scene control into two cooperating modules. The Pilot translates real time keyboard, gamepad, or spline camera trajectories (
W/A/S/D, pitch, yaw, speed) into low latency frame actions. The Director parses natural language event prompts mid rollout, triggering weather changes, crowd arrivals, vehicle motion, or lighting shifts while keeping the underlying 3D street geometry intact. - 14B causal fast and 1.3B lightweight tracks. Enterprise rigs can run the 14B checkpoint at 720p 60 fps across multi GPU nodes, while solo filmmakers can load the 1.3B checkpoint or community GGUF Q4/Q8 ports of
14B-causal-faston a single8 GB – 16 GBconsumer GPU.
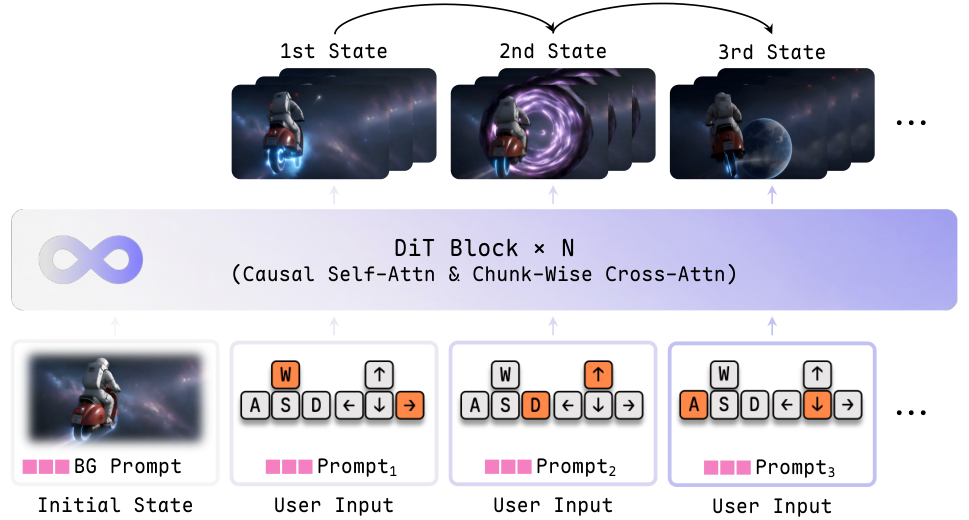
Causal pretraining schedule in LingBot-World-V2 preventing exposure bias during unbounded camera rollouts. Credit: Robbyant (arXiv:2607.07534).
Standard bidirectional video models require every frame in a clip to attend to future frames, making interactive camera steering impossible without chunking seams.
LingBot-World-V2's native causal masking streams frames sequentially while retaining spatial landmarks in its world memory KV cache.
Hardware, Quantization, and License Matrix
| Model Variant | Parameters | Target Hardware / VRAM | Resolution & Speed | License |
|---|---|---|---|---|
lingbot-world-v2-14b-causal-fast (BF16) |
14B |
Multi GPU server (8x H100/A100) |
720p up to 60 fps |
CC BY-NC-SA 4.0 (Non Commercial) |
lingbot-world-v2-14b-causal-fast (GGUF) |
14B (Quantized) |
8 GB – 16 GB VRAM + 32 GB RAM |
320x544 to 480x832 interactive |
CC BY-NC-SA 4.0 (Non Commercial) |
lingbot-world-v2-1.3b |
1.3B |
Single 12 GB – 24 GB GPU (RTX 4070 / 4090) |
480p – 720p real time |
CC BY-NC-SA 4.0 (Non Commercial) |
Non Commercial License Notice.
Robbyant/lingbot-world-v2is released under CC BY-NC-SA 4.0. Filmmakers can use it freely for research, personal exploration, and non commercial pre visualization tests, but commercial productions require a separate license from Ant Group.
The Director and Pilot controller separates low level camera steering from high level narrative staging.
A cinematographer can dolly down a hallway with the Pilot controls while typing a Director cue to flick overhead fluorescent lights or open a blast door ahead.
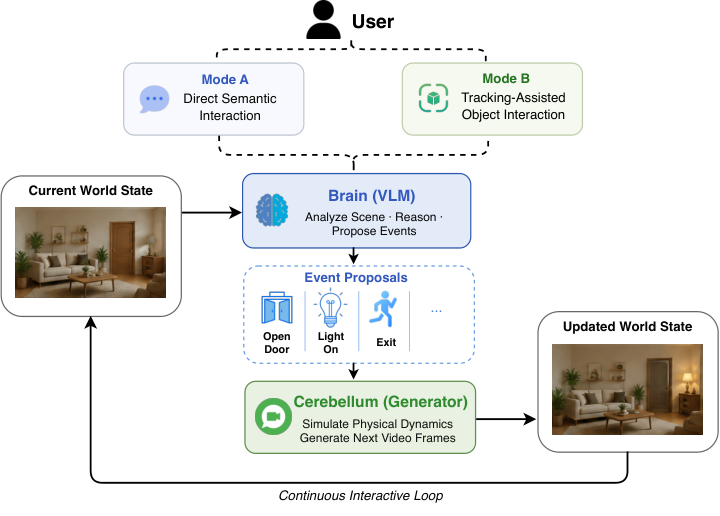
Director and Pilot controller coordinating real time camera inputs with dynamic world events. Credit: Robbyant (arXiv:2607.07534).
Parameter Reference Table
| Parameter | Recommended Value | Effect on Interactive Rollout |
|---|---|---|
--ckpt_dir |
lingbot-world-v2-1.3b or 14b-causal-fast |
Selects between single GPU portability and maximum 720p physics detail. |
--action_path |
camera_traj.json |
Supplies per frame 6 DoF camera motion and keyboard/action tokens. |
--director_prompt |
Timed event strings | Injects weather, lighting, or character actions mid stream without resetting the set. |
--kv_cache_window |
16 to 32 frames |
Balances spatial loop closure memory against single GPU VRAM usage. |
--fps |
24 or 60 |
Use 24 for cinema previs cadence or 60 for interactive virtual scouting. |
Local Setup with Python
Clone the official repository and launch a single image interactive rollout:
git clone https://github.com/Robbyant/lingbot-world-v2.git
cd lingbot-world-v2
pip install -r requirements.txt

huggingface-cli download robbyant/lingbot-world-v2-1.3b --local-dir ./weights/lingbot-world-v2-1.3b
python generate_interactive.py \
  --ckpt_dir ./weights/lingbot-world-v2-1.3b \
  --image ./plates/abandoned_station_keyframe.png \
  --prompt "Slow Steadicam push through an abandoned train concourse, volumetric dust shafts" \
  --action_sequence "forward:48,pan_left:24,forward:48" \
  --director_event "t=60:overhead sodium lamps flicker on" \
  --resolution 480x832 \
  --output station_scouting_take01.mp4
Filmmaker Production Playbook
- Use V2 for virtual location scouting before building 3D sets. Drop a single concept art frame into
LingBot-World-V2and walk the virtual camera around the space to discover natural foreground frames and lens focal lengths. - Export scouting captures as motion guides. Once you find a winning Steadicam move inside the interactive simulator, record the clip and feed its motion timing into commercial licensed video generators in AI FILMS Studio.
- Keep KV cache windows tight on 8 GB – 12 GB cards. When running the community
14B-causal-fastGGUF port locally, start at320x544with a 16 frame KV cache to maintain interactive responsiveness before stepping up resolution.
Related Reading
- LingBot-World: Open Source Interactive World Simulator
- WorldCrafter & Hy-Nomas: Open Source 3D World Video AI
- WaveForcing & MovieRoll: Open Source Long Video AI
- NVIDIA Cosmos 3: Open World Model for Video Generation


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)