

AI FILMS benchmark chart from BRIA RMBG 3.0 234-image hard set evaluation
Share this post:
BRIA RMBG 3.0: Open Source VFX Background Removal
Traditional segmentation networks struggle with bicycle spokes, wispy hair, translucent glass, and cast floor shadows because they classify pixels edge by edge. BRIA RMBG 3.0, released on November 10, 2026, replaces single pass segmentation with a 4 step generative alpha matting model built on the 8B FIBO 2.0 foundation architecture. Across BRIA's 234 image hard evaluation set, RMBG 3.0 earned an average rank of 1.51, outperforming BiRefNet in 75.9% of blind comparisons and RMBG 2.0 in 60.9%.
Studio availability. Try the public Hugging Face demo below; BRIA RMBG 3.0 is not part of a paid AI FILMS Studio plan (use BEN2 Background Remover in the image workspace for example instead).
Try BRIA RMBG 3.0 Live
Upload any production still, prop photo, or complex hair portrait into the official BRIA Space below to inspect its 4 step soft alpha matte extraction directly in your browser.
Architecture and Technical Design
Earlier background removers like RMBG 2.0 and BiRefNet rely on discriminative encoder decoder networks that output a binary or lightly feathered foreground mask. BRIA RMBG 3.0 moves matting into a flow matching Diffusion Transformer (DiT) built on FIBO 2.0 (8B), pairing a Qwen3-VL-4B vision language encoder with FLUX.2 VAE latents. The checkpoint is distilled to run in 4 steps with zero classifier free guidance (guidance_scale=1.0), producing a continuous 8 bit soft alpha matte in roughly 6 seconds on an NVIDIA L40S.
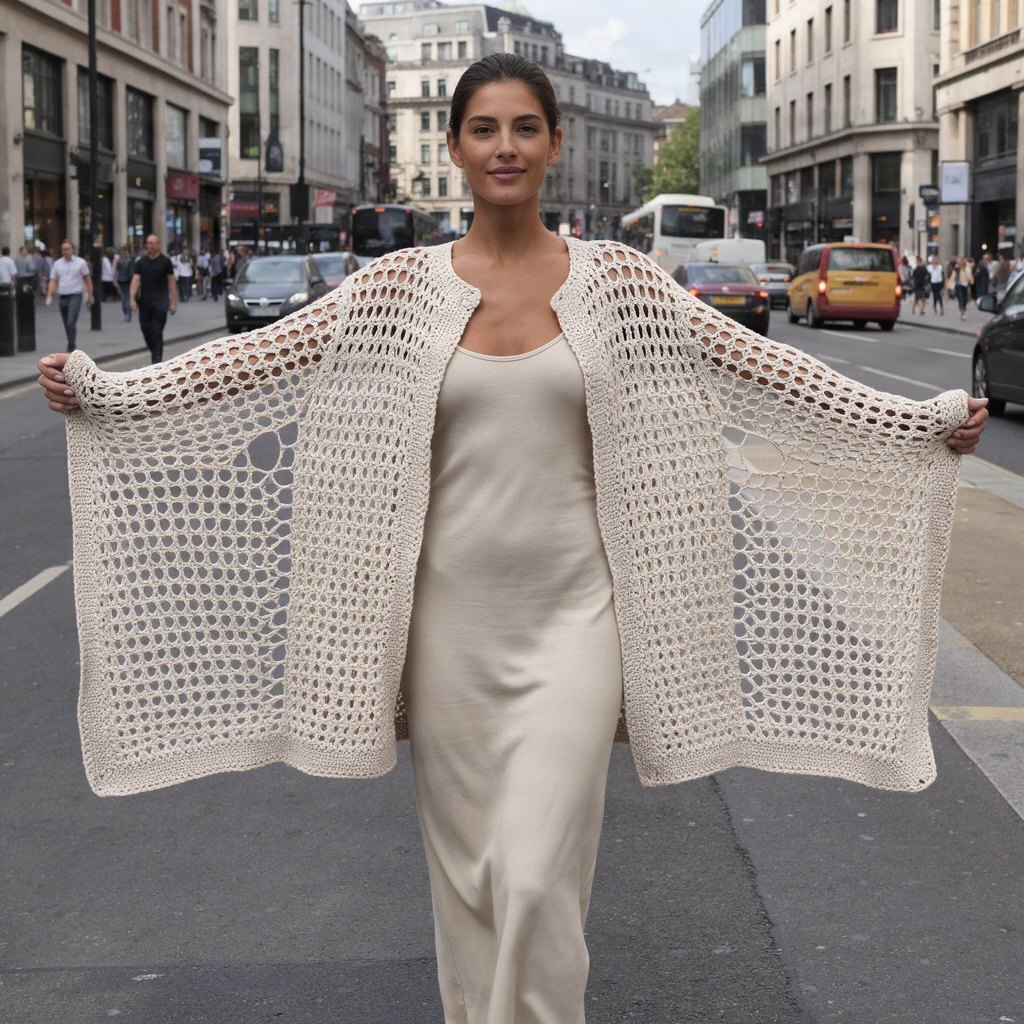
RMBG 3.0 soft fiber test plate by BRIA AI
Because the 8B backbone understands 3D scene semantics rather than raw contrast edges, it separates subjects from their own cast shadows and reflective tabletops. Internal holes inside chain link fences, foliage, and knitwear fibers stay open instead of turning into solid gray blobs.
In blind human and VLM side by side evaluations across 234 difficult full resolution images, RMBG 3.0 scored best or tied best on 79% (185 of 234) of the test set, beating remove.bg (59.4% preference), Ideogram (65.6%), and Photoroom (55.1%).
Hardware, VRAM, and License Matrix
| Deployment Option | Precision / Format | Typical VRAM | Inference Speed | License | Intended Use |
|---|---|---|---|---|---|
briaai/RMBG-3.0 (BF16) |
Safetensors (Diffusers) | ~20 to 24 GB | ~6 s on NVIDIA L40S | CC BY-NC 4.0 (Gated) | Research, look development, non commercial testing |
| Quantized FP8 / NVFP4 community builds | 8 bit / 4 bit | ~10 to 16 GB | Faster on Ada / Blackwell | CC BY-NC 4.0 | Local workstation plate prep |
| BRIA Commercial License / API | Enterprise agreement | Cloud / Self hosted | Production SLA | Commercial (100% licensed data) | Paid client VFX, advertising, and broadcast |
The open weights on Hugging Face require accepting BRIA's gated non commercial license (CC BY-NC 4.0). Commercial studios that need legally indemnified production matting can license the model directly from BRIA, since all training data is fully licensed.
Parameter Reference
| Parameter | Recommended Value | Behavior in Compositing |
|---|---|---|
num_inference_steps |
4 |
Distilled schedule; extra steps are not required |
guidance_scale |
1.0 |
Guidance free distillation; keep at 1.0 to avoid edge halos |
| Output format | 16 bit or 8 bit RGBA PNG | Preserves continuous soft alpha transparency for hair and smoke |
| Input resolution | Full native plate | Avoid aggressive downscaling before extraction on hair detail |
| Base dependency | briaai/Fibo-2.0-edit-turbo |
Shared VAE and Qwen3-VL-4B encoder components |
Local Python and CLI Setup
Request gated access to briaai/RMBG-3.0 and briaai/Fibo-2.0-edit-turbo on Hugging Face, authenticate locally with hf auth login, and run the 4 step pipeline in Python.
pip install -U torch diffusers transformers accelerate pillow
hf auth login
import torch
from diffusers import DiffusionPipeline
from PIL import Image

pipe = DiffusionPipeline.from_pretrained(
    "briaai/RMBG-3.0",
    torch_dtype=torch.bfloat16,
    trust_remote_code=True,
).to("cuda")

plate = Image.open("actor_plate.png").convert("RGB")
result = pipe(
    image=plate,
    num_inference_steps=4,
    guidance_scale=1.0,
).images[0]

result.save("actor_plate_rgba.png")
For workstations with 16 GB VRAM or less, call pipe.enable_model_cpu_offload() before inference so the Qwen3-VL-4B encoder swaps cleanly off GPU memory while the 8B DiT runs its 4 steps.
Filmmaker Production Playbook
1. Pull clean hero plates for AI relighting and set extension. Before dropping an actor or hero prop into a new virtual background, run the keyframe through RMBG 3.0 to preserve fine stray hairs and translucent fabric edges. Clean alpha borders prevent dark fringe artifacts when you animate the composite in an image-to-video generator.
2. Separate botanical and mesh props without manual roto. Complex foreground elements like flowers, tree branches, and metal grilles normally burn hours of manual spline work. RMBG 3.0's generative matte handles fine negative space cleanly in four steps.
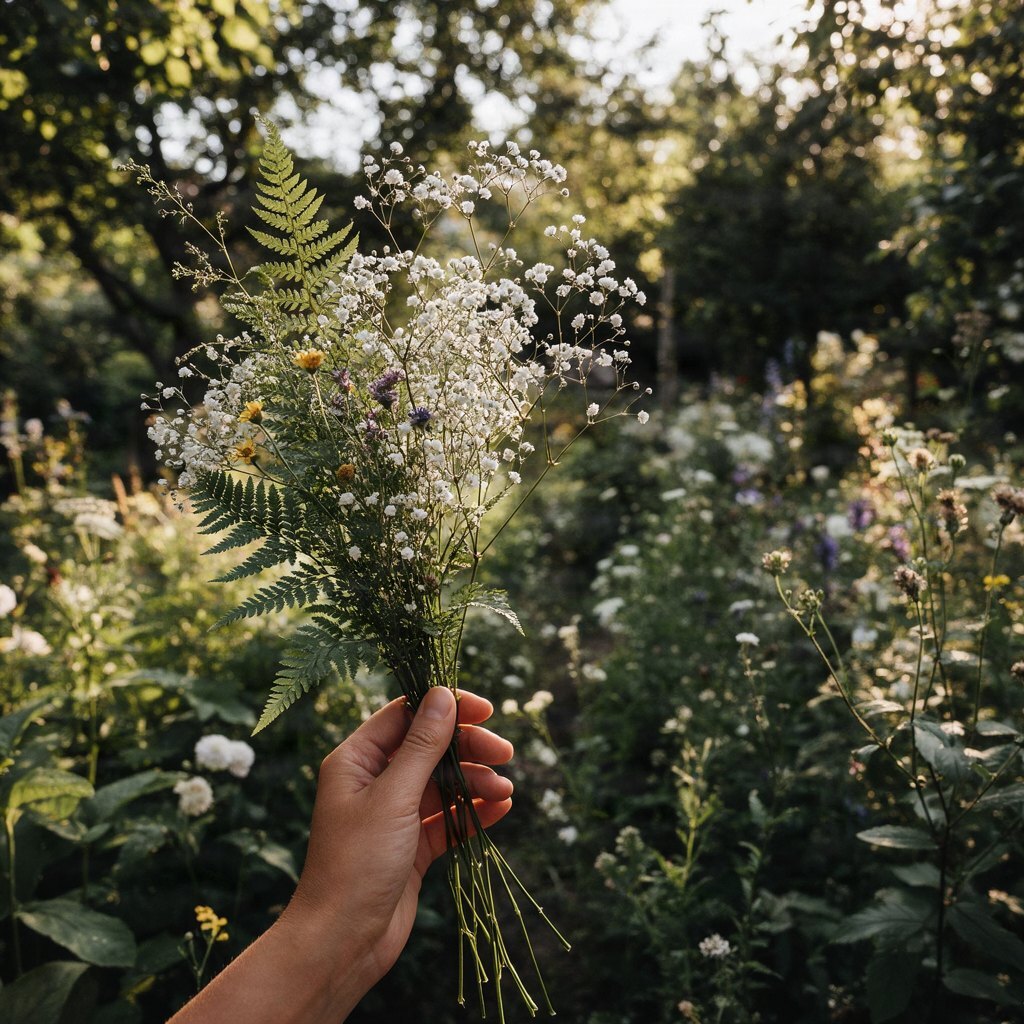
RMBG 3.0 botanical matte test plate by BRIA AI
- Combine still matting with temporal video matting. Use RMBG 3.0 to extract crystal clear hero reference cutouts and title props, and pair it with temporal video mattes like MatAnyone 2 or VideoMaMa when tracking moving footage across long shots.
- Run commercial background removal in the cloud. For paid client work where non commercial weights do not apply, use BEN2 Background Remover on the background remover page or directly inside the image workspace.
Related Reading
- Meta SAM 3: Open Source Promptable Video Segmentation
- BiRefNet, Real-ESRGAN & SwinIR: Open Source VFX Matting
- SAM-MT Achieves 36 FPS Multi-Target Video Segmentation
- VideoMaMa & VideoMaMa++: Open Source AI Video Matting


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)