

Meta AI Research — SAM 3 Promptable Concept Segmentation architecture
Share this post:
Meta SAM 3: Open Source Promptable Video Segmentation
SAM 3 (Segment Anything Model 3) (facebookresearch/sam3) extends Meta AI's foundation segmentation family into Promptable Concept Segmentation (PCS) across both images and video. Instead of clicking individual pixels on every person or prop in a crowded shot, VFX artists can type a short concept phrase such as "yellow taxi", "actor in red jacket", or "handheld microphone", and SAM 3 detects, masks, and tracks every matching instance cleanly across moving frames even through occlusions.
Studio availability. Try the public Hugging Face demo below; Meta SAM 3 is not part of a paid AI FILMS Studio plan (use BEN2 Background Remover or WAN 3.0 in the video workspace for example instead).
Why Promptable Concept Segmentation Changes VFX Rotoscoping
In SAM 2, isolating six background extras or three moving vehicles required clicking manual point prompts on each individual object on frame 1, and any new object entering the shot on frame 40 went untracked.
SAM 3 unifies open vocabulary detection and temporal mask tracking inside one architecture:
- Text and visual concept prompts. Supply a short noun phrase or an example visual crop to segment every matching instance simultaneously across the entire clip, automatically picking up newly entering objects mid shot.
- Unified detector and memory tracker. SAM 3 pairs a shared vision backbone with a concept presence head and temporal memory bank, preventing mask ID swaps when actors cross paths behind foreground columns.
- Production ready alpha masks for compositing. Exported binary or soft matte sequences plug directly into Nuke, After Effects, DaVinci Resolve Fusion, MatAnyone 2, or LBM Relighting for clean background replacement and color grading isolation.
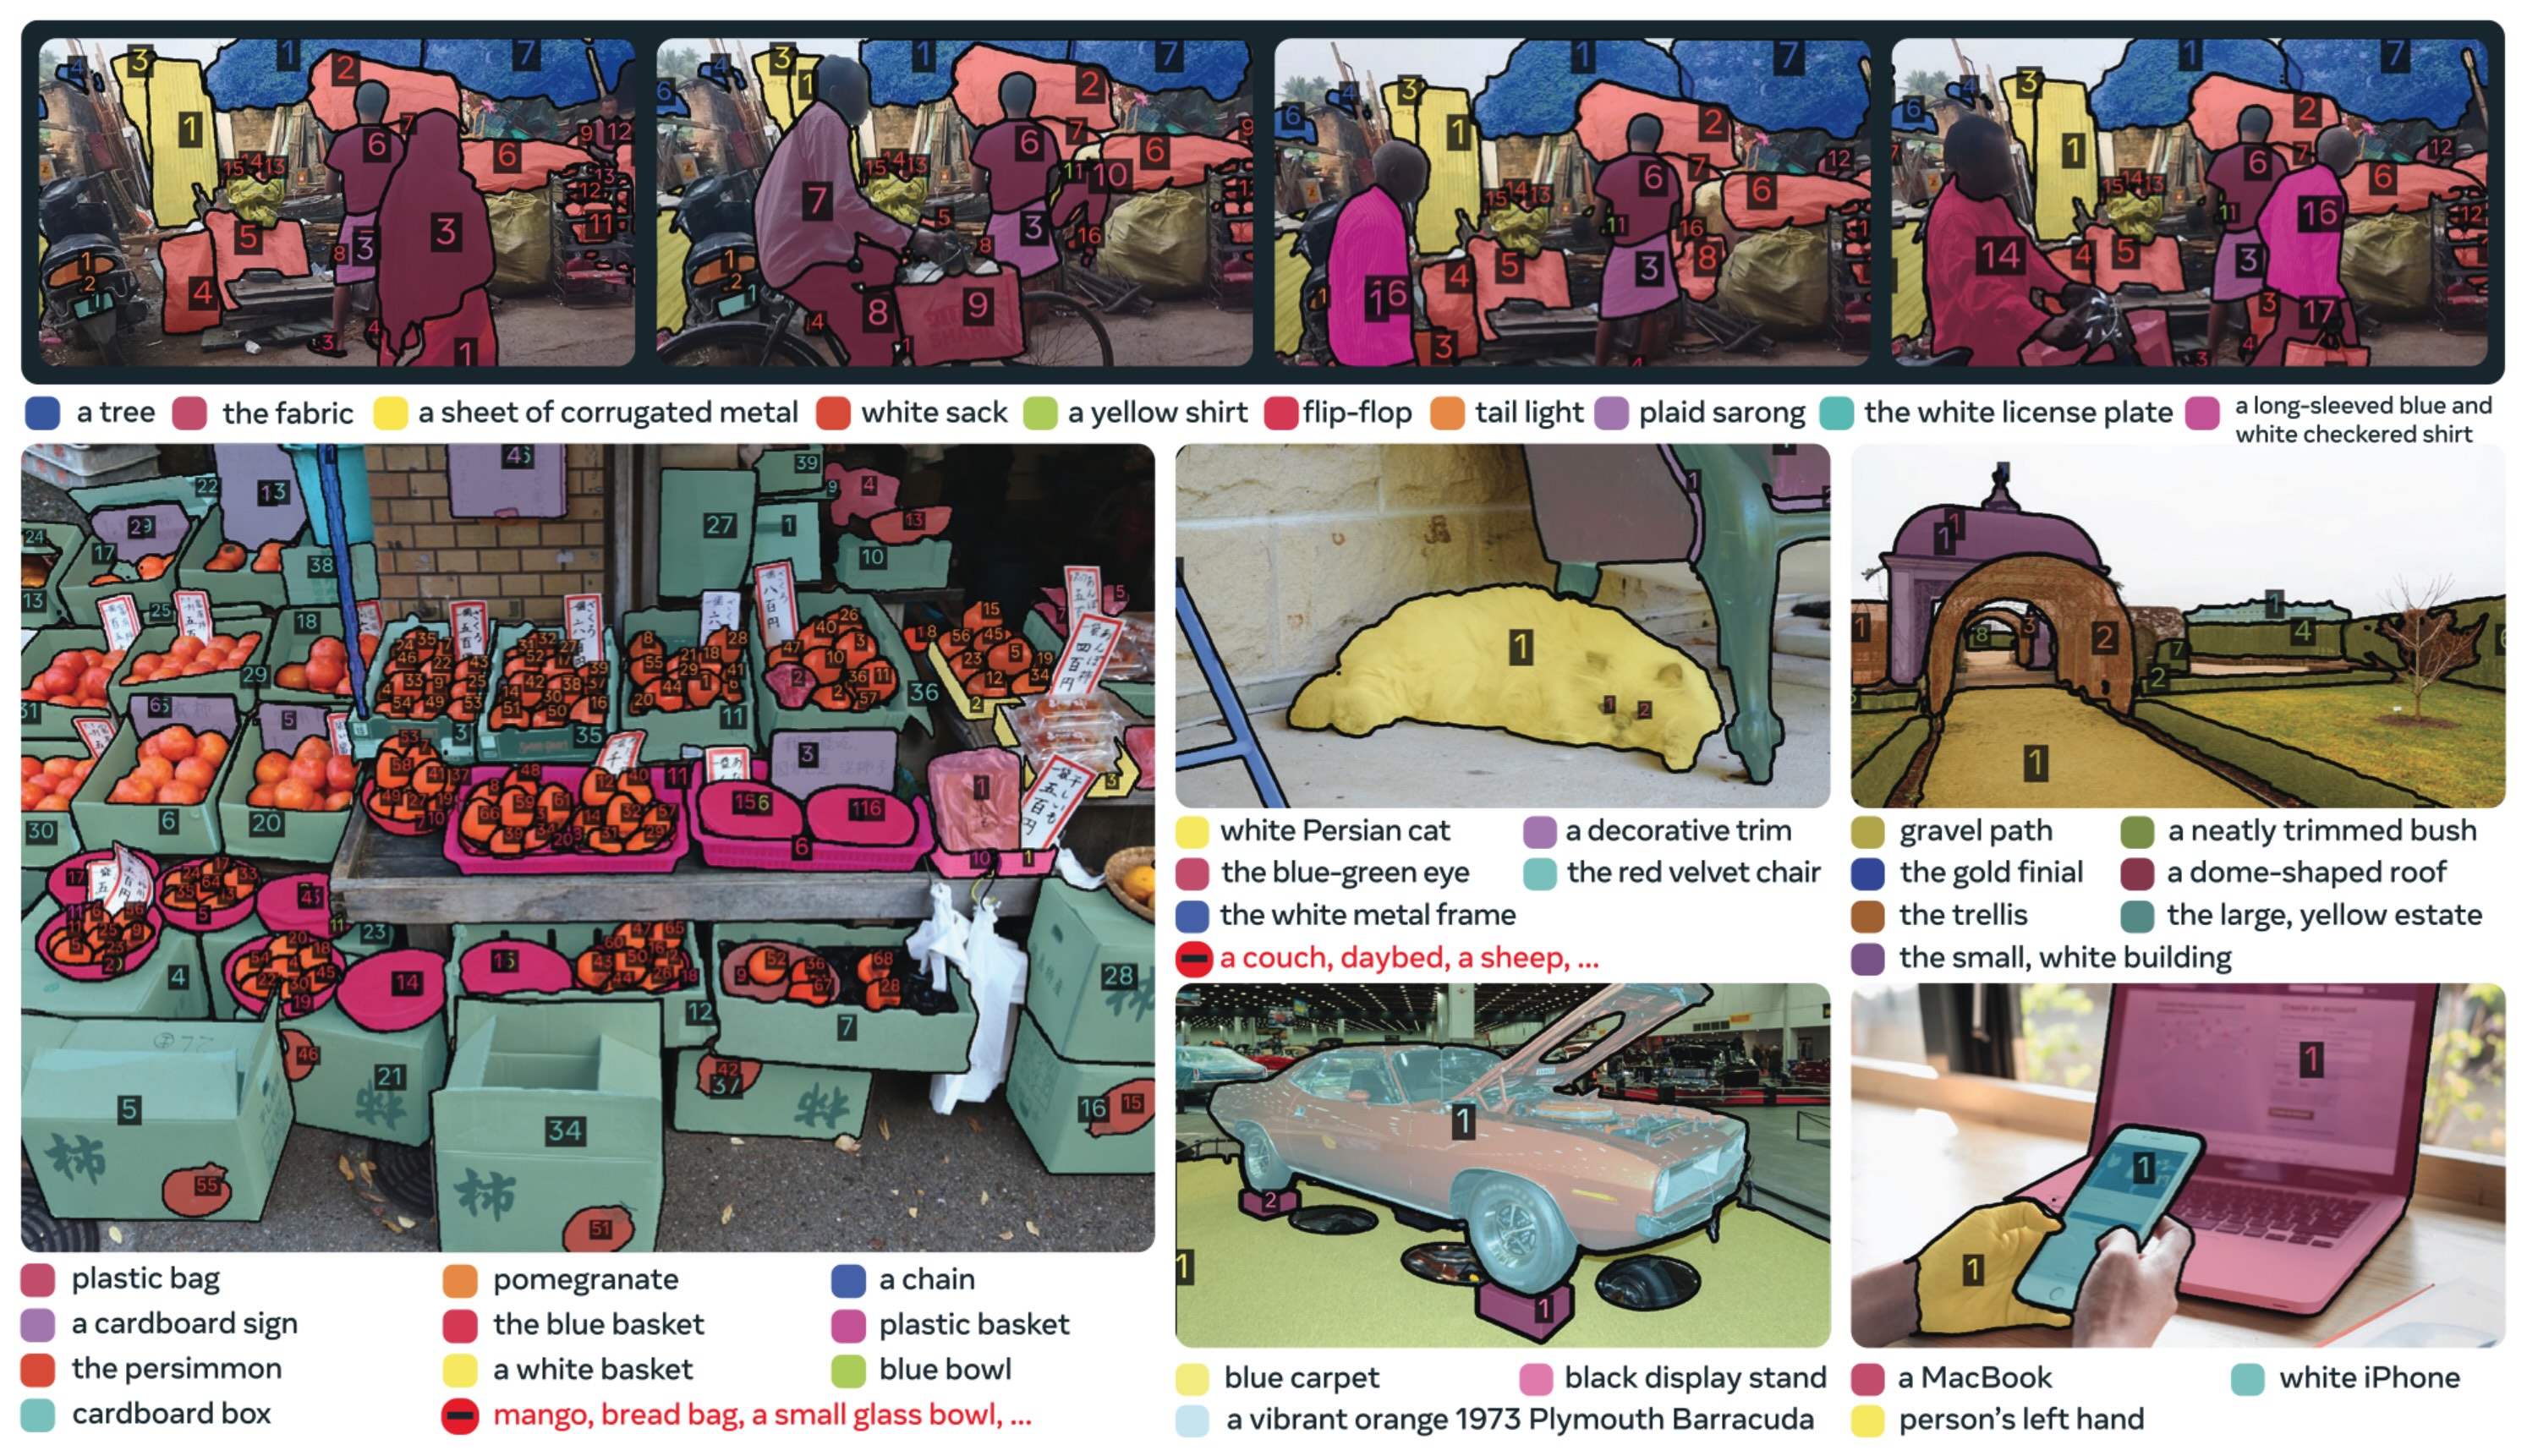
Dense open vocabulary concept masks trained on the SA-Co dataset for SAM 3. Credit: Meta AI Research.
Trained on Meta's large scale SA-Co concept dataset, SAM 3 handles nuanced film concepts including wardrobe items, vehicle parts, hand props, and lighting fixtures without custom fine tuning.
Colorists can pull instant secondary isolation mattes for faces, skies, or hero cars across a 200 frame take in seconds.
Try Meta SAM 3 Video Segmentation Live in the Browser
Test SAM 3 text prompted video segmentation directly in the embedded Hugging Face Space below (merve-sam3-video-segmentation.hf.space).
In fast sports and action sequences, SAM 3 holds tight edge boundaries around motion blurred limbs and tracks occluded subjects reliably as they re emerge behind other performers.
Pairing SAM 3 coarse masks with **MatAnyone 2** or **VideoMaMa** refines fine flying hair strands and semi transparent smoke for theatrical compositing.
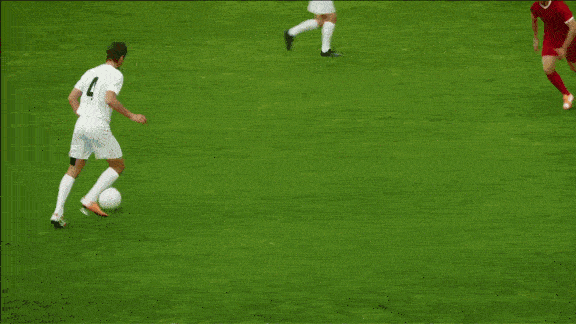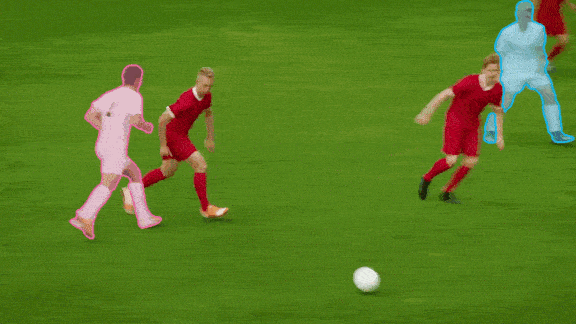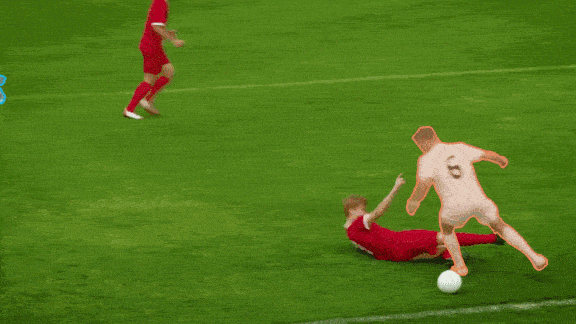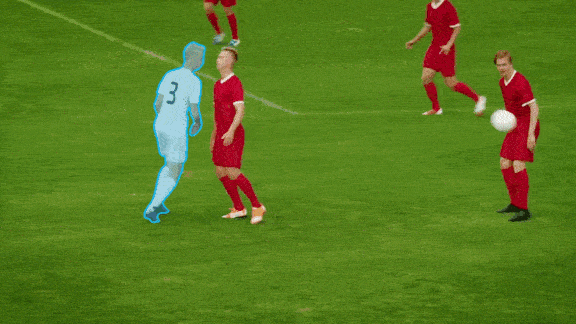
Multi instance temporal tracking on fast moving subjects in SAM 3. Credit: Meta AI Research.
Hardware and Performance Matrix
| Mode | Prompt Inputs | VRAM Needed | Target Hardware | Best VFX Use Case |
|---|---|---|---|---|
| SAM 3 Video Concept Tracking | Text phrases + optional boxes/points | 8 GB – 16 GB VRAM (BF16) |
RTX 3080 / RTX 4070 / RTX 4090 | Multi actor rotoscoping, secondary color mattes, prop isolation |
| SAM 3 Image Concept Segmentation | Text phrases + visual exemplars | 6 GB – 10 GB VRAM |
Consumer laptop GPUs | Keyframe matte extraction and inpainting mask prep |
Local Setup with Python
git clone https://github.com/facebookresearch/sam3.git
cd sam3
pip install -e .
import torch
from sam3.model_builder import build_sam3_video_predictor

predictor = build_sam3_video_predictor().to("cuda")
session = predictor.start_session(video_path="street_chase_1080p.mp4")

predictor.add_prompt(session, text="motorcycle rider in black helmet")
for frame_idx, masks in predictor.propagate_in_video(session):
    pass  # Export per frame alpha matte PNGs for DaVinci Resolve or Nuke
Filmmaker Production Playbook
- Use SAM 3 for garbage mattes, then refine hair with alpha matting. SAM 3 excels at rapid semantic isolation across crowds; feed its binary mask into MatAnyone 2 or VideoMaMa for soft feathered hair edges.
- Isolate lighting zones for color grading. Pull clean
"sky","actor face", and"wet street"matte passes to grade foreground talent and background environments independently without hand drawing power windows. - Harmonize composites with LBM. Drop your SAM 3 cutout onto a new plate and run LBM Relighting in 1 step so rim light and shadows match.
Related Reading
- MatAnyone 2: Open Source Video Matting
- VideoMaMa: Open Source Mask Guided Video Matting
- LBM Relighting & FLUX.2-Klein Relight Brush: VFX AI
- Depth Anything 3: Open Source Metric Depth for VFX


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)