

Alibaba Tongyi Lab — CosyVoice 3.0 zero shot multilingual speech generation architecture
Share this post:
Fun-CosyVoice 3.0: Open Source Multilingual Voice AI
Fun-CosyVoice 3.0 (FunAudioLLM/Fun-CosyVoice3-0.5B, Apache 2.0 License) is Alibaba Tongyi Lab's compact 0.5 billion parameter zero shot multilingual speech foundation model engineered for cross lingual film dubbing, dialect faithful character voices, and ultra low latency streaming synthesis. Built on a refined supervised speech tokenizer and flow matching acoustic decoder, Fun-CosyVoice3-0.5B runs smoothly in under 4 GB of VRAM while preserving natural speaker identity across nine major languages and regional accents.
Studio availability. Try the public Hugging Face demo below; Fun-CosyVoice 3.0 is not part of a paid AI FILMS Studio plan (use the AI Voice Generator in the voice workspace for example instead).
Why Compact 0.5B Apache 2.0 Models Win in Post Production
Heavy multi billion parameter speech models often require dedicated 16 GB GPUs just to generate scratch dialogue for an animatic, competing for VRAM with local video and image generators on the same workstation.
Fun-CosyVoice 3.0 keeps resource overhead tiny while improving international localization accuracy:
- Cross lingual zero shot voice cloning. Supply a 5 second English or Spanish actor clip and synthesize fluent dialogue in Chinese, Japanese, Korean, German, French, Italian, or Russian while maintaining consistent vocal timbre.
- Instruction steered prosody and dialects. Guide speaking pace, whispering, laughter, or regional accents directly via short natural language instructions without training speaker LoRAs.
- Bi directional streaming synthesis. First packet latency drops into interactive ranges so directors and voice actors can audition alternate script lines in real time on a laptop GPU.
- Apache 2.0 commercial clearance. Both code and
Fun-CosyVoice3-0.5Bweights carry the permissive Apache 2.0 license.
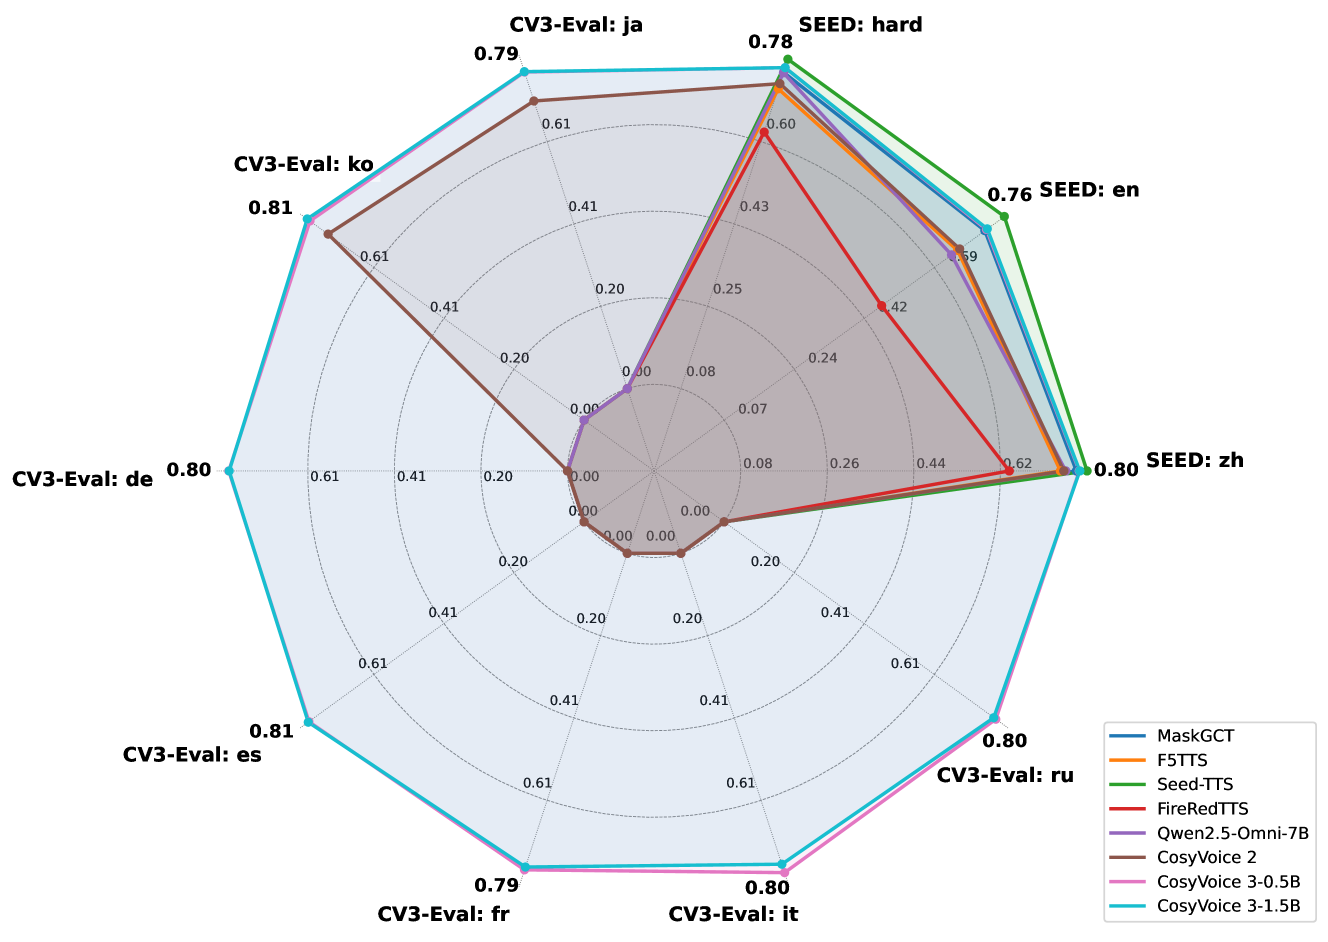
CosyVoice 3.0 speech tokenization and flow matching waveform reconstruction pipeline. Credit: Alibaba Tongyi Lab (Apache 2.0).
Scaling multilingual pretraining data sharply reduces pronunciation errors on technical film terminology, foreign character names, and rapid code switched dialogue.
Because the model occupies under 4 GB of VRAM, editors can keep it loaded alongside local video editing tools without swapping weights.
Try Fun-CosyVoice 3.0 Live in the Browser
Test Fun-CosyVoice3-0.5B directly in Alibaba Tongyi Lab's official Hugging Face Space below (funaudiollm-fun-cosyvoice3-0-5b.hf.space).
Hardware and Specification Matrix
| Metric | Fun-CosyVoice3-0.5B Spec | Production Benefit |
|---|---|---|
| Parameters | 0.5B |
Runs simultaneously alongside local video/image models |
| VRAM Needed | 2.5 GB – 4 GB VRAM (FP16) |
Fits on consumer laptops and modest GPUs |
| Streaming Mode | Supported (low latency chunking) | Instant line auditions during editorial sessions |
| License | Apache 2.0 | Commercial film, trailer, and localization use permitted |
Local Setup with Python
git clone --recursive https://github.com/FunAudioLLM/CosyVoice.git
cd CosyVoice
pip install -r requirements.txt

huggingface-cli download FunAudioLLM/Fun-CosyVoice3-0.5B --local-dir ./pretrained_models/Fun-CosyVoice3-0.5B
import torchaudio
from cosyvoice.cli.cosyvoice import AutoModel

model = AutoModel(model_dir="./pretrained_models/Fun-CosyVoice3-0.5B")

for i, out in enumerate(
    model.inference_zero_shot(
        tts_text="The lighthouse beam cut through the fog three seconds before the siren sounded.",
        prompt_text="Transcript of the five second reference clip.",
        prompt_wav="./cast/narrator_ref_24k.wav",
        stream=False,
    )
):
    torchaudio.save(f"narrator_take_{i}.wav", out["tts_speech"], model.sample_rate)
Filmmaker Production Playbook
- Always match
prompt_textverbatim to your reference WAV. Providing an accurate transcript of the 5 second actor clip improves consonant crispness and cross lingual accent fidelity. - Use for fast international trailer localization. Generate English, Spanish, French, and Japanese teaser voiceovers from one approved narrator clip (with written voice talent clearance) in minutes.
- Pair with IndexTTS-2.5 for tight lip sync windows. Use Fun-CosyVoice 3.0 for fast narrative voiceovers and IndexTTS-2.5 whenever a line must hit an exact millisecond picture cut.
Related Reading
- IndexTTS-2.5 & 2.0: Open Source Duration & Emotion TTS
- Ming-3.0-tts: Open Source Voice Design & Cloning
- MOSS-TTS Local Transformer v1.5: Open Source Voice Cloning
- Dots TTS: Open Source Streaming Voice Cloning


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)