

Tencent ARC WorldCrafter (arXiv:2609.24984) and Tencent Hunyuan Hy-Nomas (arXiv:2610.36729, Apache 2.0)
Share this post:
WorldCrafter & Hy-Nomas: Open Source 3D World Video AI
WorldCrafter (TencentARC/WorldCrafter, arXiv:2609.24984) and Hy-Nomas (Tencent-Hunyuan/Hy-Nomas, arXiv:2610.36729) are two late 2026 open source video world models that let directors initialize a virtual set from a single concept image or text prompt and explore it across multi turn camera moves and plot actions without losing spatial continuity. Released under the Apache 2.0 license (tencent/Hy-Nomas) with single RTX 4090 low memory inference, LoRA fine tuning, and an active Hugging Face Gradio Space (Drexubery/worldcrafter-demo), the two frameworks bring persistent 3D memory to generative previsualization.
Studio availability. WorldCrafter and Hy-Nomas are not available in AI FILMS Studio. This article covers public research releases from September and October 2026. To generate scenes or animate camera moves from reference images in the Studio, see the models listed on the Image to Video, Text to Video, and Motion Control pages.
WorldCrafter executing multi action scene exploration while preserving room layout and object positions
360 degree courtyard camera orbit with implicit 3D aware memory preventing architectural drift
Solving Spatial Amnesia in Interactive Video World Models
When a virtual camera pans left across a film set, explores a hallway, and pans back right 10 seconds later, standard video generators suffer from spatial amnesia. Windows move, furniture disappears, and lighting changes because 2D temporal attention only remembers recent frames unless an explicit or implicit 3D memory bank anchors the scene.
Explicit 3D point cloud caches work well for rigid static rooms, yet they struggle when actors, vehicles, smoke, or water move dynamically inside the world while the camera orbits.
WorldCrafter (September 2026, 143 Hugging Face upvotes, 557 GitHub stars) and Hy-Nomas (October 27, 2026, 108 Hugging Face upvotes, 584 GitHub stars, Apache 2.0) solve persistent interactive world generation through two complementary designs.
- Implicit 3D aware spatial memory (
WorldCrafter,arXiv:2609.24984). Instead of rasterizing brittle depth maps at every step, WorldCrafter encodes previously visited viewpoints into an implicit 3D aware latent memory bank conditioned on 6-DoF camera extrinsics. When the camera revisits an angle or orbits around a moving subject, the Diffusion Transformer retrieves view aligned memory tokens to keep walls, props, and lighting locked while allowing dynamic action inside the room. - Multi turn text and camera interactive world generation (
Hy-Nomas,arXiv:2610.36729). Released under Apache 2.0 (tencent/Hy-Nomas), Hy-Nomas lets a director upload a single reference image (added October 31, 2026) or start from text, then steer the world turn by turn using simultaneous natural language event prompts and 6-DoF camera controls (W/A/S/Dtranslation plus pan and tilt). - Single RTX 4090 low-VRAM execution and LoRA training. Unlike multi node world simulators that demand 4x or 8x H100 clusters,
Hy-Nomasincludes a low memory inference mode that runs on a single 24 GB RTX 4090, supportsSGLangserving (sgl-project/sglang#46124), and provides LoRA fine tuning scripts for custom film sets.
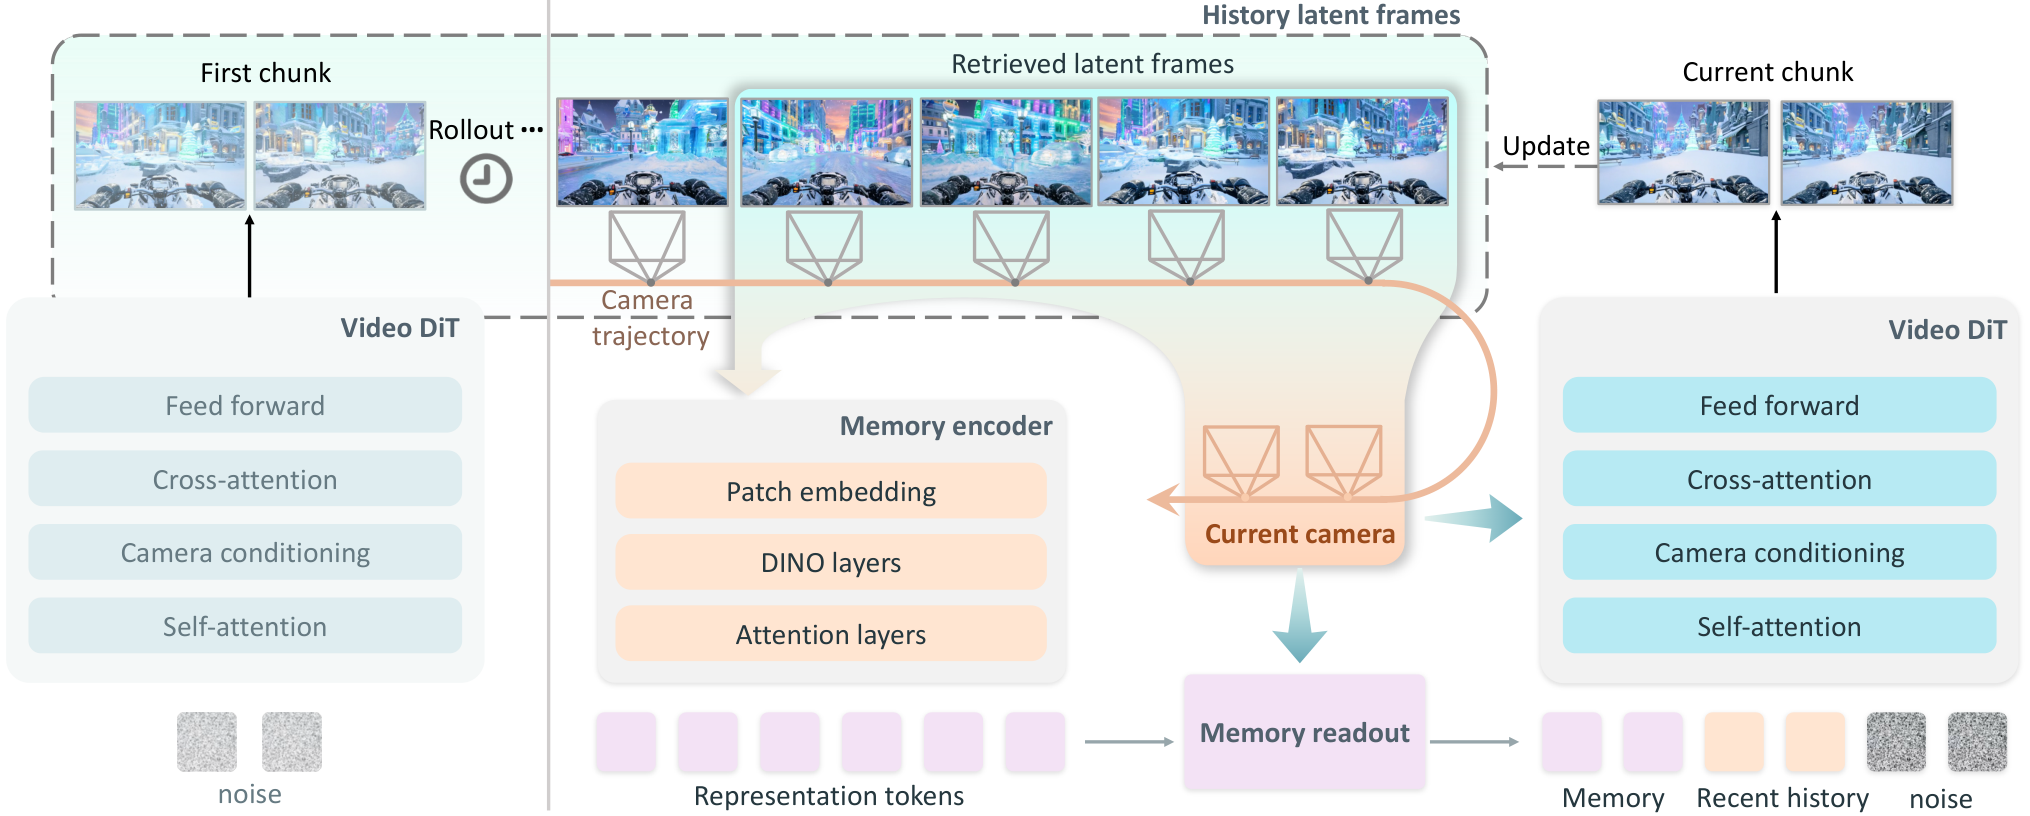
WorldCrafter architecture pairing implicit 3D aware memory with action and camera trajectory conditioning. Credit: Tencent ARC WorldCrafter (arXiv:2609.24984).
By storing scene history in a 3D pose indexed latent representation rather than a static mesh, WorldCrafter supports both novel view synthesis around static architecture and dynamic object interactions.
Directors can test how a room looks from four different camera corners without rebuilding the environment in a 3D DCC tool.
Try WorldCrafter Live in the Browser
Test the official WorldCrafter interactive Gradio Space embedded below (drexubery-worldcrafter-demo.hf.space), which loads directly in the browser without login.
To evaluate interactive world models rigorously, the Hy-Nomas team also open sourced `Hy-Nomas-Bench` (`tencent/Hy-Nomas-Bench` on Hugging Face), measuring multi turn instruction following, spatial loop closure, and visual fidelity across indoor and outdoor environments.
In community workflows showcased in November 2026, filmmakers initialize an environment plate in `Hy-Nomas`, record a multi turn camera walkthrough, and pass the resulting video into an audio and video model such as `LTX-2.5` or `Kling-Foley` to attach synchronized footsteps and ambient sound.
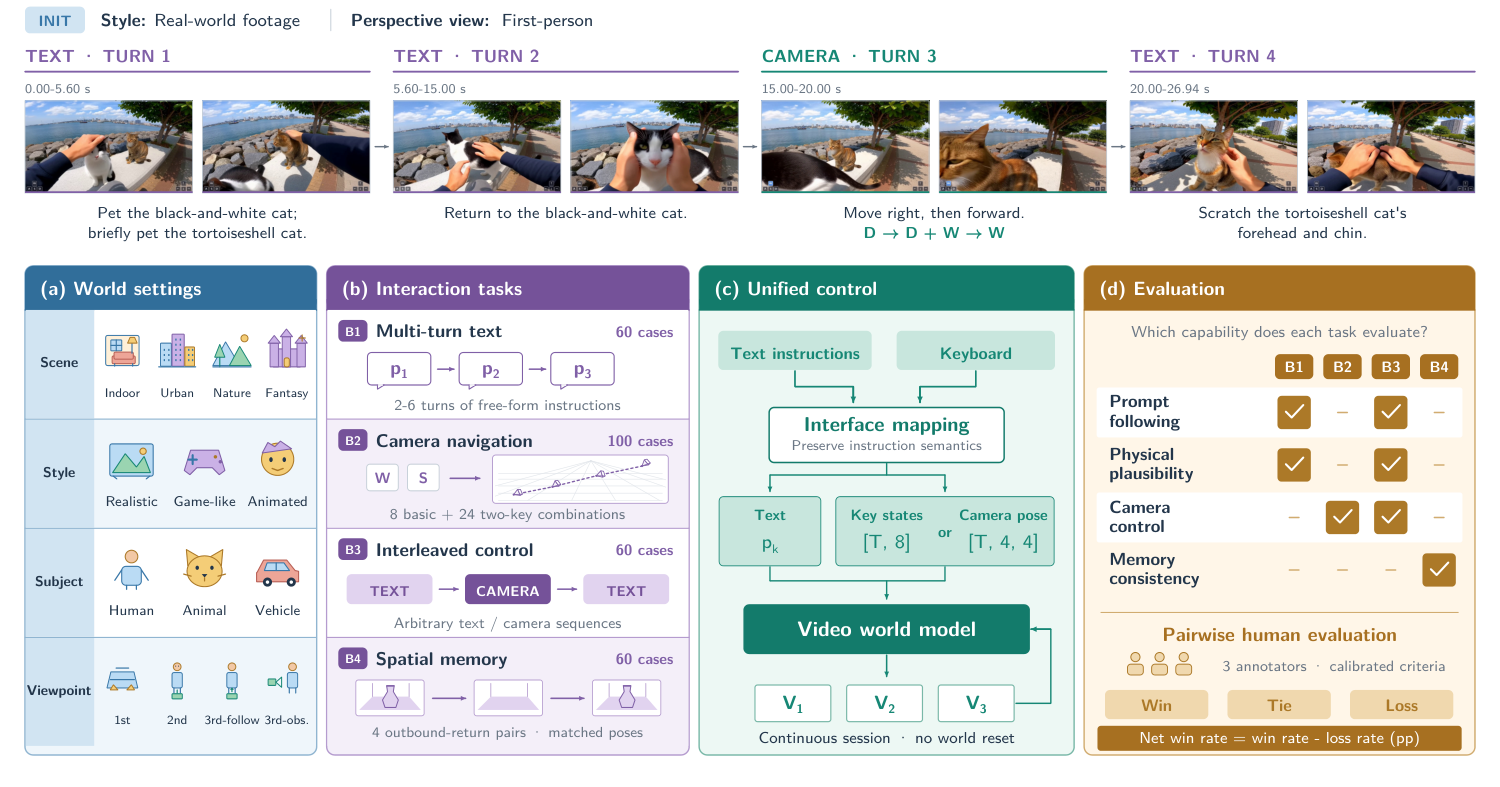
Hy-Nomas multi turn text and camera interactive world generation and benchmark tasks. Credit: Tencent-Hunyuan/Hy-Nomas (Apache 2.0).
Model Comparison, Hardware & License Matrix
| Model / Suite | Repository & Weights | Control Modalities | Minimum Hardware & VRAM | License |
|---|---|---|---|---|
Hy-Nomas (arXiv:2610.36729) |
Tencent-Hunyuan/Hy-Nomas (tencent/Hy-Nomas) |
Reference image + multi turn text prompts + 6-DoF camera | Single 24 GB RTX 4090 (low memory mode) + LoRA training | Apache 2.0 |
WorldCrafter (arXiv:2609.24984) |
TencentARC/WorldCrafter |
Text / Image to World + 6-DoF camera + action controls | 24 GB to 40 GB VRAM | Open Research |
NVIDIA GEN3C |
nv-tlabs/GEN3C (nvidia/GEN3C-Cosmos-7B) |
Explicit 3D point cloud cache + 6-DoF camera trajectory | 16 GB (SVD) to 28 GB+ (Cosmos-7B) | Apache 2.0 / NVIDIA |
NVIDIA SANA-WM |
NVlabs/Sana |
60 second 720p world generation with 6-DoF camera | 8 GB to 24 GB VRAM | Apache 2.0 |
Running Hy-Nomas and WorldCrafter Locally
To run Hy-Nomas under Apache 2.0 on a single 24 GB RTX 4090 or via SGLang, clone Tencent-Hunyuan/Hy-Nomas and download tencent/Hy-Nomas from Hugging Face.
git clone https://github.com/Tencent-Hunyuan/Hy-Nomas.git
cd Hy-Nomas
pip install -r requirements.txt

# Download Apache 2.0 Hy-Nomas weights from Hugging Face
huggingface-cli download tencent/Hy-Nomas --local-dir ./ckpts/Hy-Nomas

# Launch the interactive web demo starting from a reference location image on a single RTX 4090
python apps/demo_server.py \
  --ckpt_dir ./ckpts/Hy-Nomas \
  --low_vram \
  --init_image assets/concept_alley.png \
  --port 7860
To run batch multi turn world trajectories from the command line, pass a sequence of text actions and camera pose transitions.
python infer_multiturn.py \
  --ckpt_dir ./ckpts/Hy-Nomas \
  --low_vram \
  --init_image assets/concept_alley.png \
  --turns "Camera dollies forward down the neon alley|A cyberpunk courier walks out from the side doorway|Camera pans left to follow the courier" \
  --output outputs/alley_multiturn.mp4
For WorldCrafter (TencentARC/WorldCrafter), clone https://github.com/TencentARC/WorldCrafter.git to run 3D memory conditioned novel view and image-to-world trajectories.
Production Playbook for Filmmakers
- Scout virtual locations from a single concept frame. Generate a hero environment concept image, feed it into
Hy-Nomaswith--low_vramon an RTX 4090, and walk the virtual camera through the room to capture wide, medium, and reverse shot plates that share identical set architecture. - Use multi turn text prompts for staged blocking. Unlike static 3D Gaussian Splat worlds where nothing in the environment can change,
Hy-Nomaslets you trigger weather shifts, door openings, or character entrances on Turn 2 and Turn 3 while keeping the camera moving. - Compare across open source 3D and world models. Read our companion guides on NVIDIA GEN3C 3D point cloud cache camera control, NVIDIA SANA-WM 60-second world video model, HY-World 2.0 360 panorama and 3D world generation, and WorldClaw agentic 3D world generation.
To turn location frames into high resolution shots in the cloud without local setup, open the Image to Video, Start to End Frame, and Motion Control pages, or chain world plates and video upscalers visually in the Nodes Graph Editor.


Sources
- Tencent-Hunyuan/Hy-Nomas Official GitHub Repository (Apache 2.0)
- Hy-Nomas: Towards Free-Form Interactive World Generation (arXiv:2610.36729)
- tencent/Hy-Nomas Model Card & Weights on Hugging Face
- TencentARC/WorldCrafter Official GitHub Repository
- WorldCrafter Official Project Page
- WorldCrafter: Consistent Video World Model with Implicit 3D-Aware Memory (arXiv:2609.24984)
- Drexubery/worldcrafter-demo Interactive Space on Hugging Face
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)