

AI FILMS hardware matrix from FastVideo/FastVideo-FastH3-Omni-8-Step-V1 README
Share this post:
FastH3-Omni: Open Source 8 Step Audio Video AI
Multi reference audio video models normally require multi GPU server racks and dozens of denoising steps per shot. FastH3-Omni (FastVideo/FastVideo-FastH3-Omni-8-Step-V1), developed jointly by FastVideo and Nuva Lab as an 8 step distilled student of MiniMax-H3, generates 24 FPS video with synchronized 32 kHz stereo audio from up to 12 combined image, video, and audio references. With official NVFP4 QAD weights for NVIDIA RTX 5090 and DGX Spark alongside FP8 recipes for RTX 4090, it brings reference conditioned audio video generation onto single workstation GPUs.
Studio availability. Try the public Hugging Face demo below; FastH3-Omni is not part of a paid AI FILMS Studio plan (use MiniMax H3 Text to Video in the video workspace for example instead).
Try FastH3-Omni Live
Assemble ordered <Picture 1>, <Video 1>, and <Audio 1> references inside the official FastVideo Space below. The embed expands automatically to full interface height so the reference tray, six section prompt builder, and video player stay fully accessible.
Architecture and Technical Design
FastH3-Omni distills the MiniMax-H3 reference to video and audio (ref2va) transformer down to eight transformer evaluations at guidance_scale=1.0. The Space deployment runs the FP8 W8A8 export paired with FastVideo's Triton tile 64 block sparse attention kernels, cached at startup to eliminate first call compilation stalls.
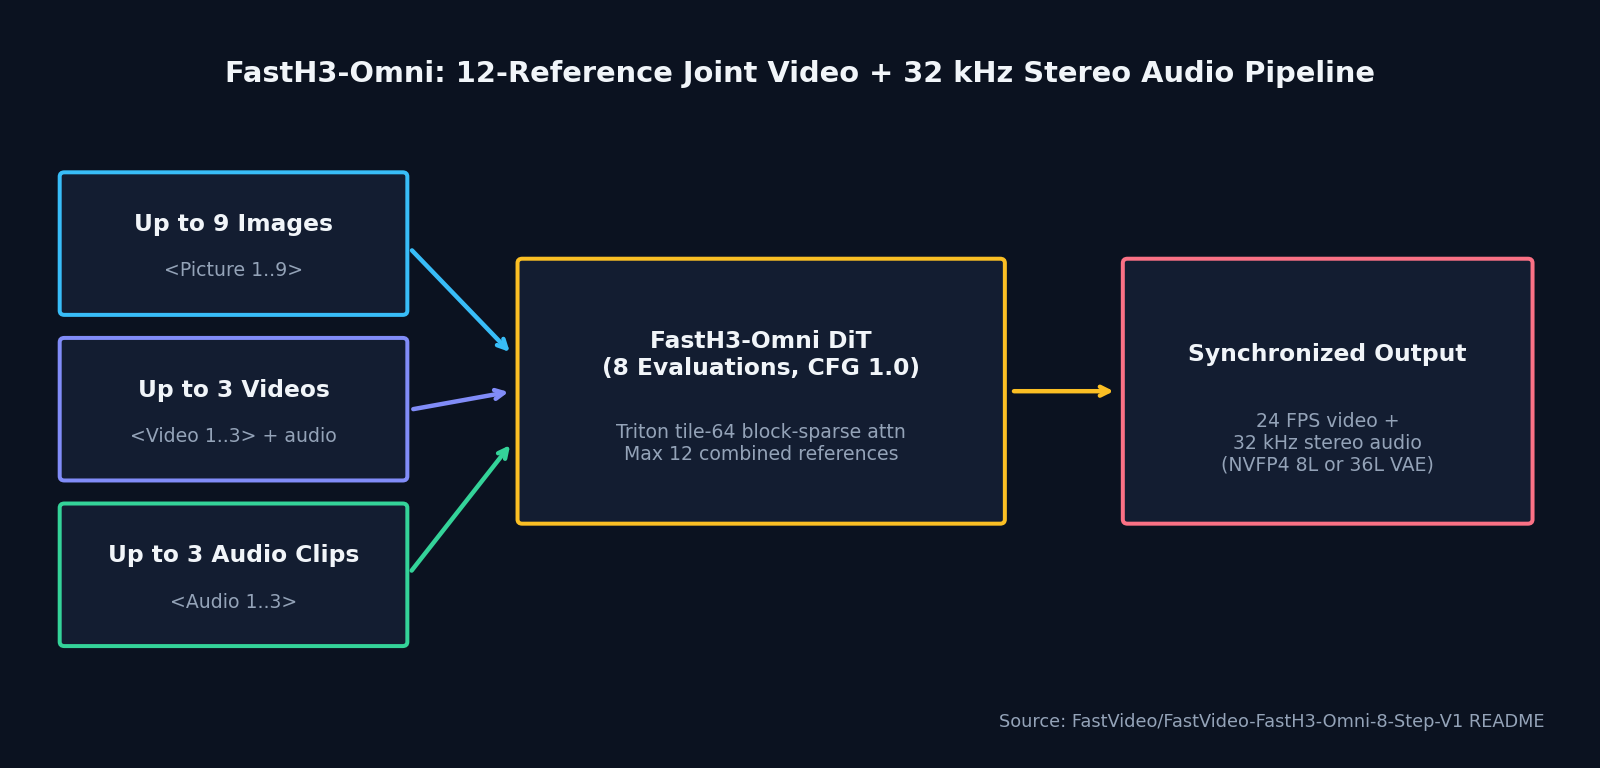
AI FILMS pipeline diagram from FastH3-Omni README
Filmmakers can condition a single generation on up to 9 images, 3 videos (including their embedded soundtracks), and 3 audio clips, capped at 12 total references (with at least one visual reference required). Inline positional tags such as <Picture 1>, <Video 1>, and <Audio 1> anchor subjects, camera motion, and voices directly inside the prompt.
Optional NVFP4 VAE decoders ship in two tiers: a 36 layer quality tier for final plates and an 8 layer fast tier for rapid pre-visualization.
Hardware, VRAM, and License Matrix
| Hardware Target | Recommended Checkpoint | Runtime & Setup | Notes |
|---|---|---|---|
| NVIDIA GB200 / B200 / RTX PRO 6000 | FastVideo-FastH3-Omni-8-Step-V1 (BF16) |
UniServe ref2va (quality preset) |
Production multi user API serving |
| NVIDIA H100 / H200 | BF16 or FastH3-OmniRef-FP8 |
UniServe server deployment | High throughput studio rendering |
| NVIDIA DGX Spark (GB10, 128 GB) | FastH3-OmniRef-NVFP4-QAD |
FastVideo spark recipe |
Keeps all model components resident at 480p |
| NVIDIA RTX 5090 (32 GB Blackwell) | FastH3-OmniRef-NVFP4-QAD |
FastVideo rtx-5090 recipe |
Offloads text encoder; uses precomputed AdaLN table |
| NVIDIA RTX 4090 (24 GB Ada) | FastH3-OmniRef-FP8 |
FastVideo rtx-4090 recipe |
Pairs FP8 DiT with BF16 text encoder (no FP4 required) |
Weights are governed by the MiniMax-H3 Community License Agreement. Review the license file on Hugging Face before deploying FastH3-Omni in commercial studio pipelines.
Parameter Reference
| Parameter / Option | Verified Value | Production Effect |
|---|---|---|
| Transformer evaluations | 8 steps |
Fixed distilled rollout for fast joint audio video output |
guidance_scale |
1.0 |
Guidance free distilled schedule |
| Max references | 12 total (up to 9 img, 3 vid, 3 audio) |
At least 1 image or video reference is required |
| Output frame rate & audio | 24 FPS + 32 kHz stereo audio |
Cinema standard 24 FPS with matched stereo sound |
--decoder |
36-layer (quality) or 8-layer (fast) |
NVFP4 VAE decoder speed vs texture sharpness trade off |
| Reference tags | <Picture n>, <Video n>, <Audio n> |
Binds exact uploaded assets to actions and sound cues |
Local Python and CLI Setup
Download the BF16 transformer (or the NVFP4 QAD / FP8 variant matching your GPU) from Hugging Face, then run it through the official hao-ai-lab/FastVideo recipes.
# Download the BF16 release checkpoint
hf download FastVideo/FastVideo-FastH3-Omni-8-Step-V1 \
  --local-dir ./FastH3-Omni-BF16

# Or download the Blackwell NVFP4 QAD checkpoint for RTX 5090 / DGX Spark
hf download FastVideo/FastH3-OmniRef-NVFP4-QAD \
  --local-dir ./FastH3-Omni-NVFP4

git clone https://github.com/hao-ai-lab/FastVideo.git
cd FastVideo
pip install -e .
Follow the device specific YAML profile (basic_fasth3_omniref_rtx5090.yaml, basic_fasth3_omniref_rtx4090.yaml, or basic_fasth3_omniref_spark.yaml) inside FastVideo/examples/inference/basic/ so attention kernels, precision flags, and shared MiniMax-H3 encoders load cleanly.
Filmmaker Production Playbook
1. Lock character, location, and sound design in one pass. Pass a hero actor portrait as <Picture 1>, a location plate as <Picture 2>, and a foley or voice timbre clip as <Audio 1>. Describing how <Picture 1> moves through <Picture 2> while triggering <Audio 1> keeps audio and visuals aligned at 24 FPS.
2. Draft with the 8 layer decoder, finish with 36 layers. During editorial blocking on an RTX 5090, run the 8 layer NVFP4 VAE decoder to test camera timing in seconds, then switch to the 36 layer decoder once you lock the winning seed.
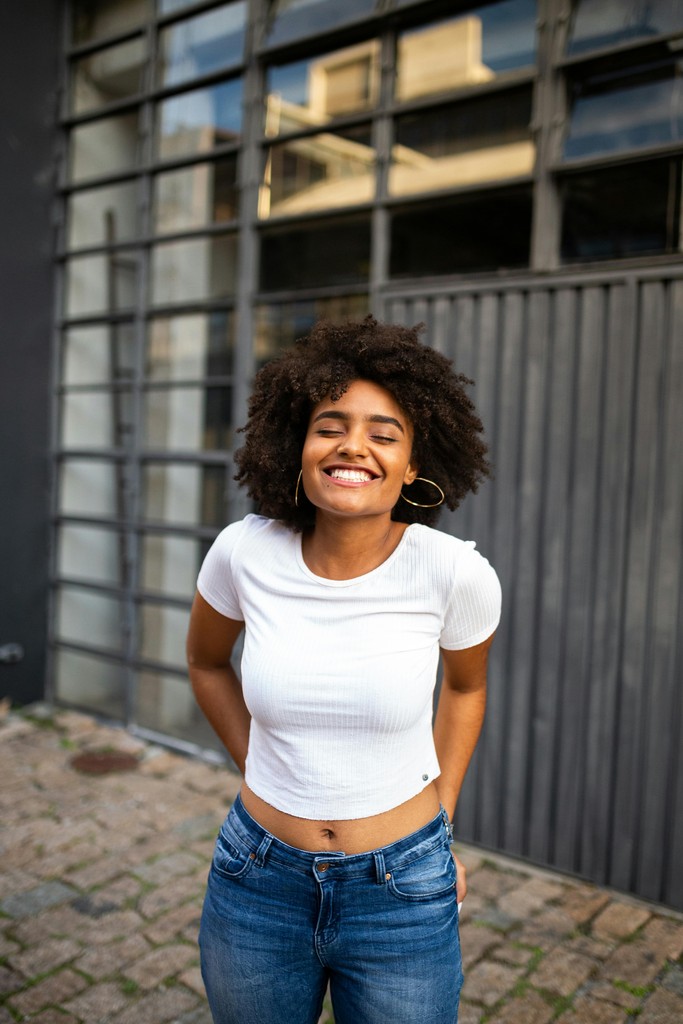
Reference example plate from FastVideo/FastH3-Omni Space
- Keep prompts structured with the six section H3 builder. The official Space includes a prompt upsampler and six section builder covering subject, motion, environment, camera, lighting, and sound cues. Writing explicit acoustic cues alongside camera moves prevents flat background hiss in the 32 kHz stereo track.
- Render cloud MiniMax H3 shots without hardware limits. When you need full resolution MiniMax H3 Text to Video, MiniMax H3 Image to Video, or MiniMax H3 Video Extend without managing local FP8/NVFP4 recipes, launch our image to video page or the video workspace.
Related Reading
- pi-H3: Open Source 2-Step Audio Video Generation
- MiniMax H3 Image: Open Weights 4K Multi Reference AI
- DMAD & DuoMatching: Open Source 4 Step Audio-Video AI
- LynnReal-Omni: Open Source 3-Step Video Editing & Control


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)