

Meituan LongCat Team, LongCat-Video-Avatar-1.6
Share this post:
LongCat-Video-Avatar 1.6: Open Source 10+ Min Lip Sync
LongCat-Video-Avatar 1.6 (meituan-longcat/LongCat-Video-Avatar-1.6, late 2026) is Meituan's upgraded 13.6 billion parameter open source audio driven human video generator built on a 48 block Diffusion Transformer (DiT) with Whisper-large-v3 audio conditioning and umT5-XXL text control. Version 1.6 directly solves the two biggest flaws in earlier talking head pipelines, exaggerated mouth jitter and long form identity drift, enabling continuous 10+ minute spoken performances in 8 denoising steps via dual DMD and OPSD LoRA mixing and official INT8 weights.
Studio availability. Try the public Hugging Face demo below; LongCat-Video-Avatar 1.6 is not part of a paid AI FILMS Studio plan (use OmniHuman or Kling Lip Sync on the Lip Sync page).
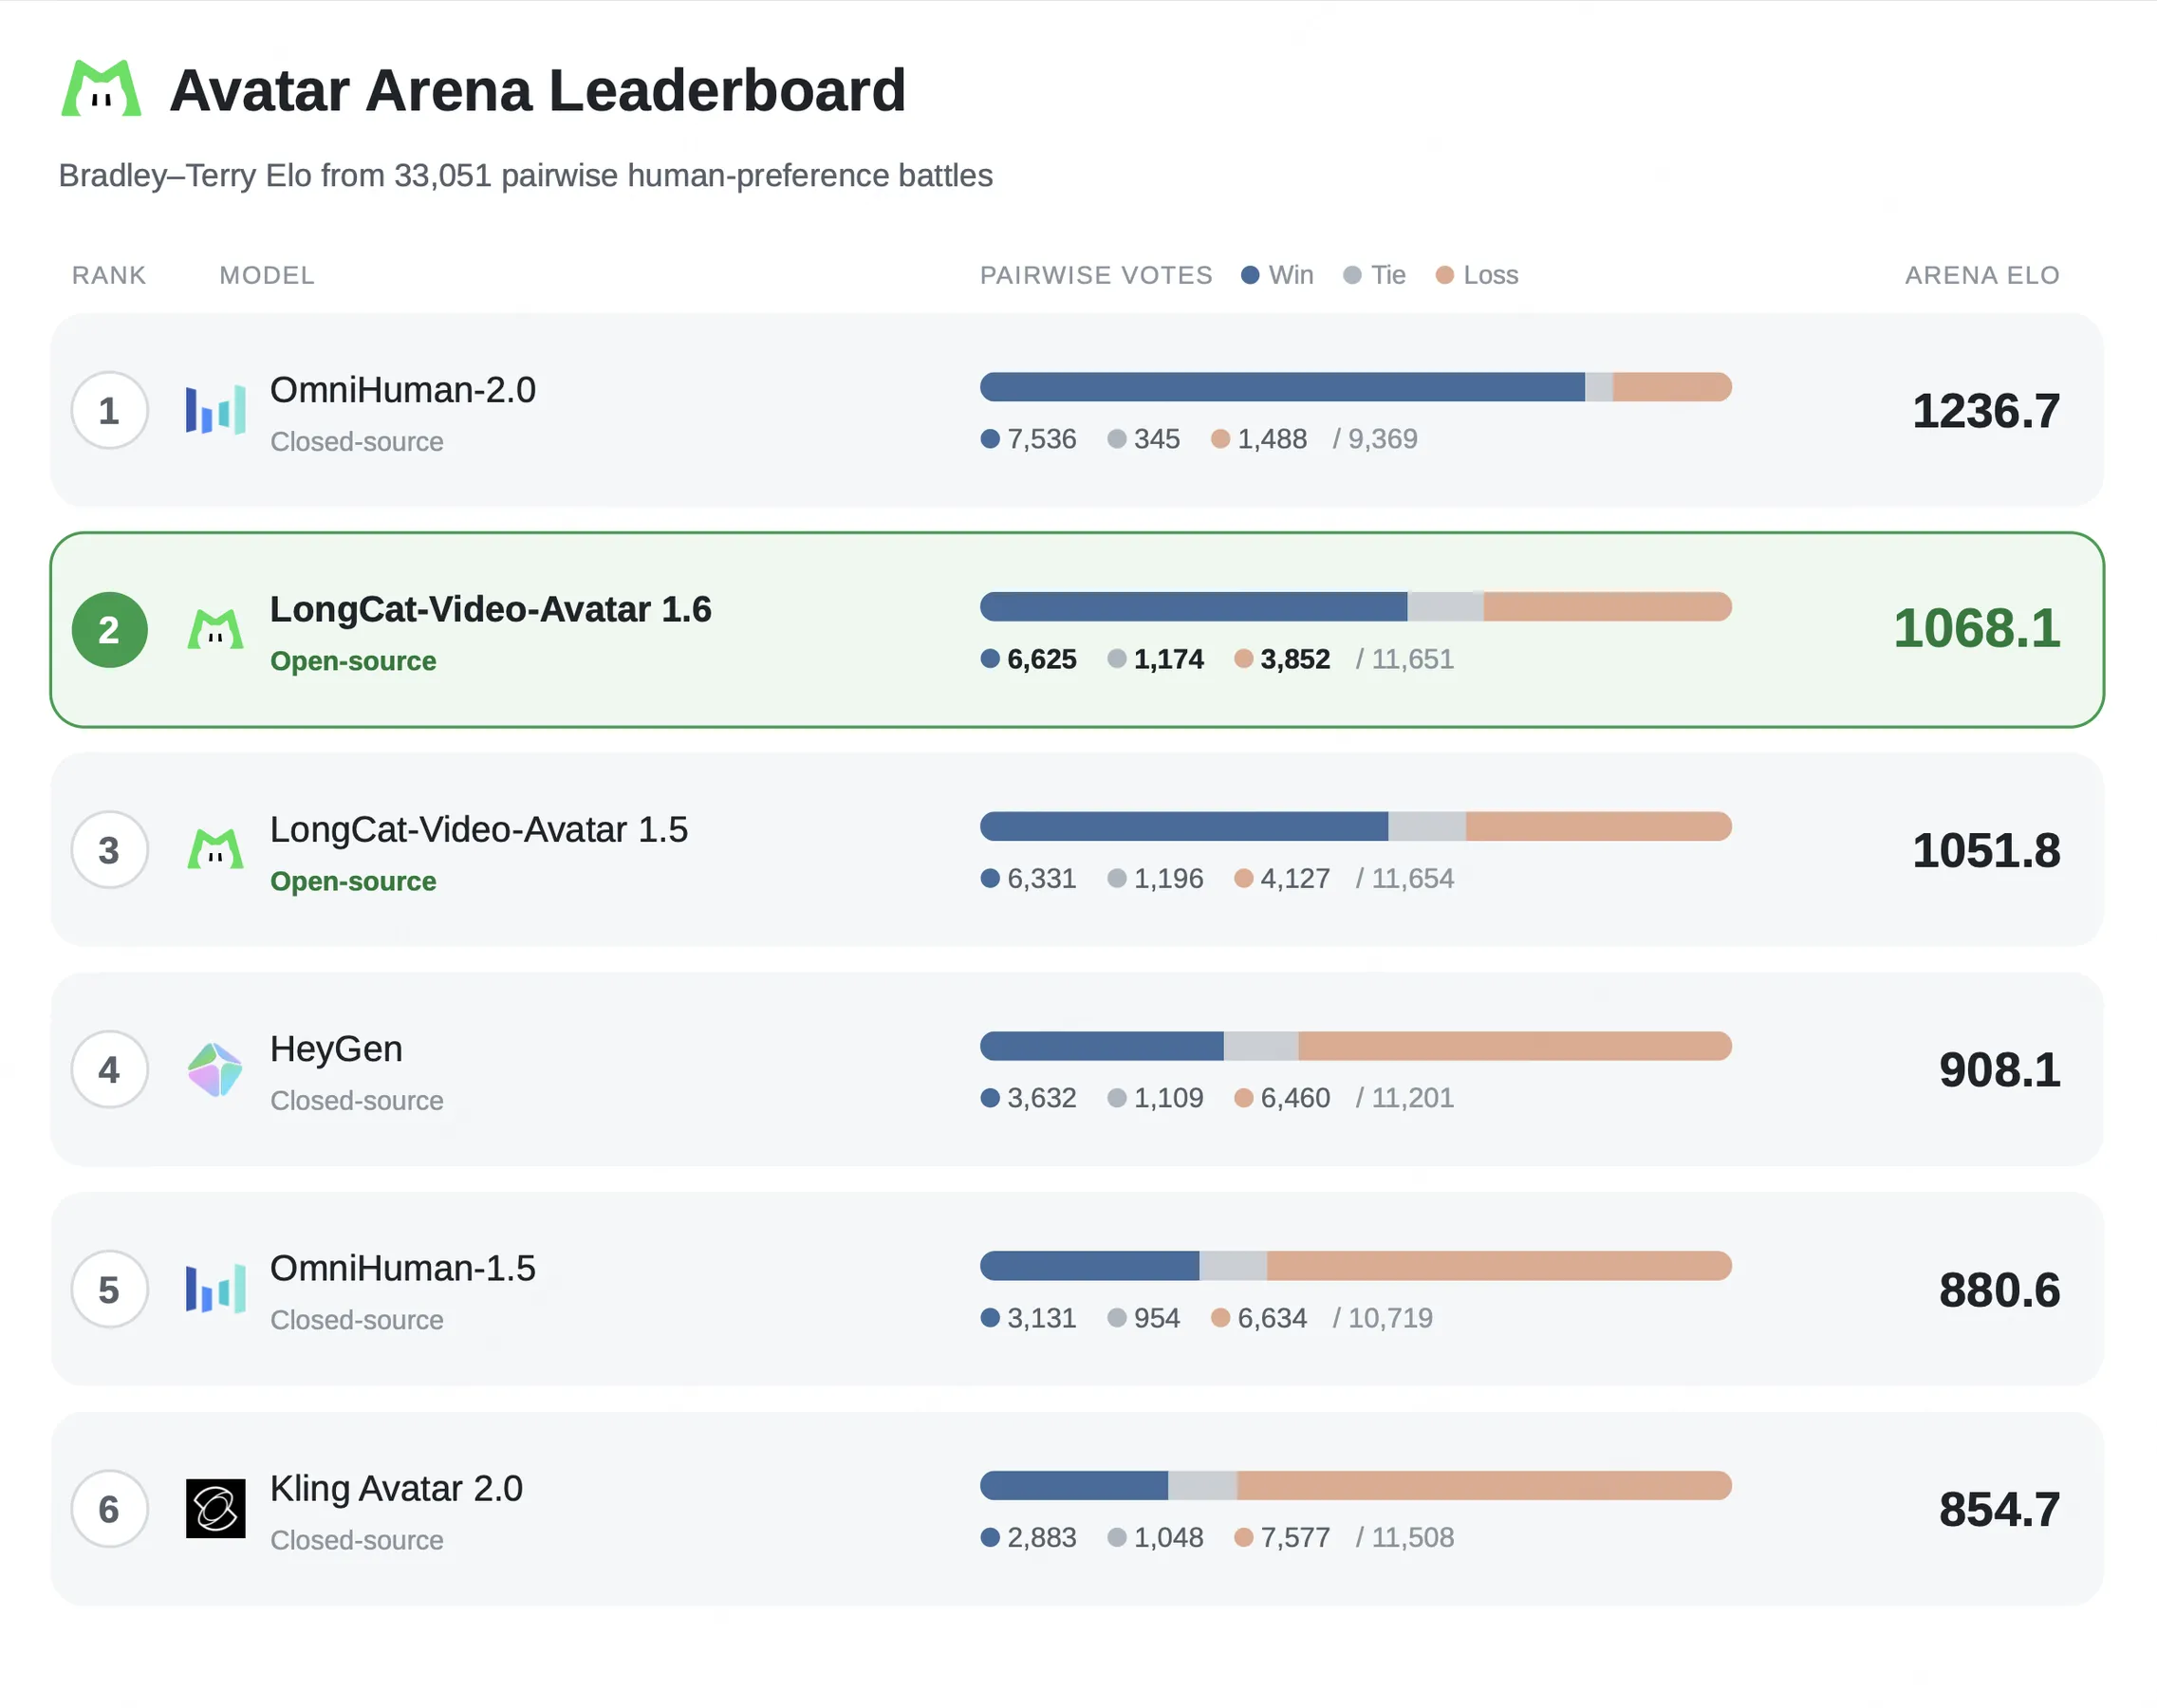
What Changed in LongCat-Video-Avatar 1.6
Version 1.5 proved that a 13.6B DiT could drive expressive upper body motion from audio alone, but long monologues still drifted in lighting and showed over pronounced jaw movement on fast plosives. Version 1.6 introduces three targeted engineering upgrades:
- Dual rank 128 LoRA mixing (
DMD+OPSD). Instead of running a single distilled adapter across all 8 steps, Version 1.6 bundlesloraA(Distribution Matching Distillation / DMD) for fast structural synthesis andloraB(On Policy Distillation / OPSD) for drift free motion stabilization. Blending DMD on the first 4 steps and switching to pure OPSD on the final 4 steps (--mix_steps 4 --mix_alpha 1.0) locks facial geometry and clothing folds across 10+ minute continuations. - Natural lip synchronization without jaw exaggeration. Updated audio cross attention calibration aligns visemes tightly with
Whisper-large-v3phoneme embeddings, removing the "rubber mouth" jitter that breaks immersion on dramatic close ups. - Official weight only
INT8DiT and Apple SiliconMLXports. Running a 13.6B DiT in raw BF16 previously demanded multi GPU nodes. Version 1.6 ships an official--use_int8DiT checkpoint that cuts VRAM pressure sharply for single workstation GPUs, alongside communityMLXports for 64 GB+ unified memory Mac studios.
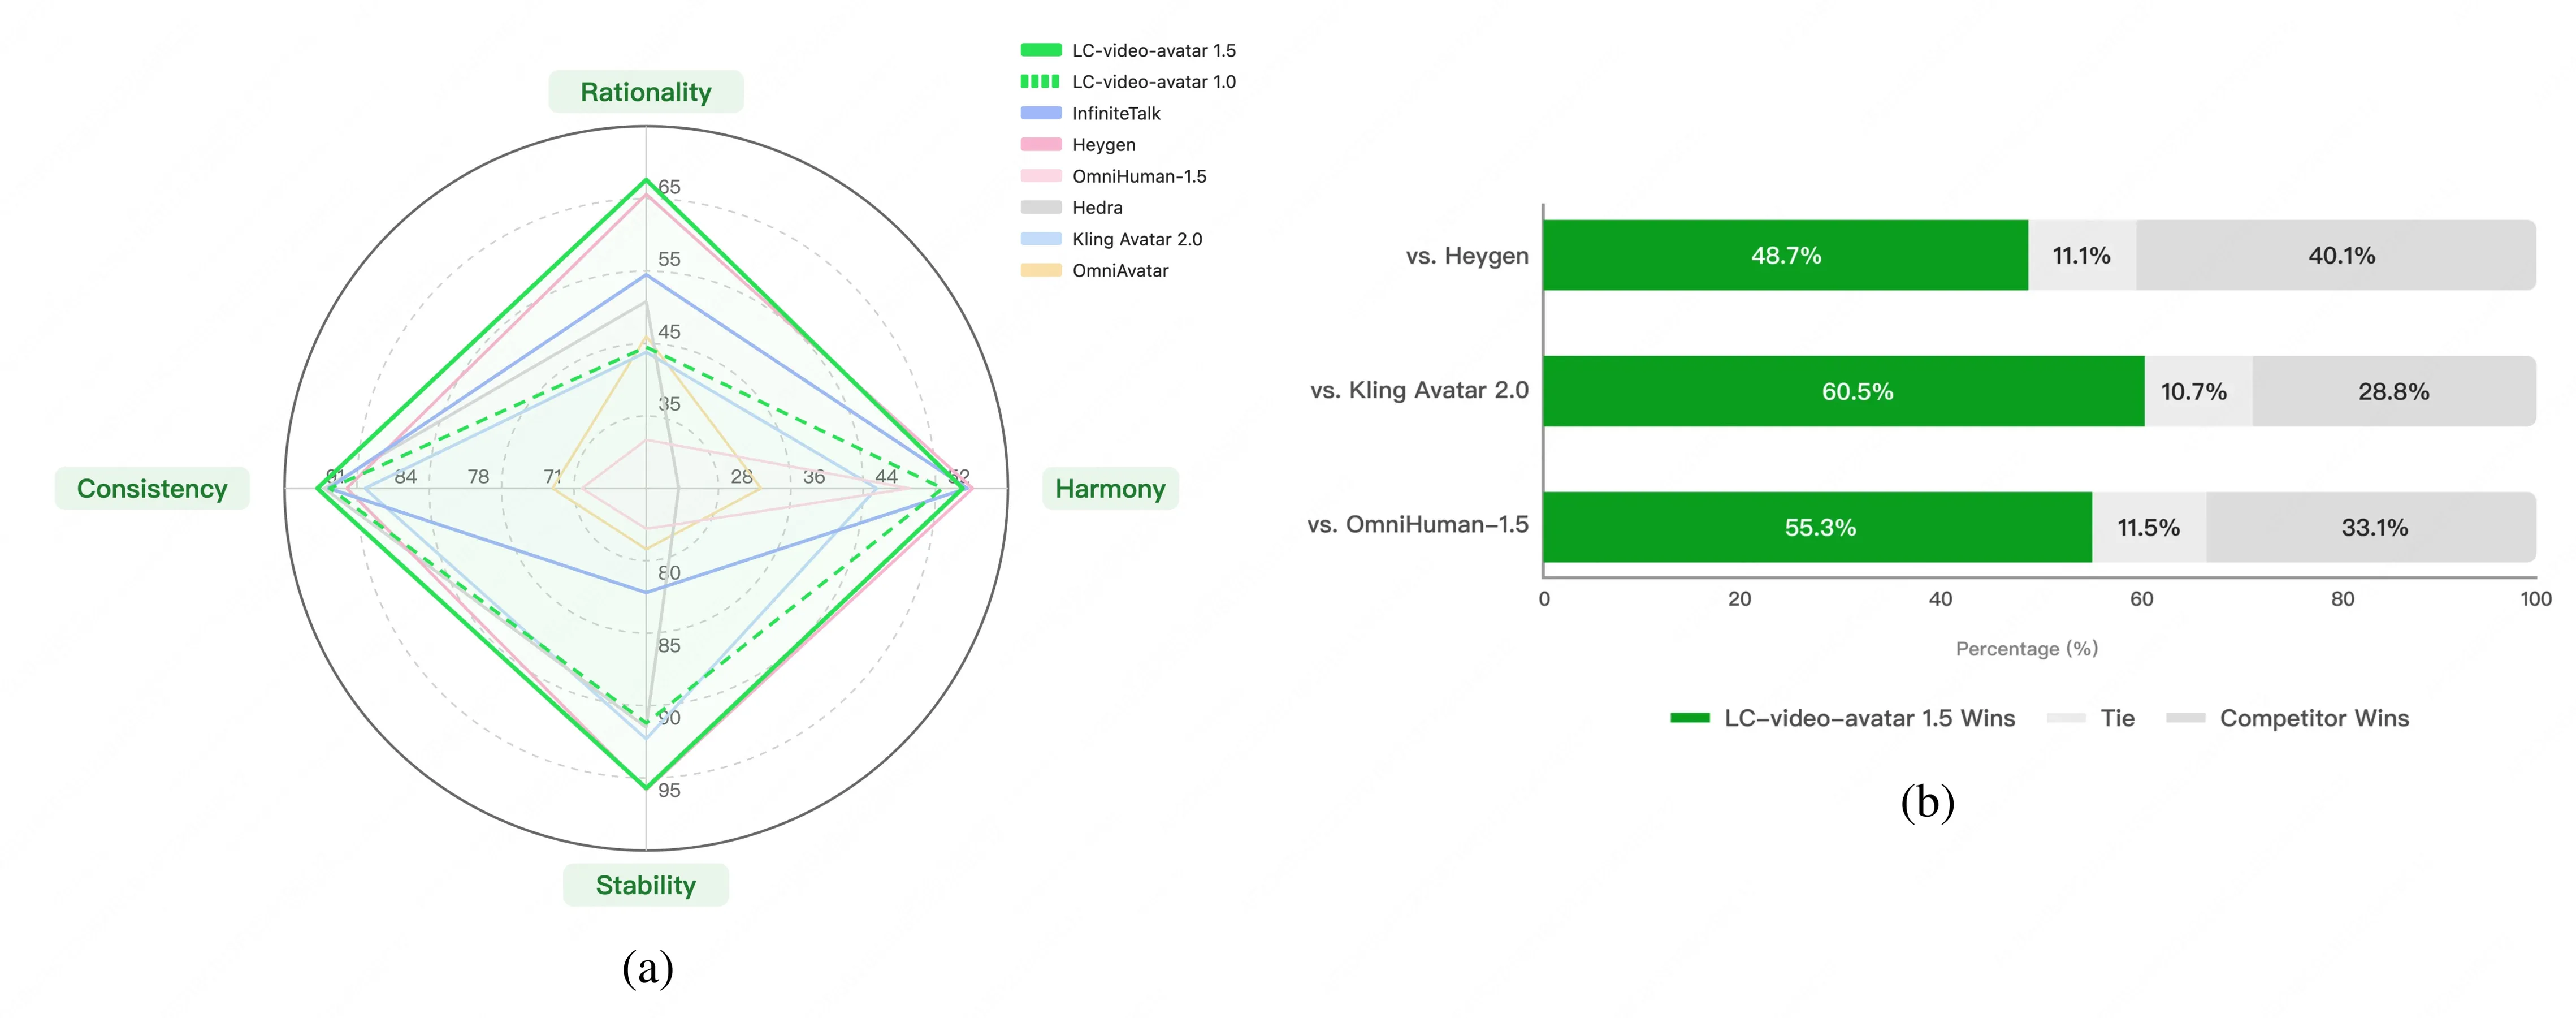
LongCat-Video-Avatar 48 block DiT architecture pairing Whisper-large-v3 audio conditioning with Wan 2.1 VAE latents. Credit: Meituan LongCat.
By conditioning all 48 DiT blocks on Whisper-large-v3 acoustic frames alongside reference portrait latents, the model coordinates micro expressions, eyebrow raises, and shoulder breathing with vocal emphasis.
Switching from DMD to OPSD halfway through the 8 step schedule suppresses compounding color drift across long multi chunk continuations.
Try LongCat-Video-Avatar 1.6 Live in the Browser
You can test LongCat-Video-Avatar 1.6 directly in the embedded Hugging Face Space below (victor-longcat-video-avatar-1-6.hf.space).
Hardware, Quantization, and Performance Matrix
| Precision / Port | Parameters | VRAM / Unified Memory | Sampling Schedule | Best Production Fit |
|---|---|---|---|---|
| Official BF16 Multi GPU | 13.6B DiT + encoders |
48 GB+ (or multi GPU CP) |
8 NFE (4 DMD + 4 OPSD) |
Studio render nodes, 10+ minute hero monologues |
Official INT8 DiT (--use_int8) |
13.6B (INT8 weight only) |
24 GB – 32 GB VRAM |
8 NFE (4 DMD + 4 OPSD) |
Single RTX 4090 / RTX 5090 workstation production |
Community Apple MLX (bf16) |
13.6B DiT |
64 GB+ Unified Memory |
8 NFE (4 DMD + 4 OPSD) |
Quiet local offline rendering on Mac Studio |
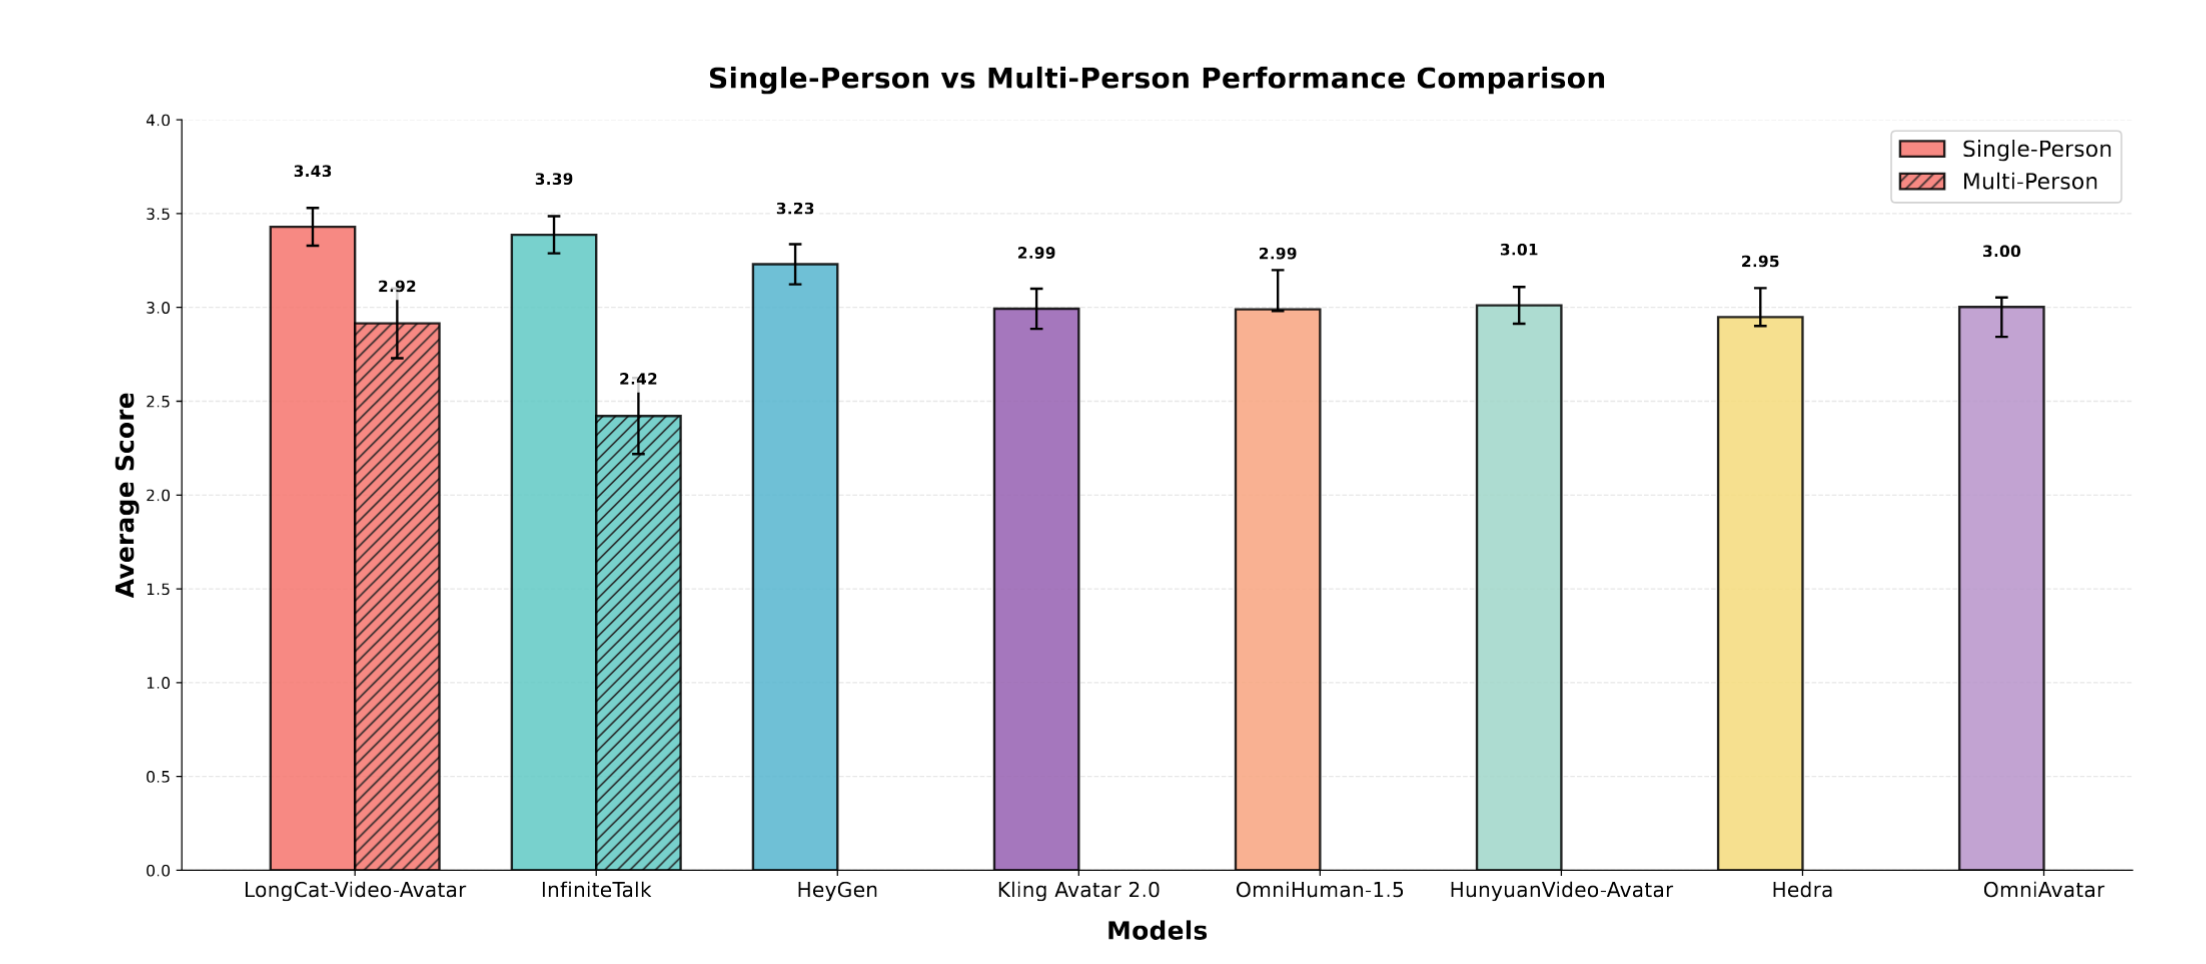
LongCat-Video-Avatar supports both single speaker dramatic close ups and multi person conversational staging, maintaining eye line accuracy and head turn naturalness across extended takes.
Filmmakers can drive the same character portrait with clean studio ADR, cloned voice takes from **Ming-3.0-tts** or **ZONOS3-Mini**, or multilingual dubbing tracks.
Visual fidelity and identity preservation across single and multi speaker avatar synthesis. Credit: Meituan LongCat.
Parameter Reference Table
| Flag | Recommended Default | Technical Role |
|---|---|---|
--num_inference_steps |
8 |
Standard distilled NFE budget for Version 1.6. |
--mix_steps |
4 |
Runs DMD + OPSD blend for the first 4 steps, then pure OPSD for the final 4 steps. |
--mix_alpha |
1.0 |
Weighting factor (mix_alpha * DMD + (1 - mix_alpha) * OPSD) during the initial steps. |
--use_int8 |
true (on 24 GB GPUs) |
Enables weight only INT8 DiT execution to fit on single consumer GPUs. |
--audio_cfg_scale |
3.5 – 4.5 |
Controls lip sync tightness; keep near 4.0 to avoid exaggerated mouth openings. |
Local Setup with Python and CLI
Download the LongCat-Video-Avatar-1.6 weights (including loraA DMD and loraB OPSD adapters) and run an 8 step INT8 inference pass:
git clone https://github.com/meituan-longcat/LongCat-Video.git
cd LongCat-Video
pip install -r requirements.txt

huggingface-cli download meituan-longcat/LongCat-Video-Avatar-1.6 \
  --local-dir ./weights/LongCat-Video-Avatar-1.6
python run_avatar.py \
  --checkpoint_dir ./weights/LongCat-Video-Avatar-1.6 \
  --reference_image ./cast/interviewer_closeup.png \
  --audio_path ./audio/monologue_01_48khz.wav \
  --prompt "Intimate 85mm documentary close up, subtle head nods, natural blinking, soft key light" \
  --num_inference_steps 8 \
  --mix_steps 4 \
  --mix_alpha 1.0 \
  --use_int8 \
  --output monologue_01_v16.mp4
Filmmaker Production Playbook
- Clean your dialogue track before running Whisper conditioning. High pass filter rumble below 80 Hz and strip heavy room reverb so
Whisper-large-v3locks onto true consonant transients instead of background noise. - Use
--mix_steps 4 --mix_alpha 1.0as your baseline. If a dramatic whisper scene shows slightly stiff micro motion, lower--mix_alphato0.85; if a 5 minute take shows slight lighting drift, keep--mix_alpha 1.0so OPSD dominates the late denoising steps. - Pair with local TTS for fast multilingual dubbing. Generate emotionally tagged dialogue tracks in Ming-3.0-tts or ZONOS3-Mini, then drive your locked character plate through LongCat-Video-Avatar 1.6 for localized festival trailers.
Related Reading
- LongCat-Video-Avatar 1.5: Open Source Lip Sync Guide
- Ming-3.0-tts: Open Source Voice Design & Cloning
- ZONOS3-Mini & Tiny-Voca: Open Source Voice Cloning TTS
- Viggle Remake & Animate: Open Source Character Video AI


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)