

Zyphra ZONOS3-Mini (arXiv:2611.16525, Apache 2.0) and n4ze3m Tiny-Voca (Apache 2.0)
Share this post:
ZONOS3-Mini & Tiny-Voca: Open Source Voice Cloning AI
ZONOS3-Mini (Zyphra/ZONOS3-Mini, arXiv:2611.16525) and Tiny-Voca (n4ze3m/tiny-voca) are two November 2026 Apache 2.0 open source text-to-speech releases that cover opposite ends of the filmmaking voice production spectrum. Released on November 9, 2026 and already downloaded more than 114,000 times on Hugging Face, Zyphra's ZONOS3-Mini delivers high fidelity zero shot voice cloning and emotional dialogue across 21 languages via SGLang-Omni and GGUF, while Tiny-Voca (released November 14, 2026) packs a complete English TTS and waveform generator into just 4.5M parameters running 70x faster than real time on 4 CPU threads.
Studio availability. ZONOS3-Mini and Tiny-Voca are not available in AI FILMS Studio. This article covers public open source releases from November 2026. To generate speech or clone voices in the Studio, open the voice workspace to run ElevenLabs Eleven V3 Text to Speech, MiniMax Speech 2.8 HD Text to Speech, or MiniMax Voice Clone, and animate dialogue on the Image to Video page.
ZONOS3-Mini Character Voice (Irish Male Acting Sample)
Zero-shot expressive character voice from ZONOS3-Mini GGUF preset bank (Apache 2.0).
Tiny-Voca 4.5M ONNX CPU Voice (70x Real-Time Female F2)
Generated on 4 CPU threads in ONNX with zero GPU memory required (Apache 2.0).
ZAC-1 Audio Codec Architecture vs 4.5M Parameter CPU ONNX
Previsualization editors and animation directors face two very different voice synthesis tasks during production. Table reads and animatics need instant scratch dialogue generated locally on a laptop without unloading a video diffusion model from GPU VRAM, while final localization and ADR require expressive voice cloning across multiple European and Slavic languages.
- ZAC-1 neural codec and 21-language autoregressive loop (
ZONOS3-Mini,arXiv:2611.16525). Zyphra'sZONOS3-Miniencodes reference speaker timbre and acoustic prosody through the customZAC-1neural audio codec, then predicts speech tokens in a low latency autoregressive loop. Supporting 21 languages (en,fr,es,de,it,pt,nl,pl,ru,sv,tr,uk,cs,da,fi,el,hu,no,ro,sk), it includes prebuilt character voices (such as Irish, British, American, whispered ASMR, and dramatic announcer presets) and runs natively inSGLang-Omnior quantizedGGUF. - 4.5M parameter end to end CPU synthesis (
Tiny-Voca). Created byn4ze3mand paired with the customdizionephonemizer (n4ze3m/dizione),Tiny-Vocatrains a compact 4.5 million parameter acoustic and waveform model from scratch on 18 hours of clean synthetic speech (F2female andM2male voices). Exported toONNX, it synthesizes a 10 second dialogue line in roughly140 millisecondson four standard CPU cores (70xfaster than real time). - Unrestricted Apache 2.0 commercial licensing. Both
Zyphra/ZONOS3-Miniandn4ze3m/tiny-vocaship under the Apache 2.0 license, allowing indie filmmakers and game cutscene teams to ship generated dialogue commercially.
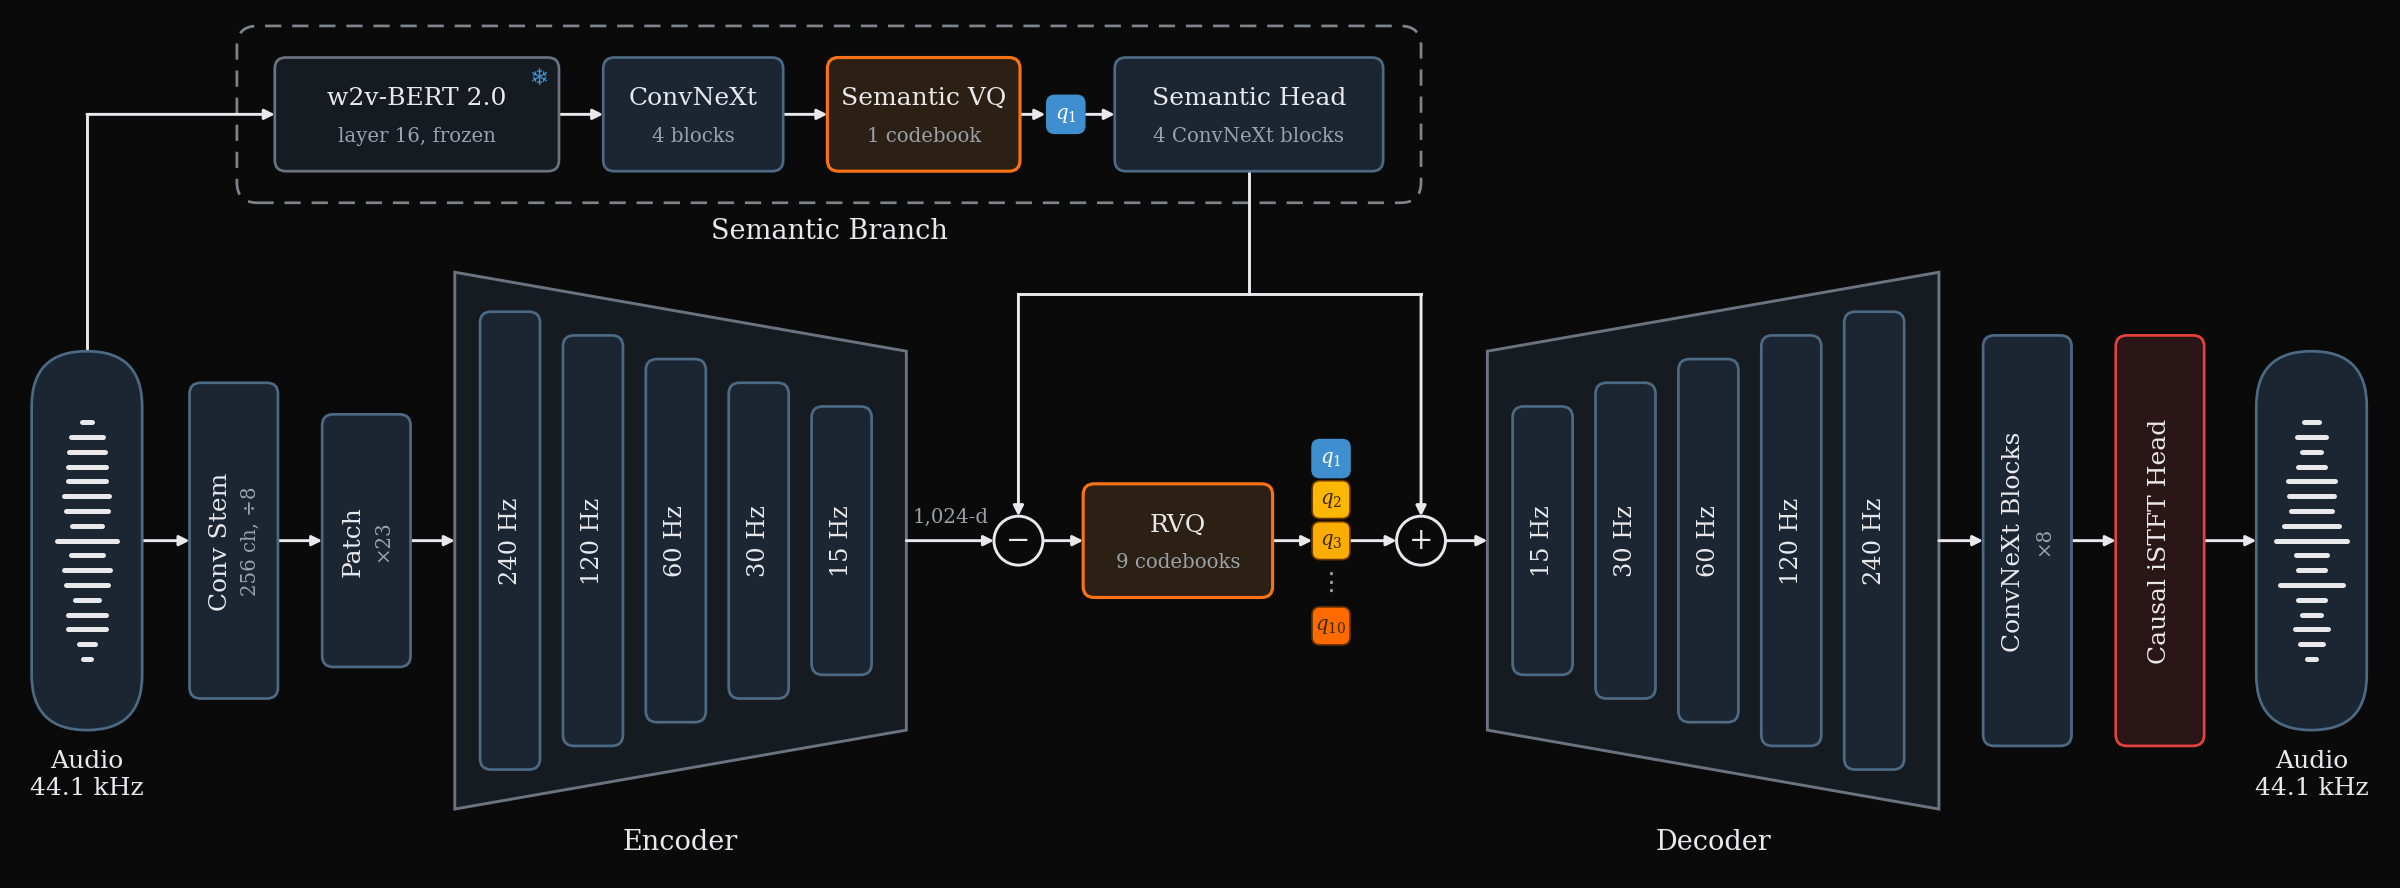
ZONOS3-Mini architecture combining the ZAC-1 audio codec with autoregressive speech token modeling. Credit: Zyphra (Apache 2.0).
Decoupling acoustic tokenization inside `ZAC-1` lets `ZONOS3-Mini` clone a performer's vocal timbre from a brief 5 to 10 second reference clip while shifting delivery style from whispered tension to energetic projection.
When served through `SGLang-Omni`, the model exposes an OpenAI compatible `/v1/audio/speech` endpoint for automated script-to-animatic batch rendering.
Try ZONOS3-Mini and Tiny-Voca Studio Live in the Browser
Both official Hugging Face Spaces are active and embeddable below without login. Test ZONOS3-Mini zero shot voice cloning in the first Space, or test Tiny-Voca Studio instant CPU synthesis in the second Space.
On the quality versus speed Pareto frontier (`arXiv:2611.16525`), `ZONOS3-Mini` matches or beats significantly larger open weights TTS models on speaker similarity and word error rate while running at a fraction of their latency.
Because `ZONOS3-Mini` also ships a `gguf/` directory alongside WebGPU and `SGLang-Omni` runners, dialogue tracks can be generated on consumer GPUs or Apple Silicon laptops.
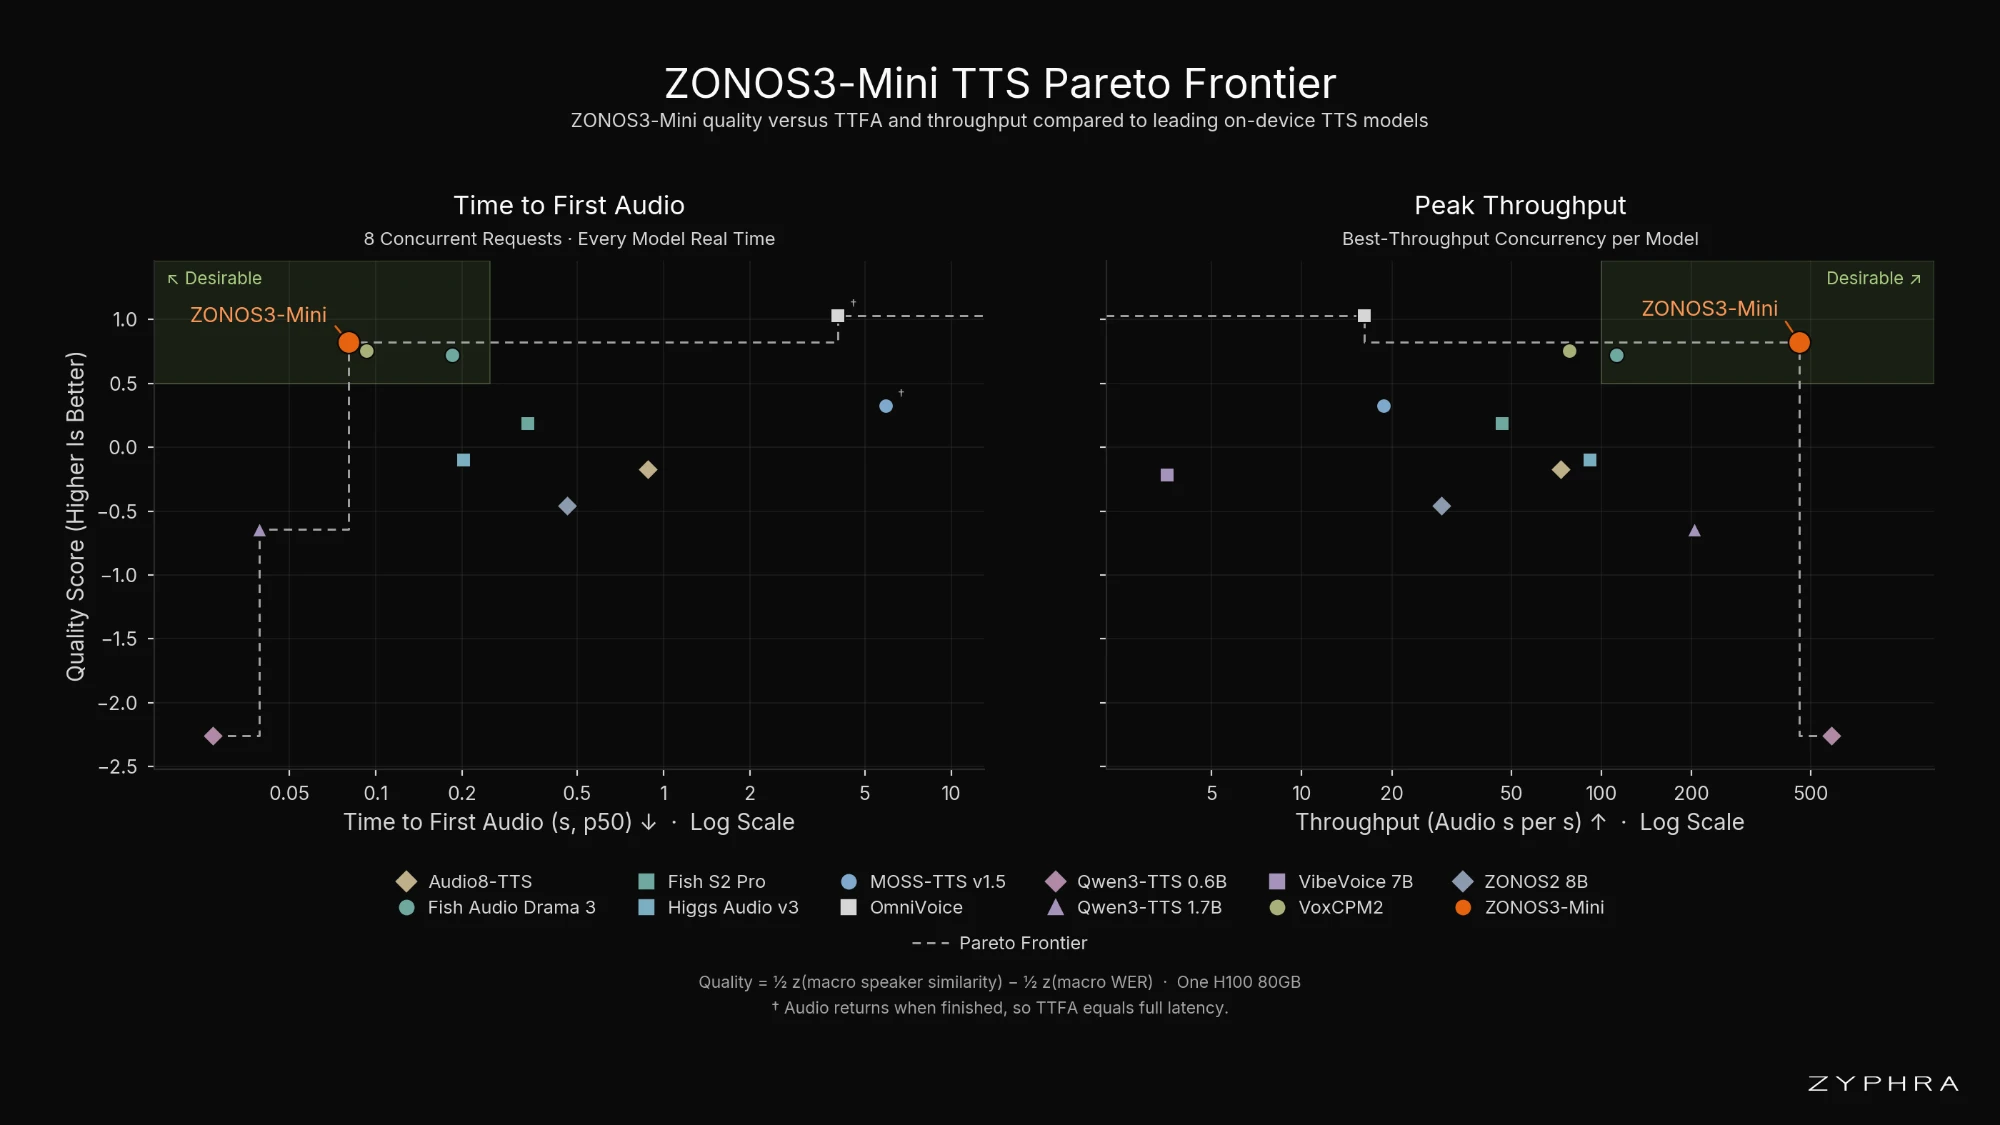
ZONOS3-Mini quality vs speed Pareto frontier across open source TTS models. Credit: Zyphra (arXiv:2611.16525) (Apache 2.0).
Model Specs, Languages & Hardware Matrix
| Model | Hugging Face ID | Parameters & Format | Languages & Voices | Hardware & Speed | License |
|---|---|---|---|---|---|
ZONOS3-Mini (arXiv:2611.16525) |
Zyphra/ZONOS3-Mini |
Compact AR + ZAC-1 Codec (BF16 & GGUF) |
21 languages + zero shot voice cloning | 6 GB to 12 GB VRAM (SGLang-Omni / GGUF) |
Apache 2.0 |
Tiny-Voca |
n4ze3m/tiny-voca |
4.5M parameters (ONNX + dizione) |
English (F2 female, M2 male) |
CPU only (4 threads, 70x real time) |
Apache 2.0 |
Fish Audio Drama-3 |
fishaudio/drama-3 |
Multi speaker dialogue TTS | Multi turn emotional script dialogue | 12 GB to 16 GB VRAM | Open Weights |
Kokoro-82M |
hexgrad/Kokoro-82M |
82M StyleTTS2 ONNX/PyTorch |
Multi language fast voice presets | CPU or 2 GB VRAM | Apache 2.0 |
Running ZONOS3-Mini (SGLang-Omni) and Tiny-Voca Locally
To serve Zyphra/ZONOS3-Mini locally behind an OpenAI compatible endpoint on NVIDIA GPUs, install sglang-omni and launch the server.
# Install SGLang-Omni and download Zyphra/ZONOS3-Mini (Apache 2.0)
git clone https://github.com/sgl-project/sglang-omni.git
cd sglang-omni
pip install -e .

huggingface-cli download Zyphra/ZONOS3-Mini --local-dir ./models/ZONOS3-Mini

# Launch OpenAI-compatible ZONOS3-Mini voice cloning server
python -m sglang_omni.launch_server \
  --model-path ./models/ZONOS3-Mini \
  --port 8000
Query the local server or clone a character voice from one of the bundled gguf/voices/ reference .wav files.
curl http://localhost:8000/v1/audio/speech \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Zyphra/ZONOS3-Mini",
    "input": "We only have thirty seconds before the blast doors seal the corridor.",
    "voice": "Cillian_en-Irish_M_1"
  }' \
  --output dialogue_line.wav
To run Tiny-Voca on a CPU only laptop at 70x real time for storyboard scratch tracks, clone n4ze3m/tiny-voca.
git clone https://github.com/n4ze3m/tiny-voca.git
cd tiny-voca
pip install -r requirements.txt

# Synthesize English scratch dialogue on 4 CPU threads via ONNX
python infer.py \
  --text "Camera two pushes in on the detective as the rain starts." \
  --voice F2 \
  --threads 4 \
  --output scratch_f2.wav
Production Playbook for Filmmakers
- Keep GPU VRAM free during animatics with
Tiny-Voca. When your GPU is occupied runningWan 2.2,MiniMax-H3, orFLUX.2, runTiny-Vocaon 4 CPU threads to generate timing accurate scratch dialogue for every storyboard panel in milliseconds. - Use
ZONOS3-Minifor 21-language dubbing and lip sync drivers. Feed clonedZONOS3-Minidialogue.wavtracks directly into audio-driven lip sync models such as LatentSync 1.6 and MuseTalk 1.5, JoyVASA portrait animation, or Kandinsky S2V 1.0. - Compare across open source voice models. Explore our related voice guides on Fish Audio Drama-3 multi-speaker dialogue TTS, Qwen3-TTS, F5-TTS, Chatterbox, and Kokoro voice cloning, and Bark TTS, Voicebox, and InSwapper.
To generate broadcast dialogue or clone voices in the cloud without local setup, open the voice workspace or wire voice nodes directly into lip sync and video nodes inside the Nodes Graph Editor.


Sources
- Zyphra/ZONOS3-Mini Official Model Card & Weights on Hugging Face (Apache 2.0)
- ZONOS3-Mini Technical Report (arXiv:2611.16525)
- Zyphra/ZONOS3-Mini Interactive Space on Hugging Face
- n4ze3m/tiny-voca Official GitHub Repository (Apache 2.0)
- n4ze3m/tiny-voca ONNX Model Card on Hugging Face
- n4ze3m/tiny-voca-studio Interactive Space on Hugging Face
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)