

Verified 4-step 736x1280 sample poster by NVLabs SANA Team (Apache 2.0)
Share this post:
SANA-Video 2.0 5B: Open Source 4 Step 720p Video
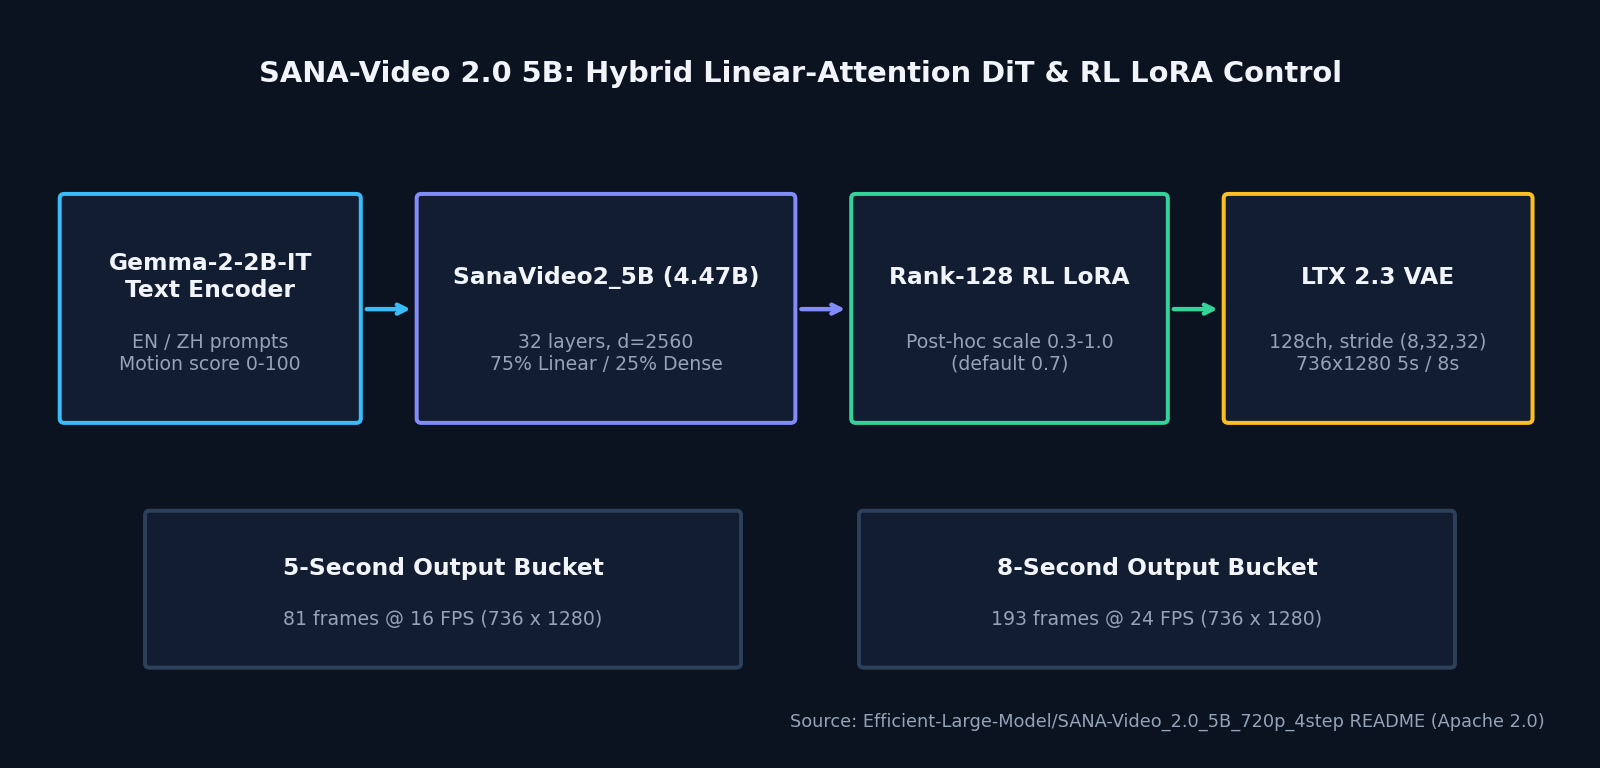
Full 50 step video diffusion models burn minutes per prompt, making rapid shot ideation painful on local hardware. SANA-Video 2.0 5B 4-Step Preview (Efficient-Large-Model/SANA-Video_2.0_5B_720p_4step), released by the NVLabs SANA team under Apache 2.0, condenses high resolution 736x1280 text-to-video generation into four velocity prediction stages at CFG 1.0. Pairing a 4.47B hybrid linear attention transformer with the LTX 2.3 latent VAE and a post hoc rank 128 RL LoRA slider, it renders 5 second (16 FPS) or 8 second (24 FPS) clips quickly on a single GPU.
Studio availability. Try the public Hugging Face demo below; SANA-Video 2.0 5B is not part of a paid AI FILMS Studio plan (use LTX-2.3 Text to Video in the video workspace for example instead).
Try SANA-Video 2.0 5B Live
Generate 5 second or 8 second 720p clips directly in the official NVLabs Hugging Face Space below. Test the Motion Score slider (0 to 100) and RL LoRA scale (0.3 to 1.0) to dial in camera energy and prompt adherence.
Architecture and Technical Design
SanaVideo2_5B contains 4,466,980,960 parameters across 32 transformer layers with hidden dimension 2,560. Instead of paying quadratic dense attention cost at every layer, 75% of layers use gated bidirectional linear attention while 25% act as periodic dense softmax attention anchors, reinforced by shared Attention Residual aggregation every 8 layers. Text prompts in English or Chinese run through google/gemma-2-2b-it, and video latents decode through the LTX 2.3 VAE (128 latent channels, temporal spatial stride 8, 32, 32).
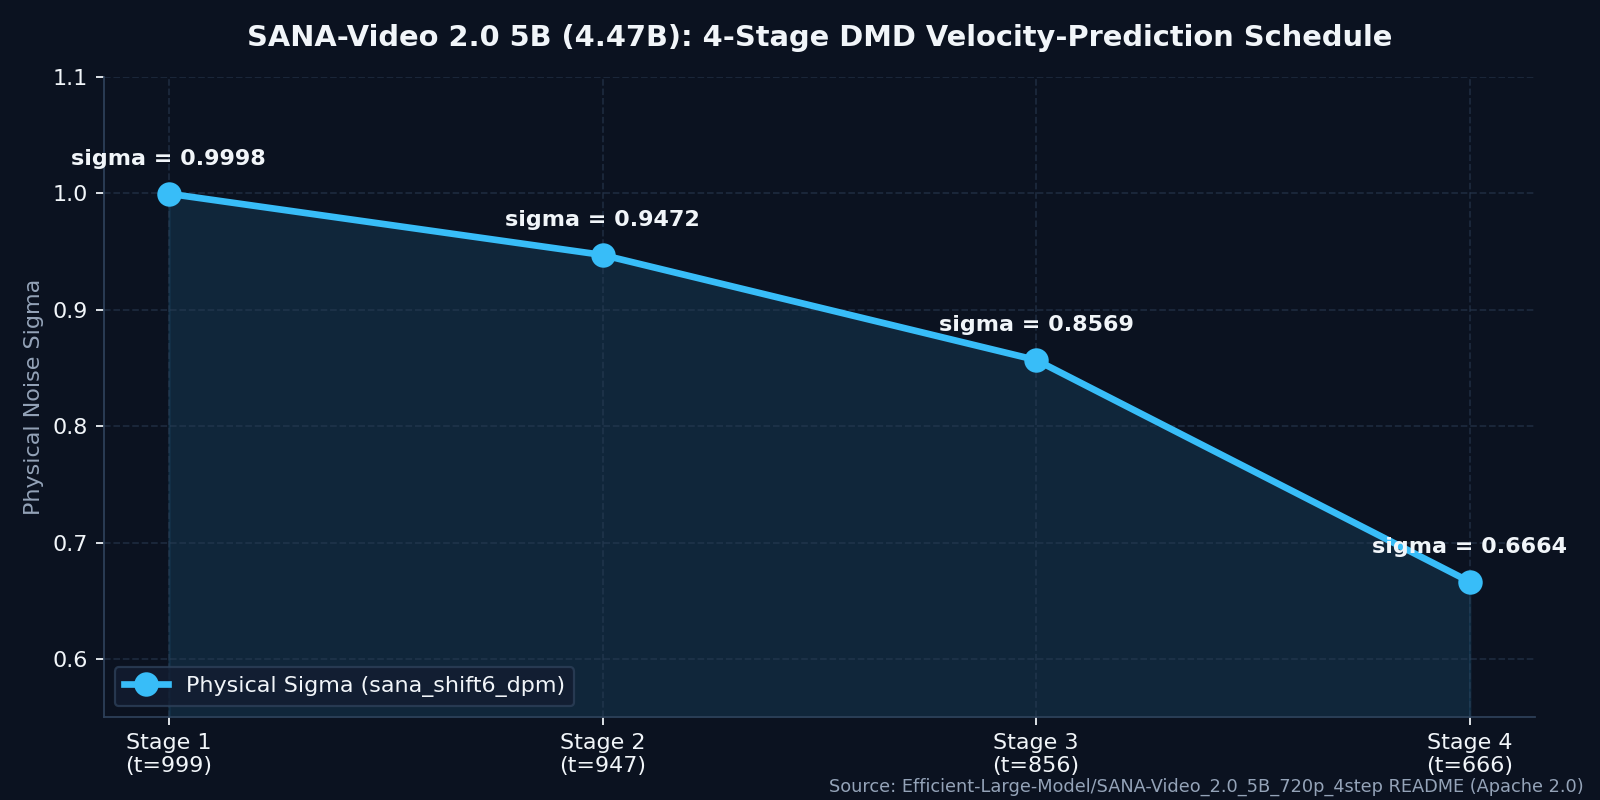
AI FILMS schedule chart from SANA-Video 2.0 5B README (Apache 2.0)
This 4 step preview is a full model tri-temporal Distribution Matching Distillation (DMD) EMA export initialized from the SFT model after merging a ReFL step 500 adapter. Rather than truncating a standard DPM solver, each stage predicts velocity v at fixed physical sigmas (0.9998, 0.9472, 0.8569, 0.6664), computes x0, and re-noises for the next stage.
A separate rank 128 RL LoRA file lets users adjust reinforcement learning strength between 0.3 and 1.0 around the base checkpoint without reloading weights or accumulating rounding error.
Hardware, VRAM, and License Matrix
| Checkpoint Variant | Task Support | Steps & CFG | Output Buckets | License | Typical VRAM (BF16) |
|---|---|---|---|---|---|
SANA-Video_2.0_5B_720p_4step |
Text-to-video only | 4 stages, CFG 1.0 | 736x1280 (81f @ 16 FPS / 193f @ 24 FPS) | Apache 2.0 | ~16 to 24 GB |
SANA-Video_2.0_5B_720p (Base) |
T2V + TI2V (first frame) | 50 steps | 736x1280 | Apache 2.0 | ~16 to 24 GB |
RL500_LoRA_rank128.pt |
Auxiliary RL strength control | Post hoc merge (0.3 to 1.0) |
Matches 4 step model | Apache 2.0 | Negligible overhead |
All checkpoints, configs, and inference code ship under the permissive Apache 2.0 license, enabling unrestricted local commercial previsualization, fine tuning, and studio pipeline integration.
Parameter Reference
| Parameter | Default / Range | Filmmaker Tuning Tip |
|---|---|---|
step |
4 (fastvideo_dmd_4step) |
Fixed 4 stage DMD rollout; do not change to arbitrary step counts |
cfg_scale |
1.0 |
Guidance free distillation; keep strictly at 1.0 |
motion_score |
20 (range 0 to 100) |
Raise to 40 to 60 for energetic camera tracks or character action |
rl_lora_scale |
0.7 in Space (1.0 native) |
Lower scales (0.4 to 0.6) yield softer cinematic textures; 0.8 to 1.0 boosts prompt lock |
num_frames / fps |
81 @ 16 FPS (5s) or 193 @ 24 FPS (8s) |
Use 193 frames at 24 FPS for standard cinema timeline rhythm |
custom_height_width |
[736, 1280] |
Native 720p widescreen bucket for cleanest spatial coherence |
Local Python and CLI Setup
Clone the official NVlabs/Sana repository, place the Diffusers format LTX 2.3 VAE under output/pretrained_models/LTX-2.3-Diffusers/, and run the 4 step CLI script.
git clone https://github.com/NVlabs/Sana.git
cd Sana
bash environment_setup.sh sana
conda activate sana

bash inference_video_scripts/inference_sana_video.sh \
  --np 1 \
  --config configs/sana_video2/SanaVideo2_5B_720p.yaml \
  --model_path hf://Efficient-Large-Model/SANA-Video_2.0_5B_720p_4step/checkpoints/SANA_Video_2.0_5B_720p_4step.pth \
  --txt_file=asset/samples/sana_video2_5b_720p_demo.txt \
  --task=t2v \
  --model.image_size=480 \
  --custom_height_width='[736,1280]' \
  --sampling_algo=fastvideo_dmd_4step \
  --generator_sigma_profile=sana_shift6_dpm \
  --cfg_scale=1.0 \
  --motion_score=20 \
  --num_frames=81 \
  --step=4 \
  --fps=16 \
  --seed=4 \
  --work_dir output/sana_video2_4step
You can also script rapid prompt sweeps directly against the Space API via gradio_client while evaluating motion scores before downloading full weights locally.
Filmmaker Production Playbook
1. Audition 24 FPS shot timing in four steps. Because SANA-Video 2.0 5B supports a native 193 frame, 24 FPS 8 second output bucket at 736x1280, editors can generate rough motion animatics directly at film frame rate without frame blending or speed ramps.
2. Sweep RL LoRA scale instead of rewriting prompts. When a 4 step clip looks slightly over sharpened or too static, hold your seed fixed and step rl_lora_scale from 1.0 down to 0.5 while bumping motion_score from 20 to 45.
AI FILMS architecture diagram from SANA-Video 2.0 5B README (Apache 2.0)
- Switch to the 50 step base checkpoint for first frame conditioning. The 4 step preview is strictly text-to-video. Whenever a scene requires locking onto an approved concept art still, use the sibling 50 step
SANA-Video_2.0_5B_720pcheckpoint or run LTX-2.3 Text to Video and LTX-2.3 Image to Video on our text to video page in the video workspace.
Related Reading
- LTX-2.3: Open Source 22B Video Model, Distilled & LoRA
- FastWan-QAD: Ultrafast Open Source Video Generation
- Wan Alpha: Text to Video with a True Alpha Channel
- SANA Video: Small Fast Text to Video with Linear Attention


Sources
Continue Reading


Video & LipSync
- Video Generator
- Text to Video
- Image to Video
- Start-End Frame to Video
- Draw to Video
- Motion Control
- Video Enhancer
- Video Upscaler
- Video Extend
- Video to Video LipSync
- Audio to Video LipSync
- Image to Video LipSync
- Video FaceSwap
- Seedance 2.5
- WAN 3.0
- Seedance 2
- FLUX 3
- Minimax H3
- Vidu Q3 Pro
- Grok Imagine Video 1.5
- Gemini Omni
- Google Veo 3.1
- Kling 3.0 Pro
- Luma Ray 3.2
- LTX 2.3
- Happy Horse 1.1
- Kling 3.0 Motion
- ByteDance Upscaler
- InfiniteTalk
- InsightFace
Image & Edit
- AI Character
- AI Actor
- Art Generator
- Text to Image
- Image to Image
- LoRA Image to Image
- Draw to Edit
- Image LoRA Training
- Remove Background
- Image Enhancer
- MidJourney 8.0
- Krea 2
- OpenAI GPT Image 2.0
- Nano Banana Pro Ultra
- Nano Banana 2 Lite
- Nano Banana Pro
- Minimax Image
- Clarity Pro
- Z-Image Turbo LoRA
- Krea 2 Turbo LoRA
- Z-Image LoRA Trainer
- Qwen Image LoRA Trainer
- Background Erase Network 2 (BEN2)